

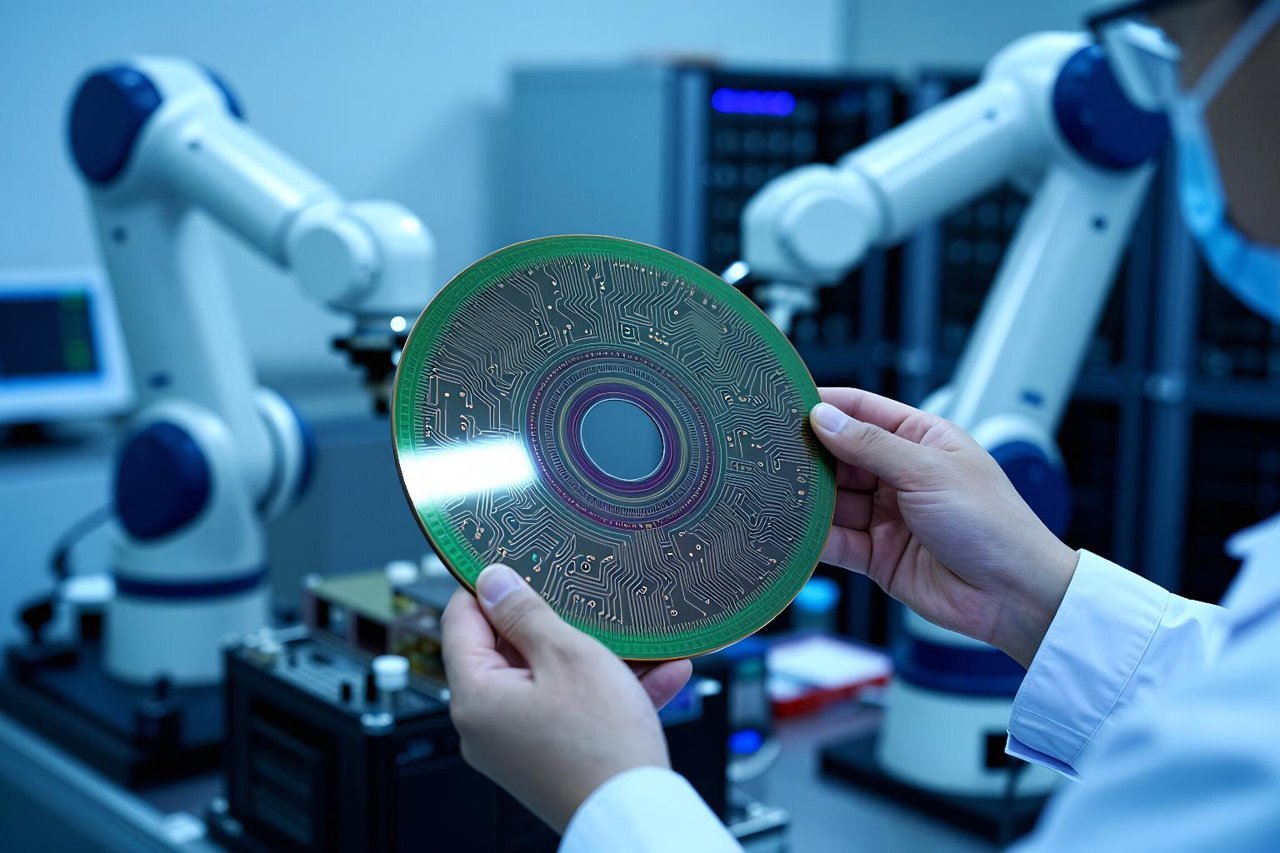
In early 2026, Cerebras Systems pulled off one of the biggest tech IPOs in years. The company raised $5.5 billion and watched its stock soar 108% on day one. That kind of debut doesn’t happen by accident. It’s the payoff from a decade-long bet on a radical idea: instead of making chips smaller, make them enormous.
But what exactly does Cerebras do? And why are investors so excited? The answer lies in a piece of silicon the size of a dinner plate.
The Wafer-Scale Engine: A Chip the Size of a Dinner Plate
Most computer chips are cut from a silicon wafer into dozens or hundreds of tiny dies. Cerebras takes a different approach. It keeps the entire wafer intact, creating a single chip that measures about 8.5 inches by 8.5 inches. The latest version, the Wafer-Scale Engine 3 (WSE-3), packs 4 trillion transistors and 900,000 AI-optimized cores. Nvidia’s H100, by comparison, has 80 billion transistors. That’s a 50-fold difference in transistor count.
Why does size matter? AI training is largely a memory problem. Moving data between processors and memory eats up time and energy. Cerebras solved this by putting 44 gigabytes of on-chip SRAM right next to the compute cores. That delivers 21 petabytes per second of memory bandwidth—thousands of times faster than off-chip memory. The result: models train faster, and you need fewer chips to do the job.
How It Works in Practice
Cerebras sells complete systems, like the CS-3, which can be clustered together to form supercomputers. They also offer a cloud service where companies can rent time on their hardware. G42, a UAE-based AI firm, has built massive clusters using Cerebras chips. And OpenAI has been a high-profile partner, a relationship that has only fueled speculation about Cerebras’s market potential. As one report noted, OpenAI’s cozy partner Cerebras is on track for a blockbuster IPO.
Software That Makes It Usable
Hardware is only half the battle. Cerebras built a software stack that compiles AI models onto its giant chip without requiring developers to rewrite their code. The compiler handles the tricky part: mapping billions of parameters onto 900,000 cores. That’s a big deal because most AI teams don’t have the time or expertise to optimize for exotic hardware. Cerebras makes it feel almost like using a standard GPU cluster, just faster.
Cerebras vs. Nvidia: A Different Approach to AI Compute
Nvidia dominates AI training with its GPUs, which are general-purpose chips that excel at parallel math. Cerebras doesn’t compete on the same terms. Its wafer-scale engine is purpose-built for the massive matrix multiplications that power neural networks. For certain workloads, especially large language models, Cerebras can train models in a fraction of the time.
But Nvidia has an ecosystem advantage that’s hard to overstate. Its CUDA platform has been refined for over 15 years, and virtually every AI researcher knows how to use it. Cerebras has to convince customers that switching is worth the effort. So far, it’s found willing buyers in research labs, national supercomputing centers, and companies with extreme compute needs.
From Startup to Wall Street: The Money Trail
Cerebras was founded in 2016 by Andrew Feldman and a team of engineers from SeaMicro, a server company that AMD acquired. They spent years in stealth, building the first wafer-scale chip and convincing investors that the approach could work. In 2024, the company filed for its IPO, a move that signaled its ambition to go public.
Then came 2026. Cerebras raised $5.5 billion and saw its stock pop 108% on the first day of trading. It was the first huge tech IPO of the year, and it instantly made Cerebras a household name in AI circles. The details of that wild ride are covered in Cerebras raises $5.5B, then stock pops 108%, in the first huge tech IPO of 2026.
The Investor Angle: Why VCs Are Watching
Cerebras’s success has turned heads in the venture capital world. Early investors like Eclipse Ventures saw a $2.5 billion win from their bet on the company. That kind of return validates the thesis that AI compute is a massive market. Eclipse’s win is just the start of its physical-world thesis, according to For Eclipse, the $2.5B Cerebras win is just the start of realizing its physical-world thesis.
And it’s not just about money. Talent matters too. Adit Singh, an early Cerebras investor, recently joined Mayfield as an infrastructure partner. His move shows how Cerebras alumni and backers are shaping the next wave of AI investing. You can read more about that in Early Cerebras investor Adit Singh joins Mayfield as infrastructure partner.
The Hunt for the Next Cerebras
With Cerebras proving that wafer-scale chips can work—and that they can generate huge returns—investors are now hunting for the next big thing in AI compute. The question on everyone’s mind: who will be the next Cerebras? That hunt is already underway, as explored in Has the hunt for AI compute uncovered the next Cerebras?.
Several startups are trying to challenge Nvidia’s dominance, but Cerebras remains the most visible alternative. Its technology is not just faster for certain workloads; it’s a fundamentally different architecture. That difference could become even more important as AI models grow larger and demand more efficient training.
Here are a few key facts that sum up Cerebras’s position:
- Wafer-scale design: One giant chip instead of many small ones.
- Massive memory bandwidth: 21 PB/s on-chip, eliminating a major bottleneck.
- Proven at scale: Deployed in supercomputers and cloud services.
- Public market success: $5.5B raised, 108% first-day pop.
- Investor confidence: Early backers seeing billion-dollar returns.
As AI continues to demand more compute, Cerebras has positioned itself as a serious contender. Whether it becomes the Nvidia of the 2030s or a specialized player, its impact on the industry is already undeniable. The company’s journey from a risky bet to a public powerhouse is a story worth watching.