

Cerebras Systems builds the strangest piece of silicon in commercial computing. Its flagship chip is a single square of silicon roughly 21 centimetres on a side, big enough to double as a serving tray and about 57 times the area of an Nvidia H100 die. Almost everything else about the company, from the shape of its data centre racks to the way it talks to investors, follows from that one decision.
The company was founded in Los Altos in 2015 by engineers who had previously built SeaMicro and sold it to AMD. Four years passed before they showed anyone a working part, a gap long enough that plenty of people in the industry assumed the whole project was a publicity stunt.
Why Cerebras refuses to cut the wafer up
Chip manufacturing runs on a simple economic rule. A silicon wafer gets printed with hundreds of identical dies, then sliced apart. Any die that lands on a speck of dust or a crystal defect is thrown away. Because defects are unavoidable, the industry keeps dies small so that a single flaw ruins only a few dollars of silicon.
Cerebras went the other way. Its Wafer-Scale Engine is one die that uses the entire wafer, so a defect can’t simply be tossed out. It has to be routed around. The current generation, WSE-3, crams 900,000 compute cores onto TSMC’s 5-nanometre process, and the on-chip network steers work away from whichever cores come back faulty.
The headline numbers are odd even by AI hardware standards:
- 4 trillion transistors, against roughly 80 billion on an H100
- 900,000 cores sharing 44 GB of on-chip SRAM
- Memory bandwidth on the order of 21 petabytes per second
That last figure matters most. Most AI accelerators spend their working lives waiting. Model weights live in off-chip HBM, and every layer of computation has to fetch them across a relatively slow connection. Cerebras keeps the weights in SRAM on the same slab of silicon as the arithmetic units, so the fetch mostly disappears. It’s the reason the company ended up with a dinner-plate-sized chip instead of the familiar palm-sized accelerator.
The pitch is speed, not size
Cerebras doesn’t really sell training clusters designed to out-muscle Nvidia at scale. It sells latency. On its own cloud service, Llama 3.1 70B generates around 2,100 tokens per second, and Meta’s larger Llama 4 Scout runs at roughly 2,600. GPU clouds typically manage a few dozen tokens per second at that size, sometimes a couple of hundred with aggressive optimisation.
Move the number by an order of magnitude and some products stop being awkward and start being obvious:
- Agentic loops that call a model thirty times to finish one task, where every millisecond multiplies
- Voice interfaces that need to reply before the silence feels uncomfortable
- Reasoning models that burn through thousands of thinking tokens before answering
- Code completion inside an editor, where a two-second pause breaks concentration
Pricing matters as much as raw speed here. Cerebras has been willing to quote per-token rates that undercut the big GPU clouds on open-weight models, which turns the question from whether the hardware is impressive into whether serving on it is cheaper.
A customer list that made regulators pay attention
For a while, Cerebras had one customer that mattered more than all the others combined. G42, the Abu Dhabi-based AI group, accounted for roughly 87% of revenue in the first half of 2024, largely through the Condor Galaxy supercomputer build-outs the two companies ran together. That concentration drew scrutiny from the Committee on Foreign Investment in the United States, and G42 eventually agreed to give up its stake in Cerebras to clear the path.
Then came a bigger name. The company became OpenAI’s cozy partner in a deal reported at more than $10 billion, covering hundreds of megawatts of inference capacity. Whatever the final contract looks like, the signal was loud: OpenAI wanted a second source of fast silicon, and it wasn’t going to get that from Nvidia alone.
From a withdrawn filing to a 2026 listing
The public markets took a while to get there. Cerebras filed its S-1 in September 2024, pulled the paperwork a year later as the G42 situation and various reviews dragged on, and instead raised $1.1 billion in a Series G that valued the business around $8.1 billion.
The eventual listing went very differently. The company raised $5.5 billion and watched the stock pop 108% on its first day, making it the marquee tech offering of 2026. A withdrawn filing followed by a triple-digit first-day jump is a fairly efficient summary of how far investor sentiment around AI infrastructure travelled in eighteen months.
Robots, simulation, and the physical-world case
Chatbots were the easy demonstration, not the end goal. Fast inference matters just as much for systems that have to act on the physical world, where a control loop running at tens of hertz can’t wait on a distant GPU cluster. That’s the thinking behind the $2.5B Cerebras win that investors framed as the opening move in a much larger bet on robotics, simulation and industrial autonomy.
What still stands in the way
The CUDA problem
Nvidia’s real advantage was never the transistor count. It’s CUDA, plus the decade of libraries, compilers and developer habits built on top of it. Cerebras has to win over teams who have already written their training and serving code for GPUs, and every migration carries risk, cost and a hiring problem. Groq, SambaNova and Google’s TPUs are chasing the same latency-sensitive buyers, and the hyperscalers would rather build their own silicon than buy anyone else’s.
Power, wafers and cooling
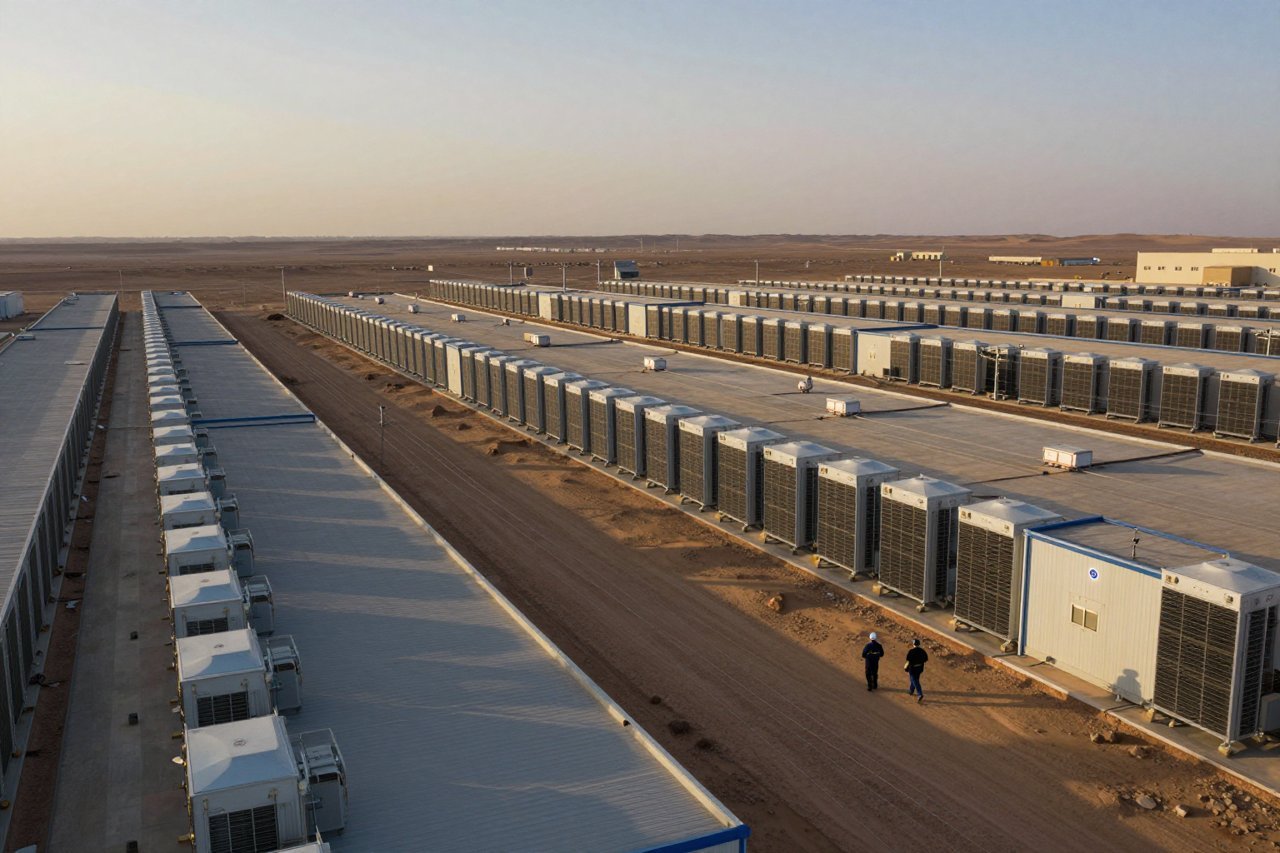
Physics pushes back too. A wafer-scale engine needs a wafer, and TSMC has finite capacity for the large-format parts. A CS-3 system draws roughly 23 kilowatts, which is why the Condor Galaxy sites were as much an electrical infrastructure project as a computing one. Speed is easy to demo and expensive to deliver at gigawatt scale.
The AI question wafer-scale silicon doesn’t answer
There’s a useful distinction to keep in mind when reading breathless coverage of any AI chip company. Being fast at inference is not the same as building general AI, and the two get tangled together constantly. Cerebras is solving a throughput and latency problem. The broader research question about machines that generalise across any task is separate, and no amount of on-chip SRAM settles it.
What the company has done is rarer than it looks. It took a manufacturing rule that everyone treated as fixed, broke it deliberately, and turned the result into something customers will pay for. Whether wafer-scale becomes the default way AI inference runs, or stays a fast, power-hungry niche for the workloads that genuinely need it, is the question the next few years of earnings reports will answer.