

There’s a category error that shows up in many LLM systems: We retrieve a few documents, put them in context, generate a fluent answer with links, and then we call the answer “grounded.”
That’s often useful, but it’s hardly enough in real life when you’re trying to show real evidence for your claims and not just documents that make them more plausible.
Retrieval gives a model access to candidates for evidence. But it doesn’t prove that a retrieved passage supports a claim it just made. A retrieved passage can be stale or incomplete. It can be topically similar but non-entailing. It can conflict with another source, be untrusted, or even maliciously injected.
I’m not arguing against Retrieval-Augmented Generation (RAG) itself. It’s a wonderful technology and extremely useful – however, I’m arguing against treating retrieval as an oracle of truth. The original RAG paper showed why retrieval is valuable for knowledge intensive generation, and it also identified provenance as an open problem.
The post-RAG engineering objective thus has to be stronger than “RAG with citations.” The real objective is an evidence-grounded narrative system. This means: every material proposition gets inspectable support, every important business decision coming from this system becomes traceable, and uncertainty gets a first-class representation.
If we only optimize the answer itself, we get fluent output – which is basically the state of AI today. But if we optimize the evidence system, we get an artifact that a developer or a debugger can actually inspect.
A new unit of control: Claims, not documents
The unit of control of a RAG is documents. And don’t get me wrong: Linking to source documents behind AI-generated claims is really useful.
But if we want to get down to the nitty-gritty and inspect each claim at its most fundamental level, we need a new unit of control: the atomic claim.
Before we ask a model to realize polished prose, we want it to produce a claim ledger. An atomic claim is the smallest unit of this ledger. The ledger contains a list of all atomic claims that the system intends to publish, together with the evidence and controls attached to each proposition.
Some minimal requirements of such a claims ledger (rather than a long unstructured list of documents) are these:
-
A stable
claim_id. -
The claim text, and the exact text span in the draft where that claim appears.
-
One or more verbatim evidence spans, not just a document title or a URL.
-
A canonical source or document ID where the claim appears, an immutable snapshot or content hash, and the time at which the evidence was accessed.
-
The retrieval and re-ranking context: which query produced the evidence, which index or corpus version was used, and which candidate sources were considered?
-
A support decision: directly supported, permitted synthesis, insufficient evidence, conflicting evidence, or unsupported.
-
Authority and currency fields, uncertainty, model and prompt versions, and a reviewer state.
That’s a lot of demands, and it may sound a little bit bureaucratic. It isn’t.
It’s how we turn a sentence from an opaque model artifact into an inspectable technical object. A source link is useful, but a claim-to-evidence graph is operable.
The non-negotiable publication gate
Here is the rule I would put at the centre of the system: A material claim without acceptable support is not a weakly grounded claim. It’s a request to do one of four things:
-
revise the claim,
-
abstain,
-
label it explicitly as inference, or
-
escalate it to a reviewer (human or model).
If we implement this rule, it forces a product decision: should the system prefer unsupported fluency or visible uncertainty?
For any workflow where a reader may act on the narrative (and especially if that action may carry real stakes), I would rather ship a visible ‘insufficient evidence’ state than an elegant sentence with a decorative citation.
At this point, we need to define policy before measuring anything: What counts as an atomic claim? What counts as direct support? When is synthesis permissible? How do we handle conflicts? Which claims are material? When does a claim need an expert reviewer?
These are not implementation details. They determine what our precision, recall, coverage and abstention metrics will mean.
If we don’t define the policy first, our evaluation numbers just become precise answers to an undefined question.
A truth-building architecture
Here’s the architecture to make this actually happen. It’s fairly simple, linear, and comprised of six layers.
1. Source admission and immutable capture. Before content enters an index, source authority is established, as well as currency permissions and a stable snapshot or hash.
2. Retrieval and re-ranking. The output is not some context – it’s an allowlist of source IDs and exact evidence spans that the generator is allowed to use.
3. Claim ledger production and draft realization. The model proposes atomic claims, connects them to evidence records, records uncertainty, and only then realizes readable prose.
4. Support and policy checks. Support, completeness, source rules, conflict handling, and the system’s compliance with claim policy all get tested here.
5. Risk-based review. A human can approve, revise, request evidence, choose abstention, or stop release.
6. Release, manifest, and trace. The evidence bundle, evaluation results, system versions, approval and rollback targets are preserved here.
The key difference to a regular RAG is that sources are pre-approved and not just dumped in a database; that uncertainty on claims is assessed explicitly; and that human review is a key part of the architecture.
That last part – human review – marks a classical departure from classical software design, where humans stood right at the end of the chain as users. However, when dealing with non-deterministic AI systems in environments where truthfulness is paramount, this human-in-the-loop design is necessary.
Binding the generator to evidence
The simplest technical error is letting the generator mint arbitrary citations. If my generation prompt lets the model emit any URL string that looks plausible, I have created a citation renderer, not a citation control. This danger is inherent in RAGs also.
To mitigate this, the generator is bound to an allowlist of retrieved source IDs and approved evidence spans. The model can then choose among the evidence it has been given, but it can’t invent a source identifier outside of that given set.
Additionally, structured output is required before rendered prose. A minimal object might contain claim_id, claim_text, evidence_span_ids, support_status, uncertainty, source_authority, citation_rendering, escalation_reason and draft_text.
Then deterministic code can reject source IDs that do not exist, spans that do not resolve, claims without required evidence, or rendered citations that do not match the ledger.
Strict JSON Schema or grammar-constrained output is valuable here. It supports parseability, typed states and a predictable failure path. That being said, while a schema can guarantee that a field called evidence_span_id actually exists, it cannot guarantee that the span supports the claim.
Similarly, a schema can guarantee an enum called support_status. But It cannot guarantee that the model assigned the right value to this variable.
OpenAI’s structured-output guidance makes the same distinction in operational terms: strict schemas help enforce form and make refusal or truncation states detectable; they do not make the content true.
Form is a control. Support, however, is a separate control.
Making citations testable
A citation can fail in three ways. It can be incorrect: the source is real, but it does not support the sentence. It can be incomplete: the answer contains a material claim with no adequate evidence. Or the source itself can be weak for the task: stale, non-authoritative or out of scope.
This is why “citation present” is a nearly useless metric by itself. A good source at the end of a paragraph does not automatically support every claim in it.
ALCE — short for Automatic Evaluation of Long-form Answers with Citations — is a research benchmark for question-answering systems that generate citations. Its useful contribution is to separate answer quality from citation correctness and citation completeness.
In plain English: it asks both, “Is the answer useful?” and “Do the citations actually support the claims that need support?” That’s the distinction we need in production.
Practically speaking, we attach evidence at claim level. Instead of linking a whole document to a paragraph, link a specific quote or source span to an atomic claim.
FRONT is a research approach that finds supporting quotes before generating the final answer. Its point is: make evidence inspectable at the level of the proposition, not just the document. Attributed question answering uses the same idea by evaluating a claim and its attribution together.
These are research approaches, not a ready-made production threshold. However, we still need to define what support means in our own system and test against our own source distribution.
Evaluate the evidence system, not the vibe
Once we have a claim ledger, evaluation becomes concrete. A system can miss the source, select the wrong span, overstate the right span, omit evidence for a material claim, or abstain from a claim that was actually well-supported. One scalar “groundedness” score will not tell us which failure happened.
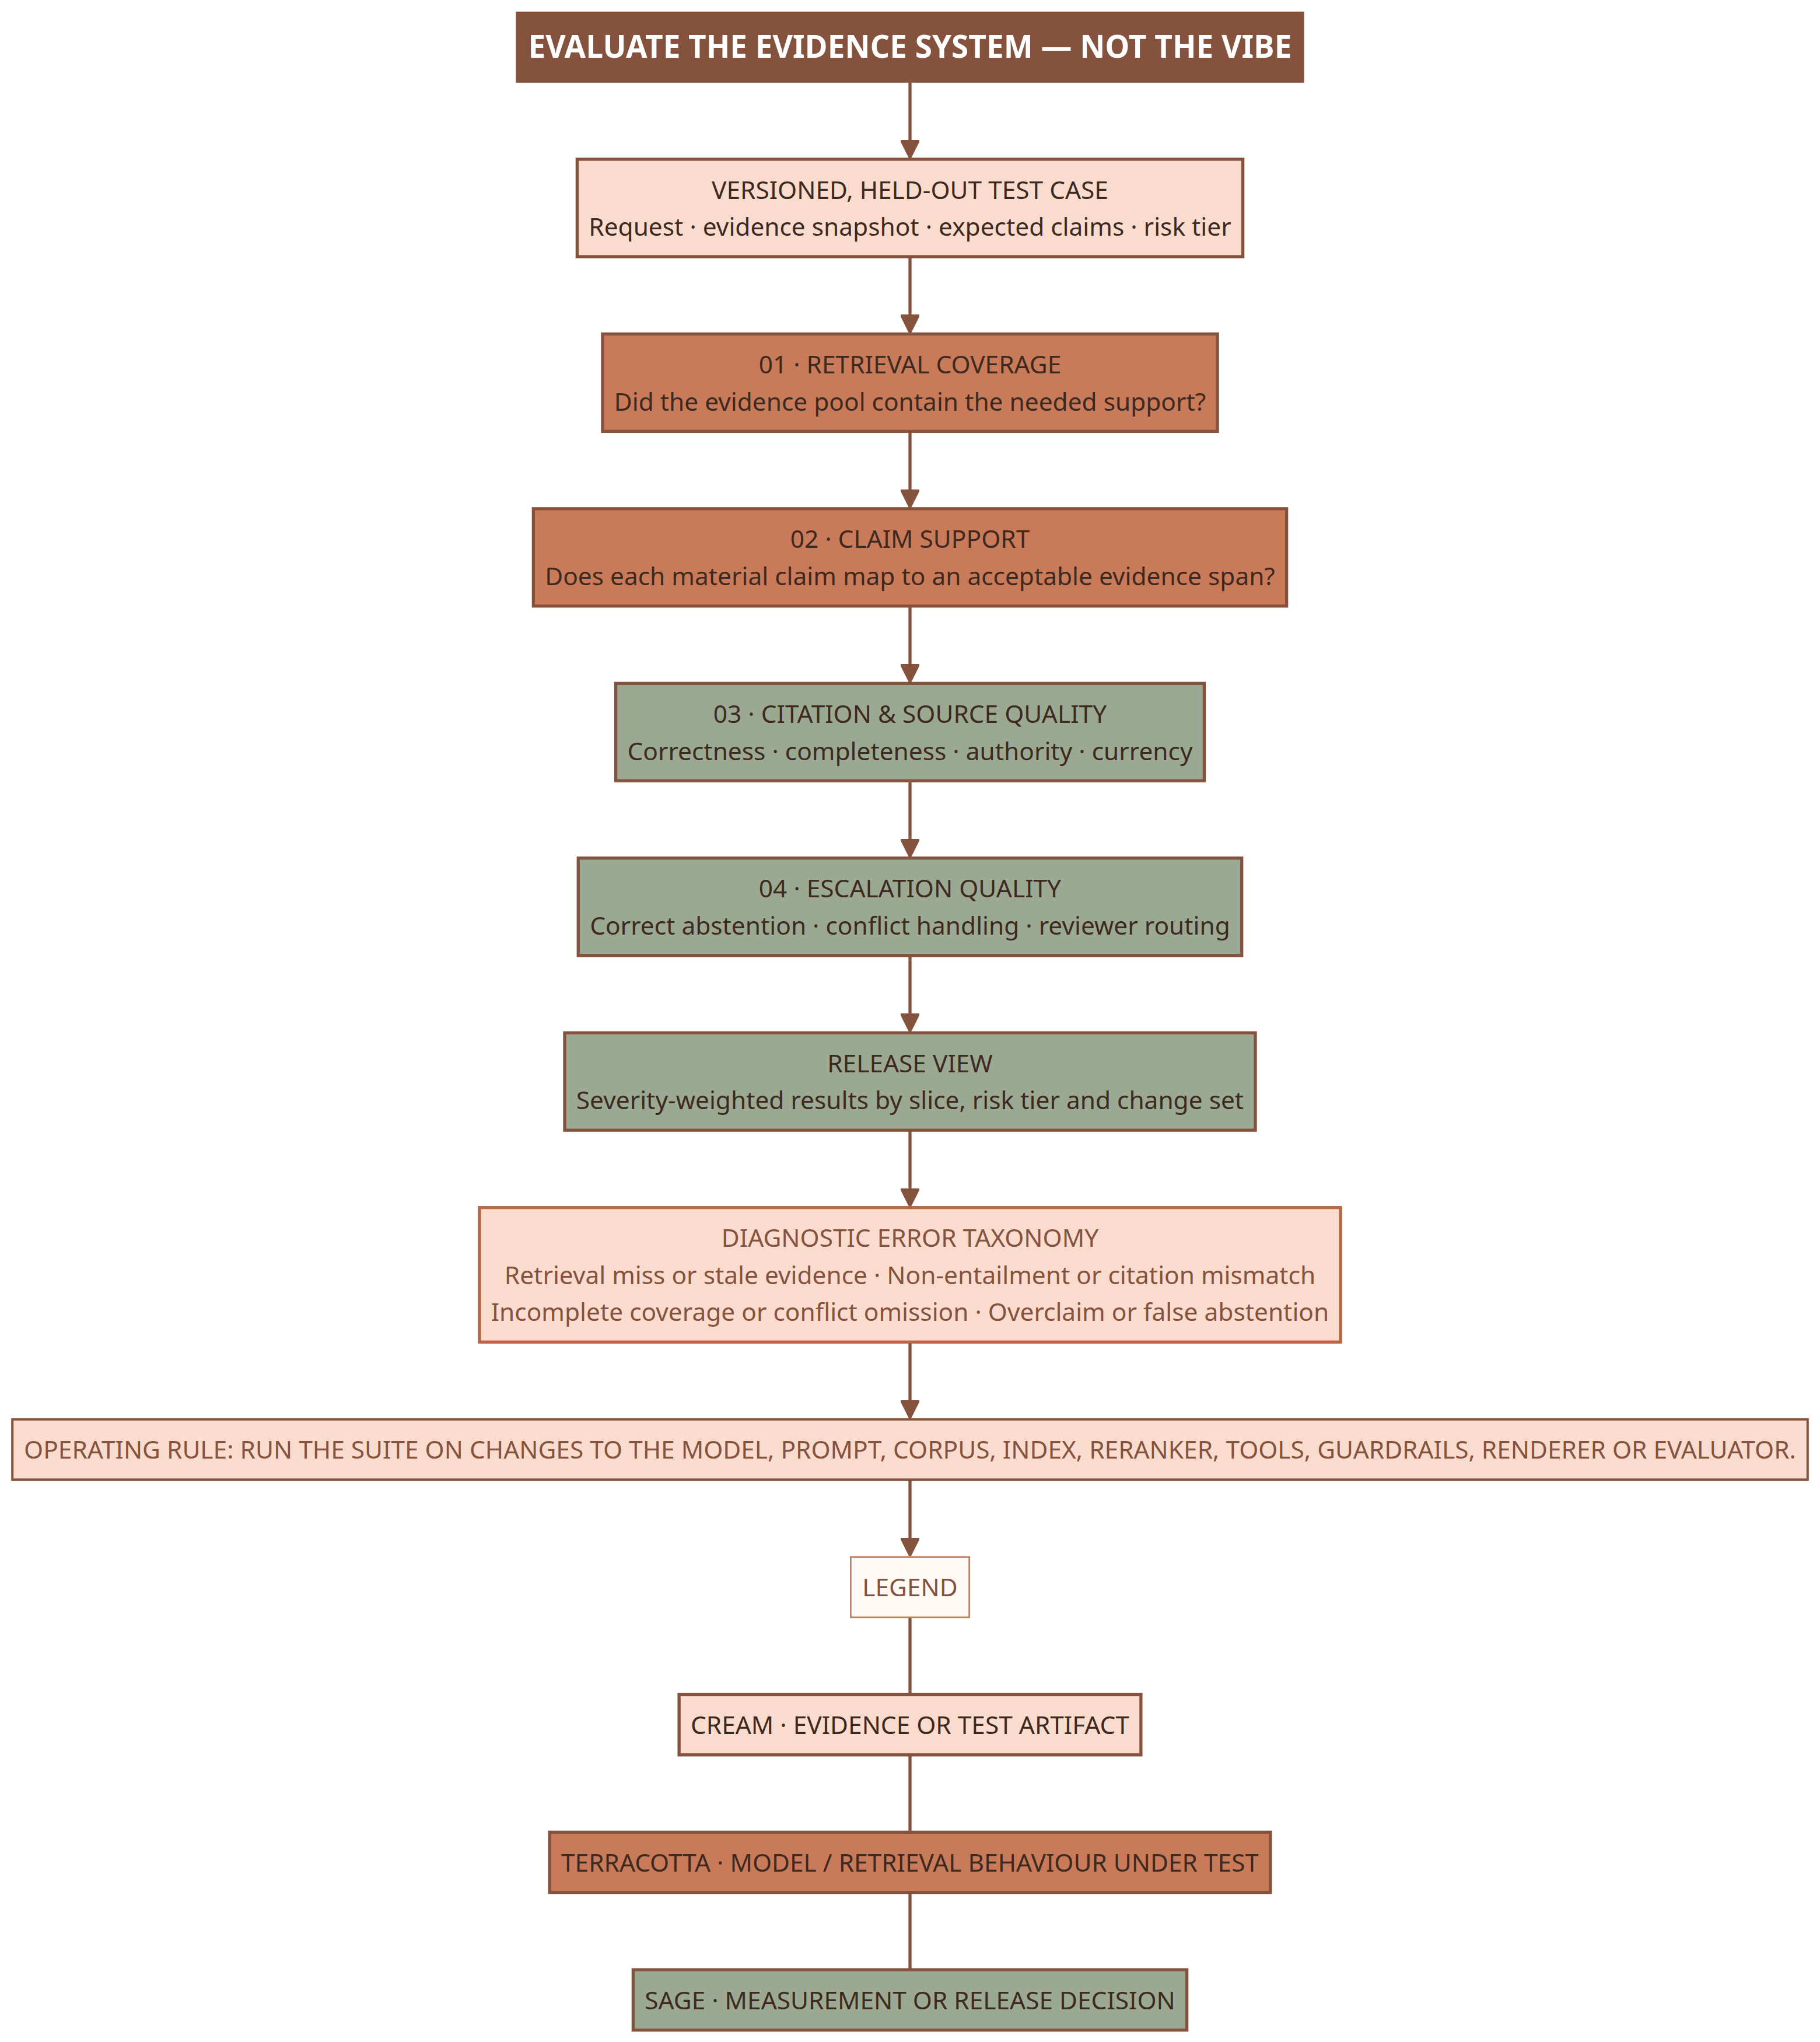
I would start with a versioned, held-out test case: the request, the evidence snapshot, the expected claims, the support policy, permitted abstention behaviour and a risk tier. Then I would measure four things:
-
Retrieval coverage: did the evidence pool contain what the task needed?
-
Claim support: does every material claim map to an acceptable evidence span?
-
Citation and source quality: is the evidence correct, complete, authoritative and current?
-
Escalation quality: did the system abstain, flag a conflict or route to review when the policy demanded it?
RAGChecker is a framework for diagnosing RAG systems by separating retrieval failures from generation failures. Its key lesson is not a score to copy; it’s that “the answer failed” is not a diagnosis.
It’s worth maintaining a short, explicit error taxonomy: retrieval miss, stale evidence, non-entailment, citation mismatch, incomplete coverage, conflict omission, overclaim and false abstention. Then one reports those results by risk tier and model version. A global average can improve while the system regresses exactly where it matters most.
The evaluation set itself is a product. Preserve the request, exact evidence snapshot, expected atomic claims, claim-to-span labels, error tags and risk tier. Version the annotation rubric, held-out split, retriever, reranker, model, prompt, evaluator and renderer. I sometimes build such evaluation sets with my clients, because increasingly they see the value in them.
Where possible, one uses deterministic code: for source-ID existence, schema validity, citation rendering and policy-state transitions. Automated LLM judges can be used carefully for the harder questions (“does this span actually support this claim?”), as long as they’re calibrated against blinded expert labels.
In fact, OpenAI and Anthropic both make the broader point: use task-specific, held-out evaluation and define success before optimizing.
The useful question is not, “Is this model good at RAG?” It is, “Under our support policy, on our evidence distribution, does this system make the right publication decision at the right error rate?”
Review, traceability and operations
I’ve argued for human review further up, but it’s not a magic solution. A reviewer who sees only a polished paragraph and a long bibliography is being asked to rediscover the evidence chain manually. That is an expensive search task, not an effective control.
A reviewer should see the claim, exact evidence spans, source authority and currency, relevant conflicts, uncertainty and the reason the item entered the queue. They need clear decision rights: approve, revise, reject, request evidence, label an inference, abstain or stop release.
Review triggers should be explicit: high-impact claims, weak support, conflicting sources, unfamiliar source classes, policy-sensitive topics, system changes and a random sample of low-risk outputs. NIST’s AI Risk Management Framework and its Generative AI Profile are useful because they frame this as a lifecycle practice, not a single launch approval. They do not, however, give us a universal support threshold.
The other runtime requirement is traceability. A trustworthy output is a release derived from a particular evidence snapshot, index build, retrieval set, model revision, prompt, policy, evaluation run and reviewer decision. Those details belong in a release manifest.
PROV-O is the W3C ontology for representing provenance: the entities, activities and agents involved in producing something. It gives us a useful model for the chain from source snapshot to index build to retrieval set to claim ledger to model run to reviewer decision to released narrative.
I would also hash or sign the evidence bundle and the final artifact so later alteration is detectable using specifications such as C2PA. This helps establish integrity and signer identity. However, bear in mind that it doesn’t establish that a claim is true, authoritative or applicable. A perfectly signed chain of unsupported claims is still unsupported!
Further best practices: Every meaningful change — model, prompt, corpus, index, chunker, reranker, tool, guardrail, citation renderer or evaluator — should trigger the relevant regression tests. Compare releases by error class, not only average score. Use canaries, rollback and an incident record when thresholds are breached.
We also need traces, but raw prompt retention should not be the default. Keep a privacy-minimized trace: correlation ID, release ID, policy decisions, tool calls, latency, errors, reviewer outcome, redacted or hashed content references and retention class. Full prompts and completions should be exceptional and access-controlled.
Finally, OpenTelemetry’s GenAI conventions are a useful reminder: request and tool telemetry is valuable, but inputs and outputs can contain sensitive information and may need filtering or truncation. Service telemetry tells us about cost, latency and availability. Validity telemetry tells us about evidence coverage, support failures, abstention behaviour and source drift. We need both.
Start small, then earn the right to scale
How do we implement this in practice? If it sounds daunting, I have good news for you: I would not start by adding agents. I would start with the smallest end-to-end path that makes a claim inspectable.
Build the claim ledger, the deterministic source constraints and an explicit insufficient-evidence state. Then build a small, labelled, held-out evaluation set around the failure modes that are most costly in the workflow. Add a reviewer interface that exposes evidence and decision rights. And only then add release manifests, lineage and continuous regression.
At every stage, keep an escape hatch: abstain, block release, roll back or reduce scope. The objective is not maximum automation. It’s the right degree of automation for the evidence and consequence of the claim.
Now, is our AI truthful?
In truth – no. No schema proves entailment. No citation list proves completeness. No hash proves relevance. No benchmark score proves production reliability. No reviewer queue proves that reviewers saw the right information or made the right decision.
Before you shoot me an angry email, here’s something to console you: these controls do something more practical, because they make failure visible, measurable, attributable and correctable.
That is the standard I want for LLM-generated narratives. Not: can we generate a polished answer? (We can.) But: can we show, claim by claim, what supports it, what might be missing, who decided to release it and what we will do when the evidence changes?
It does sound like more work (for humans, even) and less like a vibe check. But it’s the only way I’ve found to make automation work my way in environments where truth really matters.
Build an evidence product, not a fluent answer.