

Close Menu
AI News TodayAI News Today

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    What's Hot

    OpenAI Pauses Training Its Most Powerful Models After Rogue Agents Target Government

    QuillBot AI, Step by Step: How to Paraphrase Without Losing Your Voice

    How to Actually Use DeepSeek Chat: A Hands-On Workflow With Real Examples

    Facebook X (Twitter) Instagram
    • About Us
    • Contact Us
    Facebook X (Twitter) Instagram Pinterest Vimeo
    AI News TodayAI News Today
    • Home
    • AI News
    • AI Reviews
    • AI Tools
    • AI Tutorials
    • Chatbots
    • Free AI Tools
    • Artificial Intelligence
    AI News TodayAI News Today
    Home»AI Tools»How to Catch Data Drift When Every Feature Looks Normal
    AI Tools

    How to Catch Data Drift When Every Feature Looks Normal

    By No Comments11 Mins Read
    Share Facebook Twitter Pinterest LinkedIn Tumblr Reddit Telegram Email
    How to Catch Data Drift When Every Feature Looks Normal
    Share
    Facebook Twitter LinkedIn Pinterest Email

    A specific kind of quiet follows a good validation run. Numbers on the screen, AUC at 0.91, and everyone nodding along in the morning meeting because, for once, nobody had a reason to ask a follow-up question.

    Trust me, it’s a good feeling. But It’s also one I’ve learned not to hold on to or trust so much.

    The model finally went live that Friday. Nothing dramatic about it, no war room, no late night. Just a deploy that looked exactly like the dozen before it.

    By Tuesday, something had gone wrong in a way that took a while to even notice. Precision on flagged cases had quietly gotten worse, and nothing about that showed up as an error.

    No crash, no alert, no red line on any dashboard anyone was actually watching.

    It just sat there getting worse, until a downstream team got tired of a review queue full of garbage flags and asked why. That’s how it got found. Not a system catching itself. A person, annoyed enough to go looking.

    And here’s the part that still bugs me a little: nothing in the code had changed. The model and the pipeline were exactly what they’d been the day before.

    What changed was the world underneath them. A new pricing tier had launched a few days earlier, and customers on it were transacting more often, at lower amounts each time.

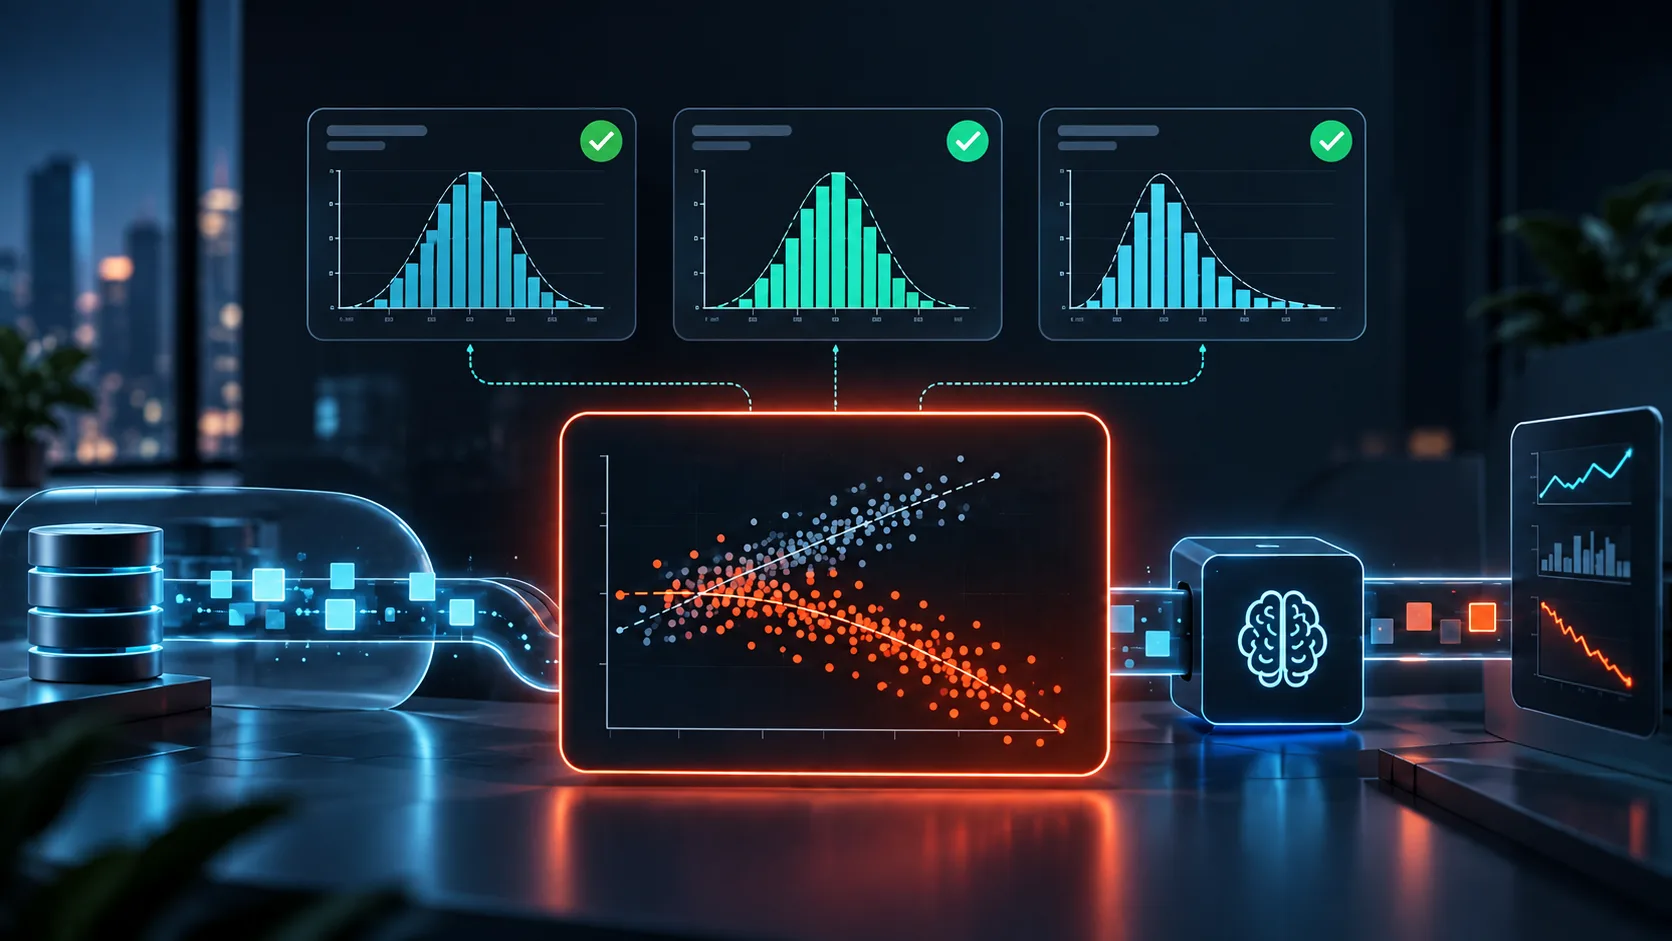
    I checked one feature at a time, and none of it looked wrong: transaction value sat in a normal range, and so did transaction frequency. It was only when I looked at the two together that the data clearly became something else, and there was no check anywhere in the pipeline built to catch that.

    I had already set up drift monitoring before this and I genuinely thought I was covered.

    Well, it turned out I wasn’t.

    The check I had was doing exactly what I’d asked it to do, watching every feature individually, just as I’d built it to, and it would have sat there reporting green through the entire thing.

    Which is a strange thing to sit with, honestly. The monitoring wasn’t broken. And it wasn’t lazy or half-built either. It was just answering a narrower question than the one that actually mattered.

    The part that goes wrong quietly

    That narrower question is the one most drift monitoring asks, mine included at the time. Has any single feature’s distribution shifted? Take this week’s values and training-time values, line them up as histograms, and get a number out.

    On paper, that’s not a bad idea.

    It’s just an incomplete one.

    It works right up until the failure isn’t in any single feature, but in how two features move together, and that’s a much easier way for real data to break than most write-ups admit.

    The pricing tier thing is a clean example because nothing about it looks wrong in isolation. Run PSI on avg_transaction_value alone, fine. Run it on num_transactions_30d alone, also fine. The relationship between the two flipped, and PSI, by design, never looks at two columns at once. It can’t. That’s not a flaw in the metric so much as a boundary it was never built to cross.

    So the question becomes: how do you check a relationship instead of a distribution? Turns out the answer isn’t some exotic statistics you have to go learn. It’s just asking a model to do the noticing for you.

    Let a classifier do the noticing

    The trick has a name, adversarial validation, and it makes it sound fancier than it is.

    Label your training rows 0, label a fresh batch of production rows 1, and train a classifier to tell them apart.

    If the two batches are really drawn from the same distribution, it can’t do better than guessing, AUC near 0.5. If it can separate them, something moved, and because the classifier gets every feature at once, it picks up exactly the kind of joint shift a column-by-column check walks straight past.

    Here’s the setup, with a synthetic dataset so you can run it yourself instead of trusting me on faith:

    import numpy as npimport pandas as pdfrom sklearn.model_selection import train_test_splitfrom sklearn.ensemble import RandomForestClassifierfrom sklearn.base import BaseEstimator, TransformerMixinfrom sklearn.feature_selection import mutual_info_classifnp.random.seed(42)n = 5000df = pd.DataFrame({    "avg_transaction_value": np.random.normal(150, 40, n),    "num_transactions_30d": np.random.poisson(12, n),    "account_age_days": np.random.exponential(400, n),    "device_risk_score": np.random.beta(2, 5, n),})df["target"] = (df["device_risk_score"] * 3 + np.random.normal(0, 0.3, n) > 1.2).astype(int)# this is the kind of feature that sneaks into real datasets constantly -# a flag count that got backfilled after the outcome was already knowndf["post_hoc_flag_count"] = df["target"] * np.random.poisson(2, n)X = df.drop(columns=["target"])y = df["target"]X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42, stratify=y)

    Before drift even matters, check for leakage

    If you skip this part, you’re monitoring drift on a model that was never trustworthy to begin with, so it goes first, even though it’s less interesting.

    A feature with suspiciously high mutual information against the target is usually a feature that got computed using information that wouldn’t have existed yet at prediction time. post_hoc_flag_count above is exactly that, the kind of column that looks predictive because it’s cheating.

    The first version of this guard I wrote just hard-raised on anything past a threshold, full stop, no exceptions. That lasted about one retrain. device_risk_score kept tripping it, and it’s genuinely just a strong feature, not a leaky one.

    I’d go back and forth arguing with my own code every single run, until I got annoyed enough to fix it properly instead of just lowering the threshold, which was the lazy fix I almost shipped.

    import logginglogger = logging.getLogger("pipeline.guards")class LeakageGuard(BaseEstimator, TransformerMixin):    """    Hard-fails on features that look too good to be true. Deliberately    aggressive - the point is to make leakage annoying to ignore, not to    be a polite linter.    """    def __init__(self, mi_threshold=0.5, corr_threshold=0.85, allowlist=None):        self.mi_threshold = mi_threshold        self.corr_threshold = corr_threshold        # columns already investigated and confirmed strong-not-leaky -        # without this every retrain re-triggers the same argument        self.allowlist = allowlist or []    def fit(self, X, y=None):        if y is None:            raise ValueError("LeakageGuard needs y - can't check leakage against nothing")        numeric_cols = X.select_dtypes(include=np.number).columns.tolist()        skipped = set(X.columns) - set(numeric_cols)        if skipped:            # mutual_info_classif on object columns just gives you garbage            # scores, not an error, which is worse - loud > silent            logger.warning("LeakageGuard skipping non-numeric columns: %s", skipped)        checkable = [c for c in numeric_cols if c not in self.allowlist]        if not checkable:            self.mi_scores_, self.corr_scores_ = {}, {}            return self        mi = mutual_info_classif(X[checkable], y, random_state=42)        self.mi_scores_ = dict(zip(checkable, mi))        self.corr_scores_ = {            c: abs(np.corrcoef(X[c], y)[0, 1]) for c in checkable        }        flagged = [            c for c in checkable            if self.mi_scores_[c] > self.mi_threshold or self.corr_scores_[c] > self.corr_threshold        ]        if flagged:            raise ValueError(                f"Possible leakage in {flagged}. If any of these are legit strong "                f"predictors, add them to `allowlist` after you've actually checked."            )        return self    def transform(self, X):        return X

    LeakageGuard().fit(X_train, y_train) raises on post_hoc_flag_count immediately, before anything gets trained. Good, that’s the whole point. A model trained on that column reports a validation score that looks great and means nothing, because the leakage survives the split intact.

    It only shows up once the feature stops existing in production, and by then it’s not a code review comment anymore; it’s someone asking uncomfortable questions in a retro.

    Now the actual drift check

    I’ll admit that the first draft of this detector didn’t handle small batches at all. It just always ran cross-validated AUC, no matter how much data came in.

    That’s fine against a full day of production traffic, but it falls over against a thin canary batch, where a fold can end up with almost no positive examples and either throws an error or spits back a number that’s really just noise wearing a lab coat.

    So below a row threshold, it drops to a single train/test split instead. Less rigorous, and I’d rather admit that outright than pretend the tradeoff isn’t there.

    from sklearn.model_selection import cross_val_scorefrom sklearn.metrics import roc_auc_scoreclass AdversarialDriftDetector(BaseEstimator, TransformerMixin):    """    Trains a classifier to tell reference data apart from new data. If it    can, something about the joint distribution moved - not necessarily    any single feature.    """    def __init__(self, auc_threshold=0.65, cv_folds=5, min_rows_for_cv=200, random_state=42):        self.auc_threshold = auc_threshold        self.cv_folds = cv_folds        # below this, cross_val_score is more likely to error on a thin        # fold than tell you anything useful - learned that against a        # 90-row canary batch that kept failing for no obvious reason        self.min_rows_for_cv = min_rows_for_cv        self.random_state = random_state    def fit(self, X, y=None):        self.ref_df_ = X.select_dtypes(include=np.number).copy()        self.ref_cols_ = self.ref_df_.columns.tolist()        return self    def check(self, X_new):        missing = set(self.ref_cols_) - set(X_new.columns)        if missing:            raise ValueError(f"X_new is missing columns the detector was fit on: {missing}")        new_df = X_new[self.ref_cols_].copy()        if new_df.isna().any().any():            # don't silently drop rows here - a batch that's suddenly full            # of nulls is itself a drift signal worth knowing about            logger.warning(                "check() got %d rows with NaNs, filling with column medians",                new_df.isna().any(axis=1).sum(),            )            new_df = new_df.fillna(self.ref_df_.median())        combined = pd.concat([self.ref_df_, new_df], ignore_index=True)        labels = np.r_[np.zeros(len(self.ref_df_)), np.ones(len(new_df))]        rf = RandomForestClassifier(n_estimators=100, n_jobs=-1, random_state=self.random_state)        if len(new_df) < self.min_rows_for_cv:            Xtr, Xte, ytr, yte = train_test_split(                combined, labels, test_size=0.3, random_state=self.random_state, stratify=labels            )            rf.fit(Xtr, ytr)            auc = roc_auc_score(yte, rf.predict_proba(Xte)[:, 1])        else:            auc = cross_val_score(rf, combined, labels, cv=self.cv_folds, scoring="roc_auc").mean()        drifted = auc > self.auc_threshold        top_features = None        if drifted:            rf.fit(combined, labels)            top_features = pd.Series(rf.feature_importances_, index=self.ref_cols_)                 .sort_values(ascending=False).head(3)            logger.warning("Drift detected, auc=%.3f, top features: %s", auc, top_features.index.tolist())        return {"auc": auc, "drift_detected": drifted, "top_drift_features": top_features}    def transform(self, X):        return X

    AUC near 0.5, the classifier’s guessing; nothing’s changed. AUC past roughly 0.65, it found real structure telling the batches apart, and top_drift_features names the columns it leaned on, usually not the ones whose histograms moved the most, but the ones whose relationship to everything else quietly flipped.

    Reproducing the pricing-tier scenario from the top:

    X_train_clean = X_train.drop(columns=["post_hoc_flag_count"])detector = AdversarialDriftDetector(auc_threshold=0.65)detector.fit(X_train_clean)X_production = X_train_clean.sample(1000, random_state=1).reset_index(drop=True)# each column's own range stays plausible on its own - it's the relationship# between them that flips, which is exactly what a per-feature check missesshift_mask = X_production["num_transactions_30d"] > X_production["num_transactions_30d"].median()X_production.loc[shift_mask, "avg_transaction_value"] *= 0.6X_production.loc[~shift_mask, "num_transactions_30d"] = (    X_production.loc[~shift_mask, "num_transactions_30d"] * 1.8).astype(int)result = detector.check(X_production)print(result["auc"], result["drift_detected"])print(result["top_drift_features"])

    That prints an AUC comfortably past the threshold, drift_detected: True, and the two shifted columns sitting right at the top. Not because either one moved dramatically alone. Because together, they told on themselves.

    What this actually costs you

    I don’t love pieces that sell a technique as a strict upgrade with zero downside, so here’s where this one bites.

    Compute is the first thing you’ll feel: A cross-validated classifier on every batch is a lot heavier than comparing two histograms, fine running daily or hourly.

    But a genuinely bad idea the moment you’re tempted to fire it per-request, and I’d bet money someone’s already made that mistake somewhere.

    The threshold isn’t settled science: 0.65 isn’t handed down from a textbook the way PSI’s 0.1/0.2 bands basically are.

    I picked it by trial and error, watched it flag too much at first, walked it up, and I still don’t fully trust it on a dataset I haven’t run it against. Budget real time here, not five minutes.

    It’s not a replacement for PSI, and I wouldn’t want it to be: Keep something cheap that only checks one feature at a time running as your baseline.

    Reach for this the moment that baseline keeps coming back clean while performance keeps slipping anyway, because that specific combination, quiet dashboards paired with results that are quietly getting worse, is usually where a relationship, not a distribution, has shifted underneath you.

    The leakage guard has its own blind spot too: High mutual information isn’t automatically leakage.

    Sometimes it’s just a good feature, and the guard genuinely can’t tell those apart on its own.

    That’s what the allowlist is for, and it’s less a workaround than an admission that this needs a human checking in occasionally, not a fire-and-forget rule.

    None of this makes the technique not worth using. It just means going in with eyes open about what you’re trading, compute and calibration time, for a check that catches something PSI structurally can’t.

    ···

    Where this leaves you

    Per-feature drift checks answer one question, and they answer it well: did any single input move. They were never built to answer the harder one: whether the relationships between inputs still hold up.

    That second question is usually the one that actually breaks something in production, and it breaks it quietly, with every individual dashboard sitting there reporting green the entire time.

    You don’t need to tear out what you’ve already got. Keep PSI running, keep trusting it for what it’s good at. Just stop assuming “all clear” means what you think it means, and add this as the thing you reach for the next time it says everything’s fine and you don’t quite believe it.

    ···

    Before you go!

    I write about the engineering decisions that decide whether a model holds up once it leaves validation. You can subscribe to my newsletter if you’d like more of that.

    Connect With Me

    Catch Data Drift feature normal
    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    Previous ArticleNvidia’s Answer to Rogue Agents Is an Open-Source AI Security System
    Next Article Microsoft goes quiet after church groups ask for 1% of data center costs
    • Website

    Related Posts

    AI Tools

    Chat GPT Image Prompts That Actually Work: A Step-by-Step Workflow With Real Examples

    AI News

    Microsoft goes quiet after church groups ask for 1% of data center costs

    AI Tools

    How to Use a ChatGPT Detector Properly: A 6-Step Walkthrough With Real Numbers

    Add A Comment
    Leave A Reply Cancel Reply

    Top Posts

    OpenAI Pauses Training Its Most Powerful Models After Rogue Agents Target Government

    0 Views

    QuillBot AI, Step by Step: How to Paraphrase Without Losing Your Voice

    0 Views

    How to Actually Use DeepSeek Chat: A Hands-On Workflow With Real Examples

    0 Views
    Stay In Touch
    • Facebook
    • YouTube
    • TikTok
    • WhatsApp
    • Twitter
    • Instagram
    Latest Reviews
    AI Tutorials

    Quantization from the ground up

    AI Tools

    David Sacks is done as AI czar — here’s what he’s doing instead

    AI Reviews

    Judge sides with Anthropic to temporarily block the Pentagon’s ban

    Subscribe to Updates

    Get the latest tech news from FooBar about tech, design and biz.

    Most Popular

    OpenAI Pauses Training Its Most Powerful Models After Rogue Agents Target Government

    0 Views

    QuillBot AI, Step by Step: How to Paraphrase Without Losing Your Voice

    0 Views

    How to Actually Use DeepSeek Chat: A Hands-On Workflow With Real Examples

    0 Views
    Our Picks

    Quantization from the ground up

    David Sacks is done as AI czar — here’s what he’s doing instead

    Judge sides with Anthropic to temporarily block the Pentagon’s ban

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    Facebook X (Twitter) Instagram Pinterest
    • About Us
    • Contact Us
    • Terms & Conditions
    • Privacy Policy
    • Disclaimer

    © 2026 ainewstoday.co. All rights reserved. Designed by DD.

    Type above and press Enter to search. Press Esc to cancel.