

Part 1: A stick on a cart, and forty years of dropping it
You have a cart that slides along a rail. Balanced on top is a pole, hinged at the bottom, doing its absolute best to fall over, because that is what poles do. Your only power is to shove the cart left or right. Your job is to not let the stick fall down.
If you’ve ever balanced a broom or a stick on your palm you already understand the whole problem, including the counterintuitive bit: you don’t keep the broom still, you keep moving your hand underneath it. This is CartPole, the most famous toy problem in AI.
The game describes its world with four numbers:
|
Number |
What it means |
|---|---|
|
Cart position |
where the cart is along the rail |
|
Cart velocity |
how fast the cart is sliding, and in which direction |
|
Pole angle |
how far the pole has tipped from upright |
|
Pole angular velocity |
how fast it is tipping |
Two ways you can lose the game: the pole tips more than 12 degrees, or the cart slides more than 2.4 units from centre and off the rail. Survive 500 steps and you’ve won. (In the code those 12 degrees appear as 0.2095 radians, which is just another unit for angles. Computers prefer them. Nobody knows why they had to be so ugly.)
Why this silly little game is picked? that is because it’s older than most of the field (after a 1983 paper by Barto, Sutton and Anderson) and so every new method gets tested on it first. Since four numbers and two buttons means every chart here is a line you can read with your eyes, so when something goes gloriously wrong later you’ll see exactly why. And because every number here came from a script on one computer, written to a file in the repo so you can check I’m not making them up.
We’ll solve CartPole the standard way first, and it’ll work. Then we’ll ask that solution for something slightly different, watch it fail instructively, and only then build the thing this article is all about.
···
Part 2: How the normal approach plays it
Suppose you got good at CartPole by brute force with a notebook. Every time you hit some situation, e.g. pole leaning left while cart drifting right, you’d try a shove and note how the rest of the game went. Then playing is easy: look up your situation, read both entries, do whichever has the bigger number. You understand nothing about physics; you just need a big enough notebook.
That is the whole idea behind the standard solution, and the only problem is the notebook. There are infinitely many situations, like the pole can be at 3.7 degrees or 3.7003, and you’ll never see the same one twice. What you need is something that can guess the entry for a situation it has never seen, by noticing 3.7003 is a lot like 3.7. Which is what neural networks are for, so we replace the notebook with a small network: situation in, two scores out.
That’s a DQN — “deep Q-network”, where “Q” is the letter somebody picked in the 1980s for “score of doing this action in this situation”. It stuck.
Four numbers in, two out. That’s the entire brain. Training is a loop: play a shove (early on mostly at random, because flailing is a respectable way to gather data), write down what happened, nudge the network so its scores match the rewards that turned up, repeat.
The word doing the heavy lifting is reward — the number the game pays out after each shove, and the only thing the agent is trying to collect. For ordinary CartPole it is one of the least dramatic pieces of code ever written:
One point per step survived. Look at that line a moment longer than it deserves, because that single line is where the goal lives. Everything the agent will ever want is in there. Remember where it is. We’re coming back for it.
Does it work?
Yes.
Five DQN training curves on standard CartPole, showing steps
survived per episode across five random seeds.
Five training runs, each starting from complete ignorance. All five begin around 20 steps — what random flailing gets you — and all five climb, ending at 350 ± 184 out of 500 steps after about 39,000 steps of real play. A machine that taught itself to balance a pole by falling over a lot, and nobody told it what a pole is.
Hold on to that ±184, because the runs don’t behave the same. One sails to 480 then sags back; two plateau around 100 and sulk. DQN training is genuinely temperamental, and a properly tuned one solves CartPole outright — three of our five touched the perfect 500 during training. So I’ll tip the scales the other way: we keep each agent’s best version ever reached, not its final weights. I’d rather beat the good version.
Put a pin in the wobbliness. It returns in Part 3, considerably less charming.
···
Part 3: Now ask it for something else
The pole still has to stay up. I’d just also like the cart parked at x = +1.0, a metre right of centre. Same game, same physics, same two buttons, one extra preference.
Go ahead and try to ask. Not “try to make it happen” — try to ask. Find me the function call. There isn’t one: no argument, no flag, no field on the object. The goal is not something the agent has. It’s something the agent is.
So let’s do the only thing available — ask anyway, and watch. Here is our perfectly good balancing agent while I stand behind it repeating “park at x = +1.0” in a clear and patient voice.
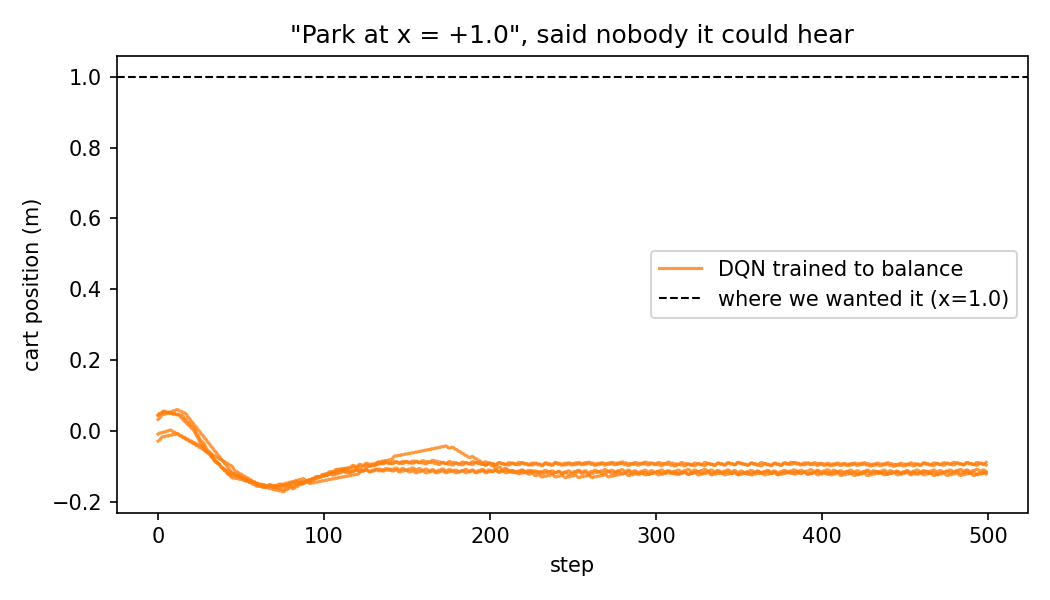
Cart position over time for a balance-trained DQN that is being
asked, rhetorically, to park at x = +1.0.
It hovers around x = −0.1, roughly where it started and nowhere near where I asked.
Notice what didn’t happen. It didn’t crash or glitch — it balanced, competently, which is exactly what we asked back when asking was possible. Over a hundred episodes it sits 0.957m from the target and survives 350 steps, its ordinary form. It doesn’t refuse; it carries on doing the one job it was ever given. There’s no ear. Three things follow, and they get worse as we move forward further.
Limitation one: the goal is set in concrete
The only place a goal can enter into a DQN is the reward function, and that was consumed during training:
Two lines apart. And that difference cannot be applied to an agent that already exists, any more than you can change the flour in a baked cake. You throw it away and train a new one. Changing your mind isn’t a setting, it’s a rehire — a completely new process from scratch
Limitation two: every change of mind is paid for in real failures
So we rehire. Three new goals, three new agents from scratch:
|
The new goal |
Real steps of practice needed |
|---|---|
|
Park the cart at x = +1.0 |
24,437 |
|
Never leave the middle ±0.5 of the rail |
46,117 |
|
Go to +1.0, wait, then come back to −1.0 |
19,138 |
For CartPole, who cares — it’s a simulation costing forty seconds and some electricity. Now put the cart on a real rail, in a real room, made of real metal. Every one of those 46,117 steps is a physical object really moving, and a large fraction of them are it really falling over, because that’s how it learns. That’s the bill in a currency you cannot print, and it’s why this corner of AI exists: the most expensive thing isn’t computation, it’s experience.
Limitation three: it never actually learned the game
Look again at what the notebook contains: “in this situation, this shove tends to work out.” Notice what it does not contain — any statement about what the cart will actually do. Nothing about momentum, nothing about how a shove tips the pole the opposite way. It learned which move pays off, never how the cart behaves. Those sound similar. Here’s the evidence they aren’t — five training runs, identical code and reward, differing only in the random seed:
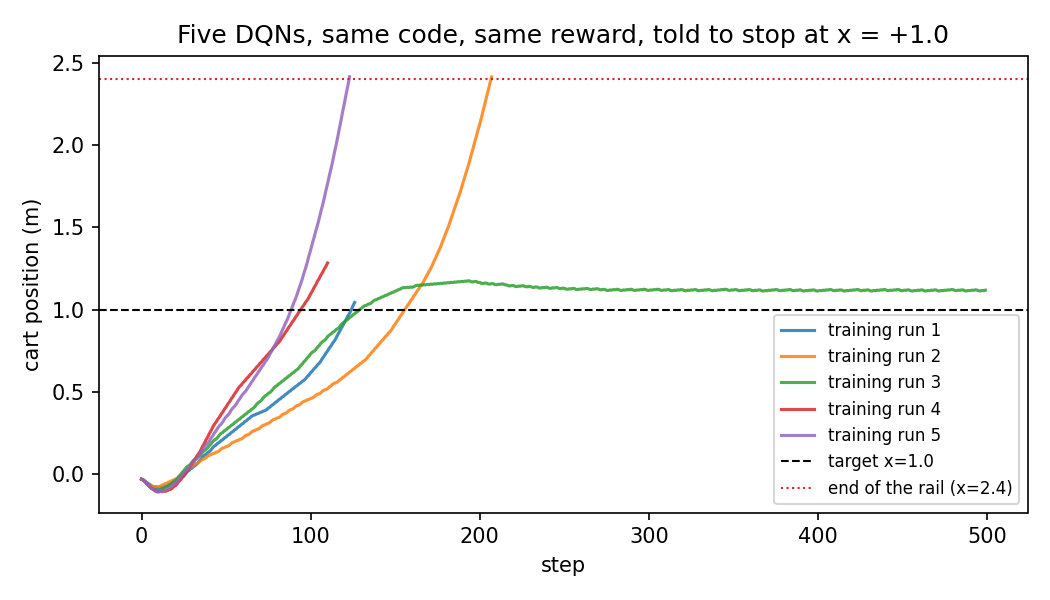
Cart position traces for five DQNs retrained with a parking
reward, showing five different outcomes from identical code.
|
Training run |
What the cart did |
|---|---|
|
1 |
reached the target, fell over at step 127 |
|
2 |
sailed past the target and off the end of the rail, step 208 |
|
3 |
parked at 1.12 m and held it for all 500 steps |
|
4 |
reached the target, fell over at step 111 |
|
5 |
sailed past the target and off the end of the rail, step 124 |
Run 3 nailed it. Runs 2 and 5 drove off the end of the rail like a dog chasing a ball into traffic: they’d learned “rightward is rewarding” with no concept of arriving. Anything that understood carts would know you have to slow down before you get there.
This makes limitation two worse than I made it sound. You don’t pay 24,437 real steps for the new goal, you pay it for a lottery ticket — and today it paid out one time in five. Those agents also share nothing: whatever run 3 figured out died with run 3, because the notebook has no column for how the world works.
One root cause: the agent learned an answer without learning the subject, and an answer only answers the question it was asked. Learning what to do is model-free — just reflexes. Learning how the world works is model-based. Everything from here is the second kind.
···
Part 4: The idea, before we write any of it
Think about crossing a busy road. You do not step into traffic and gather empirical data on the outcome; you do not need to be hit by a bus to form a considered opinion about buses. You stand on the curb and run the scenario: if I walk now, that bus arrives around the time I’m halfway across, and I don’t care for how that ends. So you wait four seconds and cross behind it.
You just imagined a future, disliked it, and picked a different one. No practice runs, no fatalities, no 24,437 attempts — because you carry a rough working copy of how the world behaves that you can run at will, for free.
So here’s the pivot. Stop training a network to know what to do. Train one to know what happens next.
A world model is a neural network that has learned to be the environment. Hand it a situation and an action, it hands back the next situation, without the real cart moving a millimetre. Which gives you something that knows how carts behave and has no opinion whatsoever about what you should do with them. Physics is magnificently indifferent to your goals: it simulates a cart travelling to x = +1.0 with the same enthusiasm it simulates one falling over.
So the goal has nowhere to hide. It can’t be baked into the weights, because the weights are busy being physics. Which takes Part 3’s limitations in order. The goal was set in concrete: now it’s a small function that reads an imagined future and says how much it likes it, and you can edit it on a Tuesday. Changes of mind cost real failures: now they cost none, because the search happens inside the network, and the pole never has to fall for the model to know it would have. It never learned the game: now that’s the only thing it learned, and since knowing how carts work is independent of what you want carts to do, it’s learned once and reused by every goal.
But then how does it decide anything?
Fair objection — we threw away the thing that chose actions. You do, with a loop that’s almost embarrassing:
-
Make up a few hundred random sequences of shoves.
-
Daydream every one, inside the model. The real world is not consulted.
-
Score each daydream, with whatever scoring function you feel like today.
-
Take the first shove of whichever came out best.
-
Play that one shove for real. Bin the rest. Go back to step 1.
That’s planning: imagine a load of futures, pick the nicest, take one step towards it, throw away your plan and think again. The road-crossing thing, done a few hundred times a second by something with no imagination to speak of but a great deal of patience.
One warning, so the next part reads as measurement rather than bad news. An imagined future is an approximation, and approximations rot — each imagined step starts from the previous one, so errors compound. Finding where the daydream turns to fiction is most of what comes next.
···
Part 5: Building the thing
5.1 Data worth learning from
Before the network can learn how carts behave, it has to watch some carts behave, so we play a few hundred games and write down every moment.
The obvious way is to shove randomly, which requires no thought and is its entire appeal. It’s also useless: a coin-flipping agent drops the pole in about 20 steps, so you get a model that has seen an enormous amount of falling over and essentially no balancing. Your model can only learn about situations that show up in your data — not a fact about neural networks, a fact about learning.
So we need a collector that can balance, without training a whole agent to do it. We cheat, in three lines:
If the pole’s tipping right, go right and get underneath it. That’s the broom on your palm, and it works embarrassingly well for something you could write on a napkin. (Yes, it’s better than the DQN. And I know, that’s awkward.)
But a flawless balancer has the opposite problem: it keeps the pole so close to vertical the model never sees anything go wrong. We’d have swapped a diet of pure failure for one of pure smugness. So we spike the drink (a quarter of the time we ignore the controller and shove at random) which keeps knocking it into ugly, nearly doomed positions it has to dig out of. Recovery is something the model very much needs to have seen.
Run that 500 times:
Two seconds. Not everything in machine learning has to hurt.
One detail matters more than it looks. The game reports two endings. terminated means the pole fell or the cart ran off the rail. truncated means the 500-step timer ran out; nothing failed, somebody blew a whistle. The lazy move is to mash them into one done flag. Don’t. A fall is a consequence of the state, so it can be learned; the timer is a stopwatch the model cannot see. Teach it that step 500 of a beautifully balanced game is a catastrophe and you’ve taught it to hallucinate.
5.2 Making the problem harder on purpose
A confession: as described, this task is too easy, in a way that would quietly render the next section pointless. Those four numbers are complete — everything needed to compute the next moment with school physics. A plain network with no memory could do it, and any memory I added would sit there like a hat rack in a swimming pool.
So we handicap it. The model only sees two of the four numbers: cart position and pole angle. The velocities are hidden.
Why kneecap our own model? that’s because that’s what reality is like. Point a camera at anything and it tells you where things are, never how fast they’re going. To know a speed you compare now against a moment ago. You need a memory.
So we give it a GRU cell: a small network with a scratchpad it updates every step and carries forward, whose job is to reconstruct the velocities we stole. Out of it come two predictions — what changes next, and is the next moment a crash. The whole thing is 13,635 numbers.
Two decisions matter more than the architecture. Predict the change, not the position. Consecutive moments are nearly identical: if the cart’s at 0.132, next step it’s at 0.134. A network asked for the next position scores magnificently by copying its input — beautiful numbers, no physics learned, the student who answers every question with “same as last time” and passes. Ask for the change instead, 0.002, and the trick evaporates.
Put both numbers on the same scale. Cart position roams over a range of about 2, pole angle inside about 0.2, so the network concludes position errors matter ten times more. They don’t; the angle is the one that kills you.
5.3 Training, and the small lie we tell throughout
Show the model 32 consecutive real steps, let it guess what comes next at each one, measure the wrongness, nudge its 13,635 internal numbers in whatever direction would have made it less wrong. Do that about 11,000 more times. Machine learning is mostly this, repeated until either the model converges or you do.
One wrinkle: the memory runs across all 32 steps, so a mistake at step 30 might be the fault of something misremembered at step 3. Blame travels backwards along the chain — an intimidating name, backpropagation through time, for an unintimidating idea.
Crashes need a thumb on the scale because they’re rare: one step in 380 is a failure. A model that answers “nah, we’re fine” every time scores 99.7% and is useless, like a smoke alarm that’s been unplugged and is therefore never wrong about your toast. So we count each crash 380 times over.
And now the lie, which is the hinge the whole article turns on. During training, at every step, we hand the model the real observation. Even when its last guess was nonsense, we wipe the slate and give it the truth before asking for the next prediction. This is teacher forcing: a driving instructor who grabs the wheel after every mistake and puts the car back in the lane. It makes training fast and stable, and it means the model never once experiences the consequences of its own errors. Hold that thought for ninety seconds.
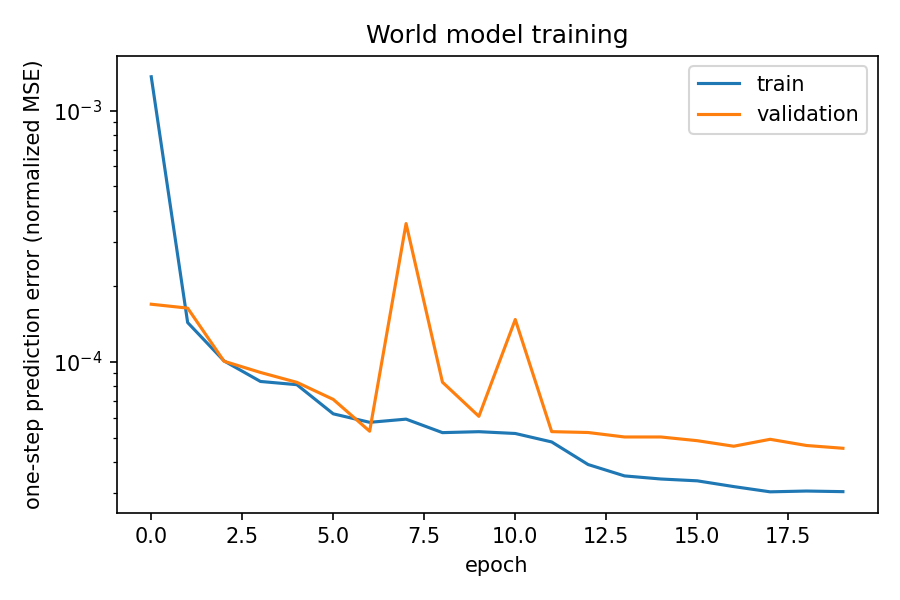
World model training and validation loss over 20 epochs.
Twenty passes through the data (each pass is an epoch, because somebody in the 1980s wanted it to sound more prestigious than “lap”), about three minutes. Blue is how wrong it is on games it studied, orange on games it has never seen. Both drop steeply and flatten, orange a little above blue, which is exactly right — a yawning gap would mean it had memorised our 500 games instead of learning physics.
In real units its one-step predictions are off by 3.8 millimetres of cart position and 0.00026 radians of pole angle, about a tenth of a percent of the distance to falling over. It catches 100% of real crashes at the price of about six false alarms each, which is the right way round: a planner that flinches at nothing is fine, one that strolls into a future where the pole already fell is not.
The model has learned CartPole physics. It’s perfect. We’re done.
(And yet, we are not done!)
5.4 Cutting it loose, and measuring the damage
Everything above measured one step, with the instructor’s hand hovering. Now take the hand off: give the model one real starting situation and a list of shoves, and make it predict each moment from its own previous prediction, a hundred times, with reality never consulted. The code change is one variable:
That line is the difference between a predictor and a world model, and it’s where the lie comes due. We trained it in a world where mistakes were erased instantly. Now they stack: a tiny error at step one becomes the input to step two, compounding like the world’s least appealing savings account.
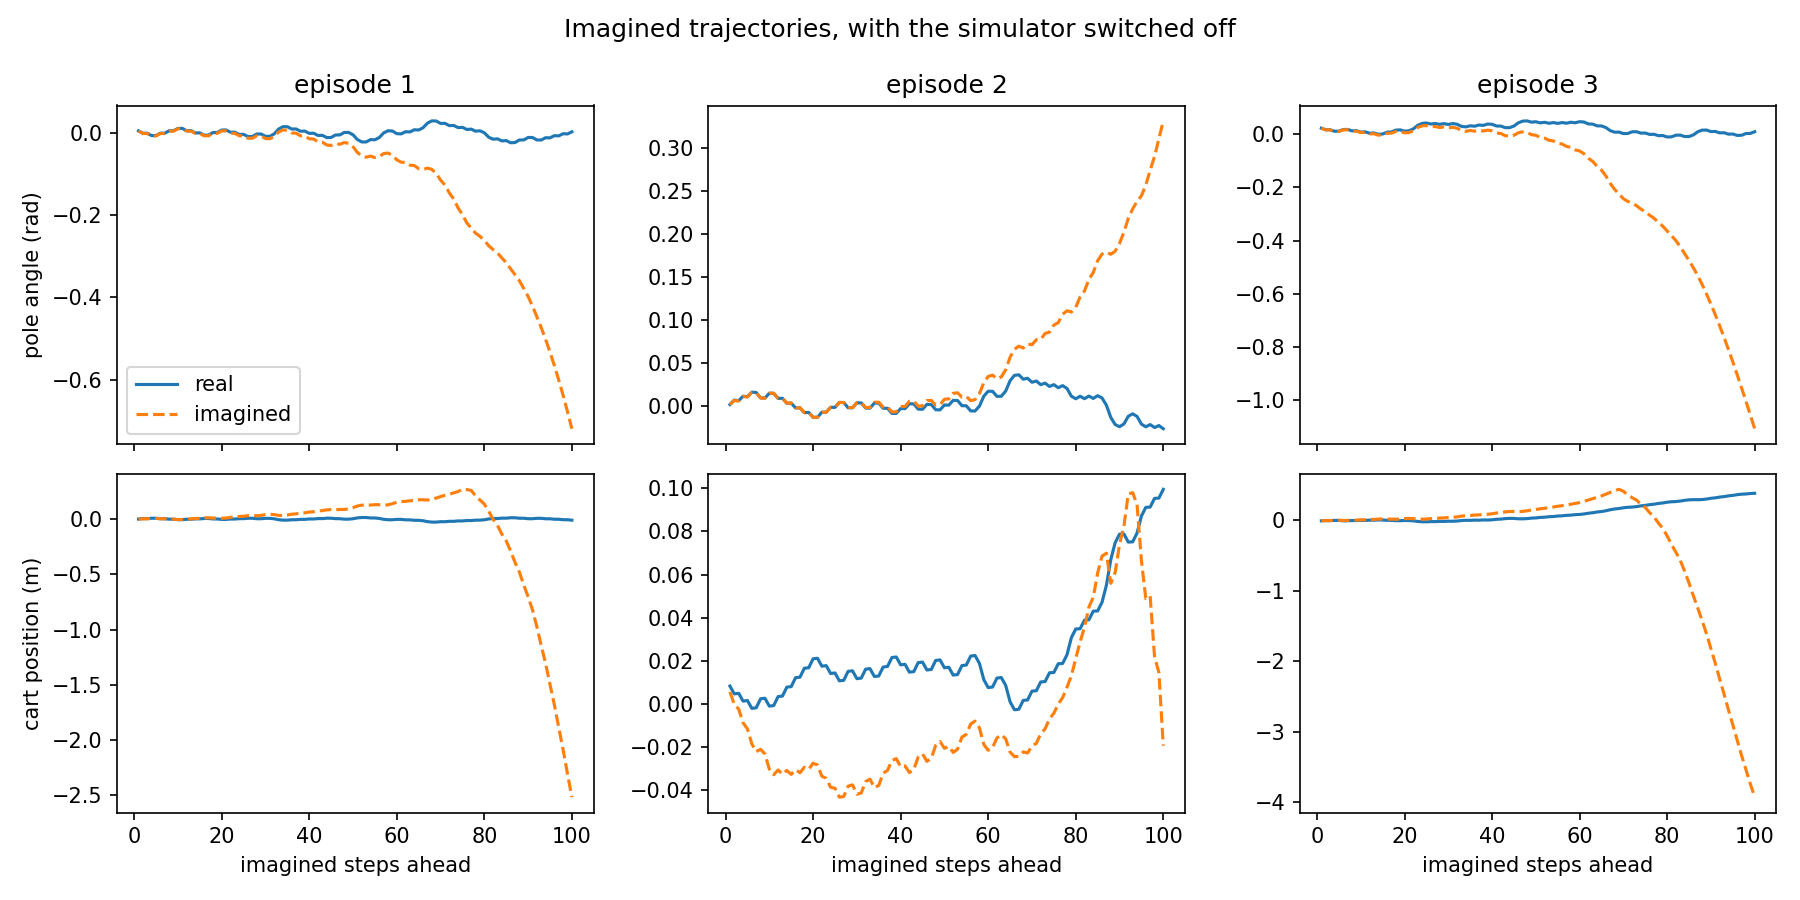
Imagined versus real trajectories for pole angle and cart
position across three held-out episodes, with the simulator switched off.
Solid is reality, dashed is the daydream. For thirty-odd steps you can barely tell them apart. Then it loses the plot — by step 100 the imagined pole has crashed to the floor in a game where the real pole never wobbled. It isn’t being stupid. It’s being slightly wrong a hundred times in a row.
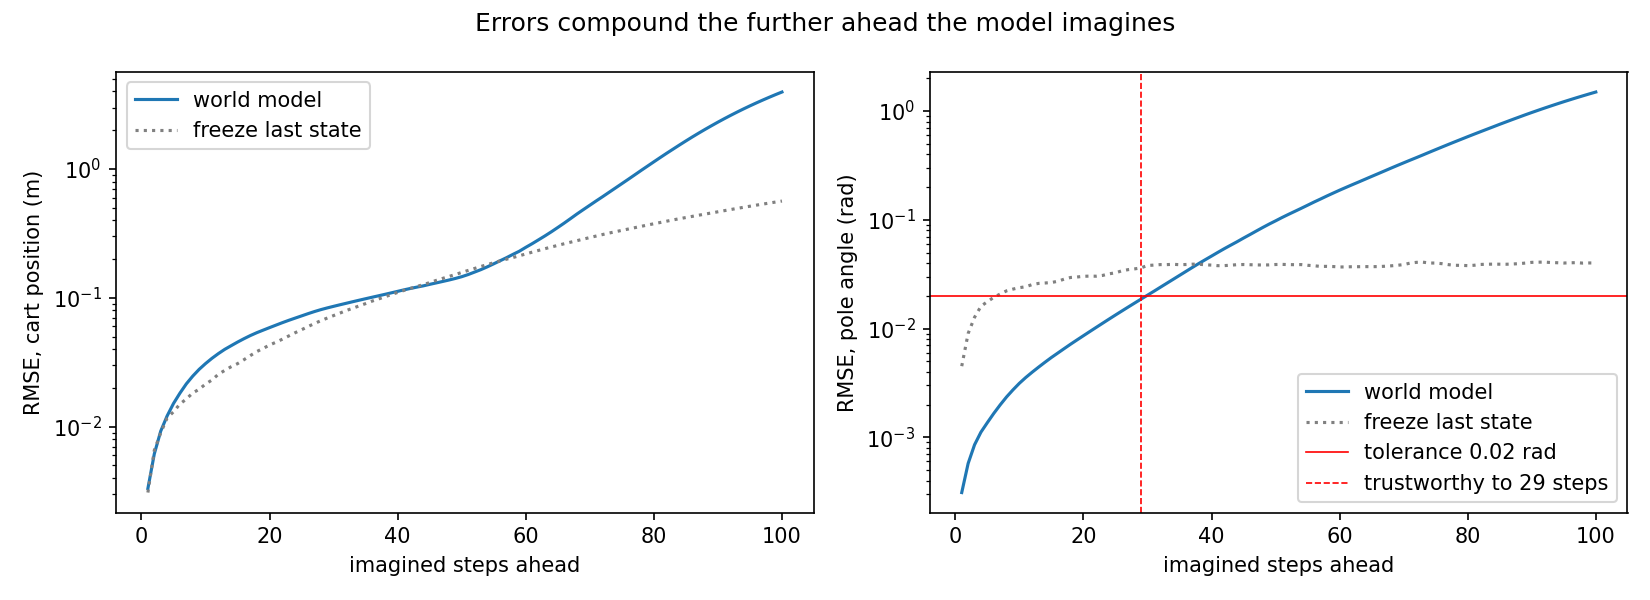
Prediction error versus rollout depth for cart position and pole
angle on log axes, with a freeze-the-last-state baseline for comparison.
|
Steps ahead |
Pole angle error |
|---|---|
|
1 |
0.00031 rad |
|
10 |
0.00314 rad |
|
20 |
0.00860 rad |
|
29 |
0.01866 rad |
|
50 |
0.09776 rad |
|
100 |
1.49452 rad |
Enjoy that bottom row. 1.49 radians is 86 degrees. The imagined pole isn’t leaning, it’s lying down having a rest.
The grey dotted line is my favourite thing in the project: the laziest model imaginable, assume nothing ever changes. Our sophisticated neural network beats that potato for 37 steps, after which you’d be better off assuming the universe had stopped. That’s not embarrassing, it’s the most useful measurement here, because it tells us how far the daydream can be trusted. Set a tolerance of 0.02 radians — a tenth of the way to falling over — and H = 29 steps. Beyond that, fiction.
One more honest failure. Can it predict when the pole falls?
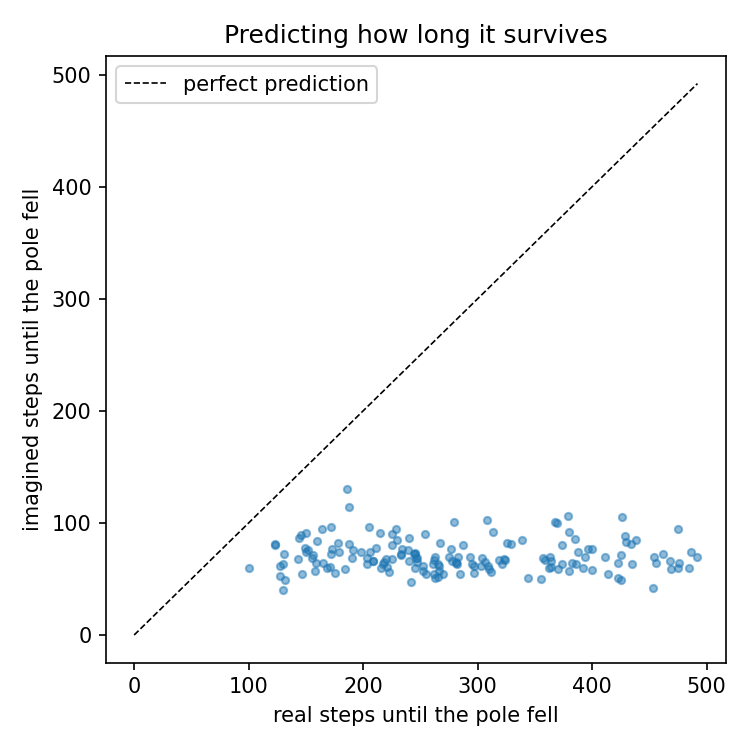
Scatter plot comparing the real step at which the pole fell
against the imagined step at which the model thought it would.
No. Median error: 202 steps — games that really lasted 300 get predicted to end around step 60. But look at why: in the daydream, the pole really does fall around step 60. The crash detector is accurately reporting a crash in an imaginary world that stopped resembling ours thirty steps earlier. It isn’t lying. It’s describing a different universe, very competently.
5.5 Acting by dreaming
At every real moment: invent 200 random sequences of shoves, each 15 long. Daydream all 200 inside the model. Score each dream. Play the first shove of the winner. Throw away the other 199. Repeat.
(Fifteen, not the 29 we measured. Not a typo, and the reason is interesting enough to be one of the lessons at the end.)
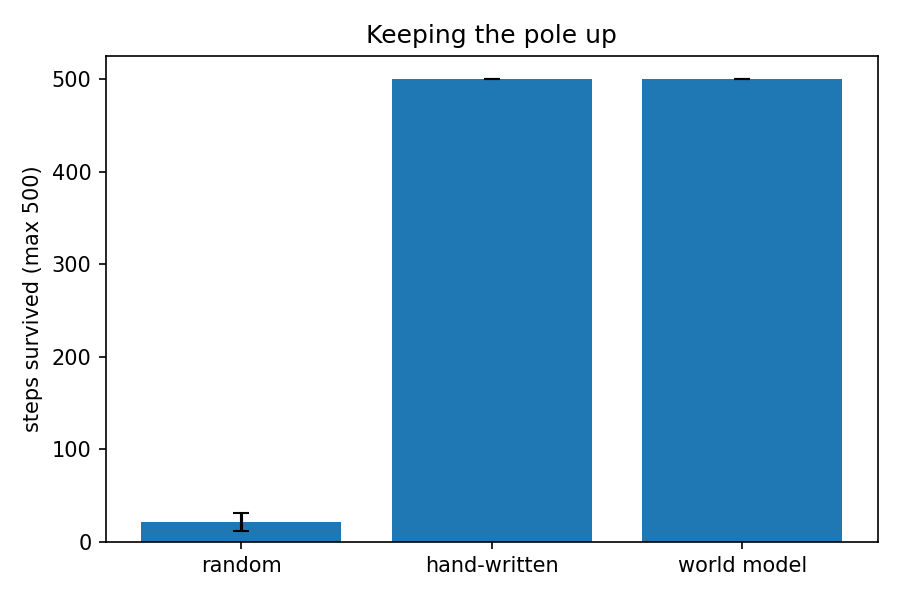
Bar chart of steps survived by random actions, the DQN baseline,
and the world-model planner.
|
Agent |
Steps survived (max 500) |
Time per decision |
|---|---|---|
|
Coin flips |
21.5 ± 9.8 |
instant |
|
Hand-written controller |
500.0 ± 0.0 |
instant |
|
World model planner |
500.0 ± 0.0 |
2.94 ms |
A perfect score on every one of a hundred episodes, from a network never told what “good” means — we only defined that after training finished.
One disclosure, because leaving it out would be cheeky: for the first 8 steps of each episode the planner doesn’t plan, it uses the three-line controller from 5.1, because a blank memory has no idea how fast anything is moving. Eight steps out of 500 isn’t where the result comes from, but it is in the numbers.
And it ties that napkin controller. If balancing a pole is all you want, the napkin wins, it’s free, and you should go use it. Balancing a pole is not what we want.
5.6 Changing the goal without touching the model
Here’s the bit the whole article has been walking towards. I would like the cart parked at x = +1.0. Watch what I have to do.
I wrote a function. That’s the change. That’s all of it. Same weights, no new data, no training, zero steps of real practice. The model doesn’t know the goalposts moved, because it was never aiming at them. All I changed is which of its daydreams I go looking for.
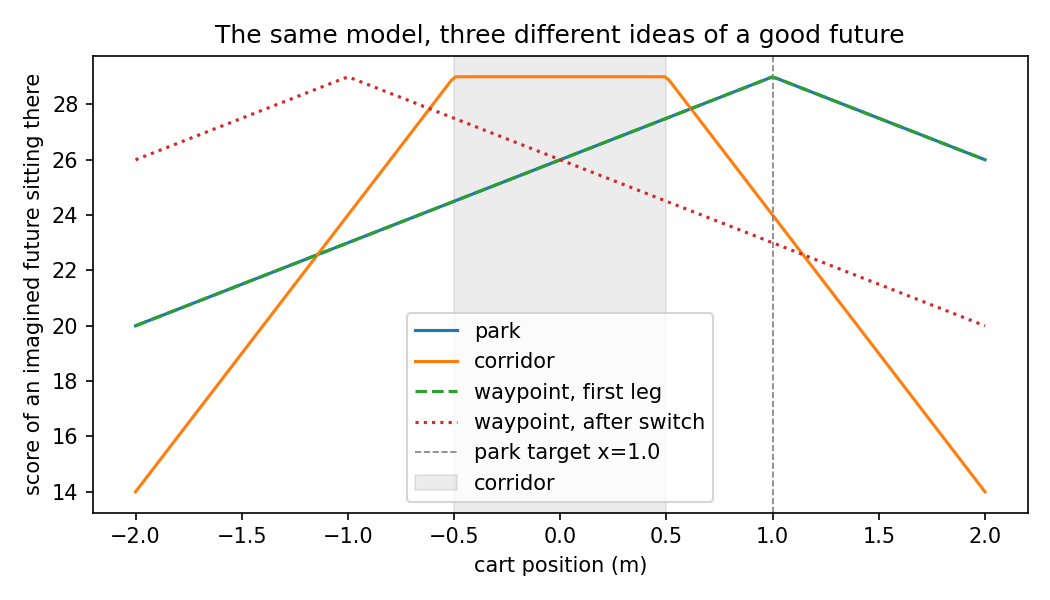
The park, corridor and waypoint scoring functions evaluated
across the rail, showing how the same imagined future is rated differently by
each goal. The waypoint goal is drawn twice, before and after its switch.
Goal A: park the cart at x = +1.0
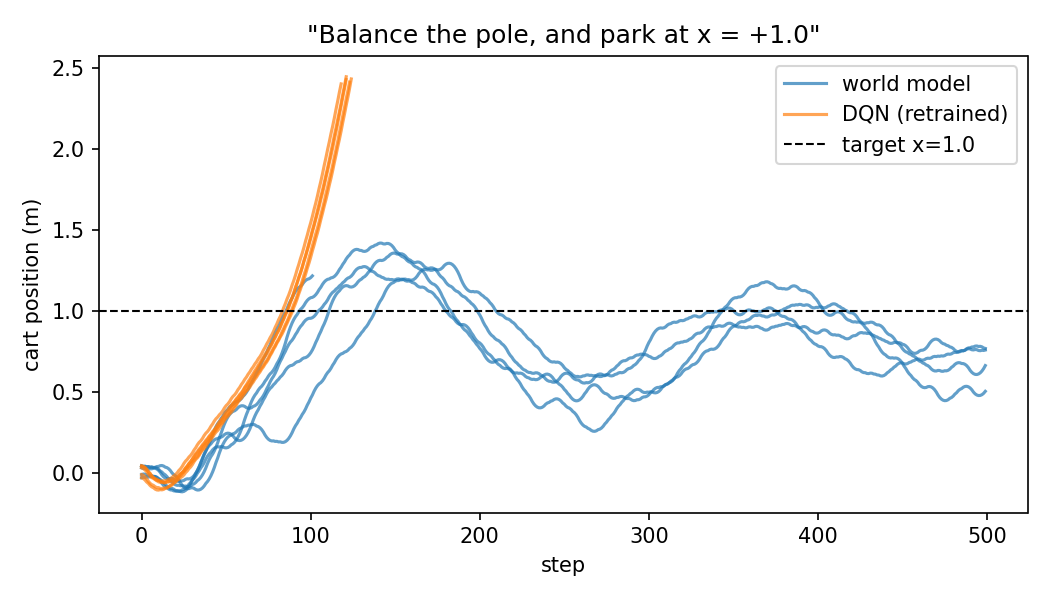
Cart position over time for the world-model planner and a
retrained DQN, both asked to balance the pole and park at x = +1.0.
Blue is our planner, told to park; orange is the Part 3 DQN, retrained from scratch at a cost of 24,437 real steps. The planner climbs to the target, overshoots, comes back, and pootles around the line, averaging 0.469 m from it. Not elegant, but it understood an assignment nobody trained it for. It doesn’t always survive, though: 51 of the 100 episodes last the full 500 steps, the rest drop the pole along the way, worst at step 56, dragging the average to 350.
|
Distance from target |
Survived |
Cost to acquire the goal |
|
|---|---|---|---|
|
World model, told |
0.469 m |
350 steps |
0 real steps |
|
DQN, retrained |
0.548 m |
212 steps |
24,437 real steps |
|
DQN, never told |
0.957 m |
350 steps |
– |
Three ways to be handed a goal. Being told beats being retrained, lasts substantially longer, and is free.
Goal B: stay in a narrow corridor
“Balance, but never let the cart past ±0.5.” The rail allows 2.4, so this rule is five times stricter than anything in the training data — and the most realistic of the three, since real requirements are usually “never go there”.
We do well. The DQN does better.
|
Steps spent outside the corridor |
Survived |
Cost |
|
|---|---|---|---|
|
DQN, never told |
21.1% |
350 |
— |
|
Hand-written controller |
23.3% |
500 |
— |
|
World model, told |
2.3% |
454 |
0 real steps |
|
DQN, retrained |
0.0% |
410 |
46,117 real steps |
Being told the rule took violations from 21.1% to 2.3%, which is what I set out to demonstrate. Then the retrained DQN scored a flawless zero: give something 46,117 steps of practice at one constraint and it gets very good at one constraint. Being told gets you most of the way there instantly. Training gets you the rest, eventually, at a price.
Goal C: chase a moving target
“Go to x = +1.0, hold for 100 steps, then come back to x = −1.0.” The one that stops looking like balancing and starts looking like a robot doing a job. We lose this one, and it’s the most instructive result in the section.
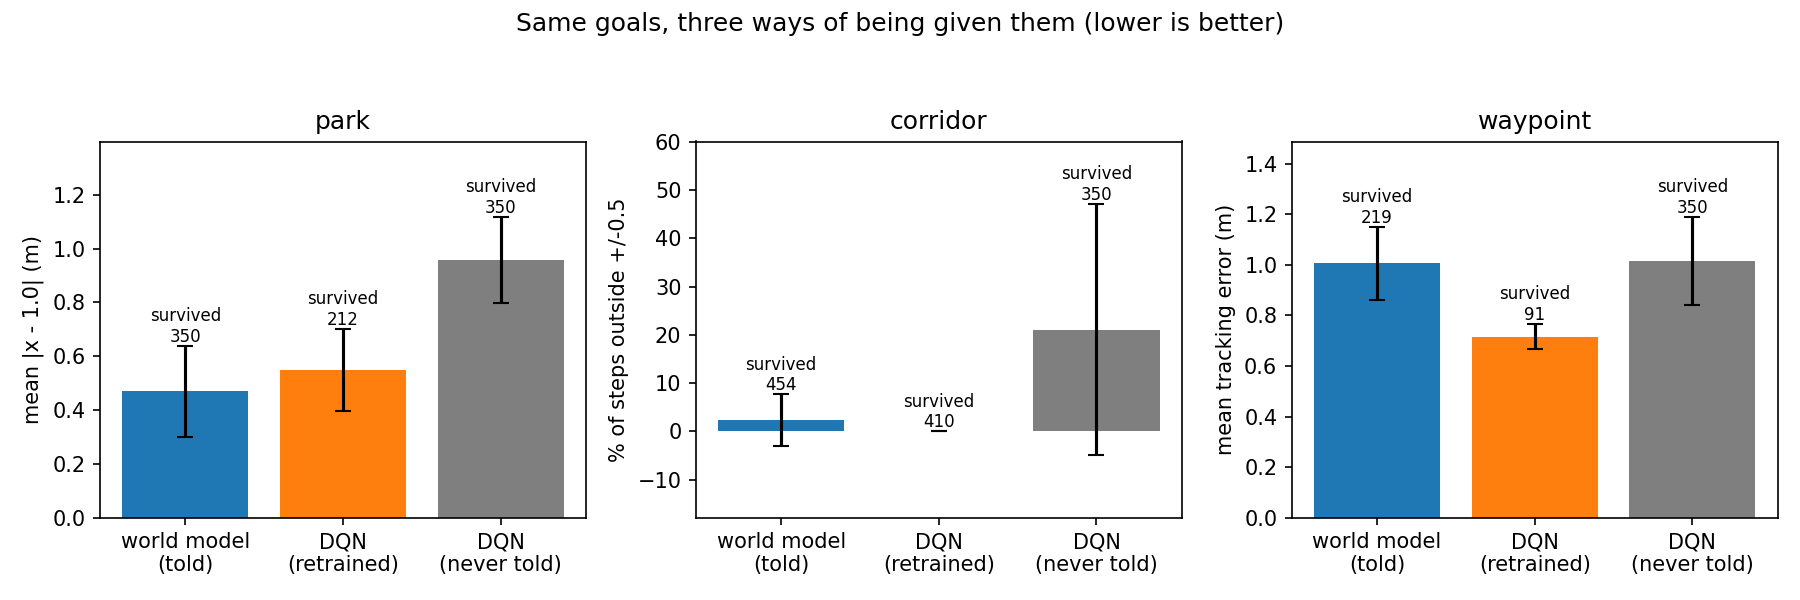
Grouped bar chart comparing three ways of giving an agent a
goal — untold DQN, retrained DQN, and world model told at run time — across the
park, corridor and waypoint tasks.
|
Tracking error |
Survived |
|
|---|---|---|
|
World model, told |
1.006 m |
219 steps |
|
DQN, retrained |
0.716 m |
91 steps |
|
DQN, never told |
1.017 m |
350 steps |
Read both columns before you believe the first one. The target moves at step 100; the retrained DQN dies at step 91. Its lovely tracking error was earned entirely on the easy first leg. It’s not better, it’s being graded on a shorter exam — my metric quietly rewarding failure, which I only spotted because survival sat in the next column. If you take one practical thing from this section, make it that.
Now the row which will make us humble again. The agent never told about the task at all scores 1.017 m; we score 1.006 m. Telling our planner the goal bought about a centimetre, which makes us statistically indistinguishable from an agent that ignored us. Hauling a balanced pole two full metres needs deeper lookahead than 200 random sequences provide — most drop the pole, and the survivors all amount to “stay near the middle”. Sitting at the origin and letting the targets come to you turns out to be a decent strategy here, and we found it by accident.
(It got worse before it got better: the first version froze the target for the whole daydream, so a dream looking 29 steps ahead from real step 90 never saw the switch at step 100 coming. Fixing that took the error from 1.18 m to 1.01 m.)
The bill
Every decision means dreaming 200 futures. The DQN, a single pass through a small network, answers in 0.16 ms. We don’t.
|
What we asked for |
Steps dreamed ahead |
Time per decision |
Versus the DQN |
|---|---|---|---|
|
Balance |
15 |
2.94 ms |
18x |
|
Stay in the corridor |
15 |
3.06 ms |
19x |
|
Park at the target |
29 |
5.44 ms |
34x |
|
Chase waypoints |
29 |
5.47 ms |
34x |
The goal changes the bill: jobs that need the cart to travel dream twice as deep and cost twice as much, so quoting one headline latency for “the planner” would be quietly flattering. And 18x to 34x is less than I expected — two hundred dreams ought to cost more against a single forward pass, and would, if the GPU weren’t dreaming all two hundred side by side at once.
The DQN is fast because it isn’t thinking. We’re slow because we are. Five milliseconds a step is what it costs to change your mind after training has finished, and on this evidence that’s a bargain.
···
Part 6: What I’d tell you before you build one
Most of your trouble will not come from the neural network, or at least mine didn’t.
Your definition of “good” can silently forbid the solution
I told the planner to take the cart to x = +1.0. It took the cart to −1.2 and fell over.
I suspected the model. The model was fine. The problem was a lovely piece of physics I’d failed to account for: to move a cart-pole right, you must first push left. Broom on your palm again — you first tip it the way you want to go, then chase it. Shove the cart right and the pole tips left, so you must chase it leftwards or drop it.
Now look at what my scoring function did to that plan. I scored each daydream by its average distance from the target across the whole dream, which feels unimpeachable. But the opening move of the only manoeuvre that works takes the cart further away. Every dream containing the correct answer scored badly, and the planner correctly discarded it. It wasn’t failing to find the solution — it was finding it, evaluating it exactly as instructed, and binning it. Scoring by where the dream ends up fixed it in one line.
The lesson: when a planner underperforms, suspect the objective before the model. A broken model is obvious, because the predictions are visibly wrong. A broken objective fails quietly, in a plausible direction, and looks exactly like a model that isn’t good enough.
Cover the actions you’ll ask about, not just the situations
Everyone knows training data must cover the situations you care about. Less obvious: it must also cover the actions.
Our collector corrected every wobble instantly, so the cart never went anywhere — gorgeous balancing data, not one example of a journey. Fine until Goal A, where the whole task is a journey. The model had never watched one and was confidently, fluently wrong. The fix was one number: a small nudge added to the controller’s decision, different each game, so some games balance in place and others balance while sliding along the rail.
The lesson: your planner will ask about action sequences no sensible policy would ever produce, because it’s searching. If your data contains only sensible behaviour, those questions are asked into a void — and the model will answer anyway.
The trustworthy horizon is a ceiling, not a recommendation
We measured that the dream holds up for 29 steps. I assumed planning would improve all the way to 29 and collapse after.
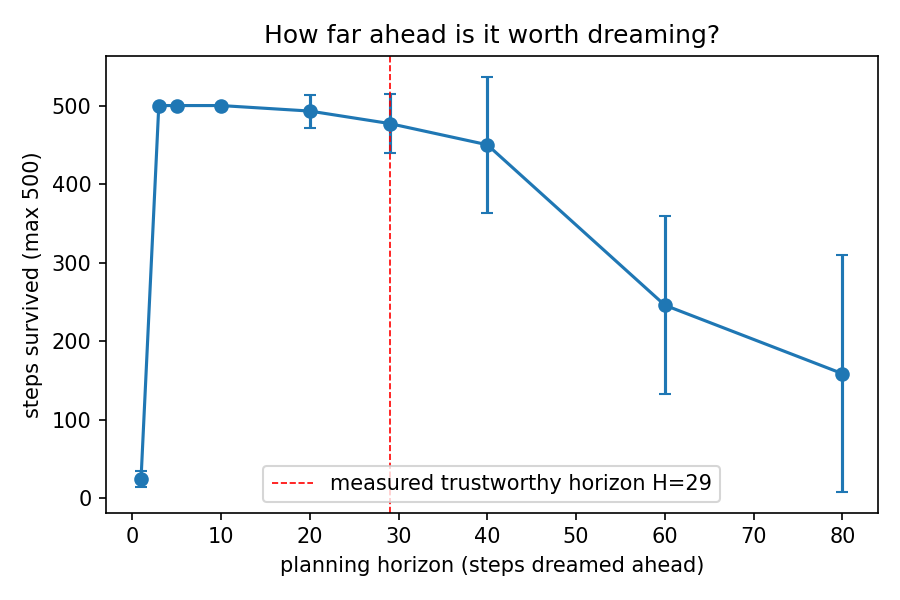
Steps survived as a function of planning horizon, sweeping the
number of steps the planner dreams ahead.
|
Steps dreamed ahead |
Steps survived |
|---|---|
|
1 |
25.0 |
|
3 |
500.0 |
|
5 |
500.0 |
|
10 |
500.0 |
|
20 |
493.0 |
|
29 |
477.1 |
|
40 |
450.1 |
|
60 |
245.9 |
|
80 |
158.8 |
Both ends behave: at a horizon of 1 the planner is hopeless, because seeing one step ahead isn’t planning, it’s twitching, and past 29 it collapses as the drift measurement predicted. The middle is where I was wrong. It’s already perfect at a horizon of 3, and from 20 onwards slowly gets worse — well before the model stops being accurate.
The culprit isn’t the model, it’s the search. We pick the best of 200 randomly generated sequences, and the longer the sequences, the worse a random sample covers the options. There are 8 possible 3-step plans and we try 200, so we find the best one every time, twice. There are about half a billion 29-step plans and we still try 200, which is indistinguishable from trying none.
This is why the balancing planner dreams 15 steps, not 29. The 29 is a ceiling — the depth beyond which the model lies to us — not a recommendation. The goals that need the cart to travel still use the full 29, because they need the lookahead enough to pay the search cost.
The lesson: two separate things limit how far ahead you can usefully plan — how long your model stays accurate, and how well your search covers the space. Everyone measures the first. The second usually bites, and bites earlier.
···
So what have we actually got?
A neural network of 13,635 numbers that learned how a cart behaves by watching one for a few hundred games, and which can now be told — at runtime, by editing a function, for free — to park somewhere it has never been asked to park.
It isn’t going to run a robot. It ties a three-line controller at the game it was built for, loses one goal outright and half-loses another, and takes up to five and a half milliseconds to decide anything. But the shape is right, and the shape is what scales.
It thinks from scratch every step, two hundred fresh daydreams every moment, never keeping a single insight. The fix is to let an agent practise inside the daydream until the good moves become reflexes, then send it out with no deliberation. Train in the dream, perform on instinct. That’s essentially DeepMind’s Dreamer, the natural next thing to read.
It only ever imagines one future, with the serene confidence of a man who has never been wrong and also never checked. A model with no way to say “honestly, could go either way” can’t stop small uncertainties snowballing into large wrong answers — precisely the drift we measured. Serious world models track the range of what might happen instead: stochastic latent states, hidden variables holding a spread of possibilities rather than one number, in a design called the RSSM, or Recurrent State Space Model.
But the trick underneath all of it is the one we just built. Learn how the world works, not what to do about it. Then do your failing somewhere imaginary, where it’s free.
The complete code with explanations is hosted in this github repository: https://github.com/AnubhabBanerjee/CartPole-Daydream