

1. Before the LLM writes anything
1.1 What is Jev?
Most AI applications do not always need another paragraph of generated text. Sometimes they just need a decision.
Let’s imagine opening a support inbox at 9 a.m. and finding 340 new messages. Before anyone writes a reply, the system may need to decide which team should handle the message, whether it is urgent, or whether the customer is asking for a refund. The same pattern shows up in AI agents: before calling a tool, the system may first need to decide whether that action is safe.
This is where Jev gets interesting.
Released by TypeSafe AI in September 2026, Jev is presented as a System One model: not a replacement for large language models, but a more specialized layer for fast, structured decisions (ex: tool calls). Instead of generating a sentence and then asking software to interpret it, Jev returns a choice from a predefined set of answers together with probabilities.
That puts it in a different part of the AI stack. LLMs are good at open-ended language, explanation, and reasoning. Jev is aimed at the many smaller decisions surrounding that work: classification, routing, filtering, safety checks, and other tasks where the output is known in advance.
1.2 Why I wanted to test it
There are already plenty of ways to solve these problems. Rules are fast and cheap, but they become brittle as language changes. Traditional classifiers can be accurate, but they require labelled training data and retraining when the task changes. And an LLM can usually return the answer as JSON, although that means using a generative model for a task that may only require choosing between a few options.
The early results around Jev were what caught my attention. In a 400-item PriorBench classification test, Jev scored 95.9% compared with 77.2% for keyword rules. In another test published by Dan Shipper’s Every.to, Jev took a median of 0.35 seconds per passage check, versus 8.83 seconds for Fable 5.1 at high effort. Those numbers come from specific benchmarks, so I would not treat them as universal comparisons—but they were enough to make me curious.
There is also the question of confidence. If an LLM writes “I am 90% sure,” how often is it actually right? In Supa Journal’s Japanese benchmark on 18 September 2026, four chat models had confidence errors of 0.078–0.163 on a scale from 0 to 1, compared with 0.002–0.047 for Jev. I will explain how that error is measured later, because the meaning of these numbers matters as much as the speed.
I was particularly interested in the confidence scores. Jev does not just return a label; it gives probabilities for the available choices. That raises a more useful question than raw accuracy: when the model says it is confident, can you actually trust that confidence?
So I decided to test it myself. I compared Jev with Qwen on 3,080 bank messages, looking not only at which model made the right decision, but also at speed, confidence, and what happened when the available answers did not quite fit the input.
2. Where the idea of Jev came from
Let’s talk a bit about the foundation of Jev to understand the reason of creating this system.
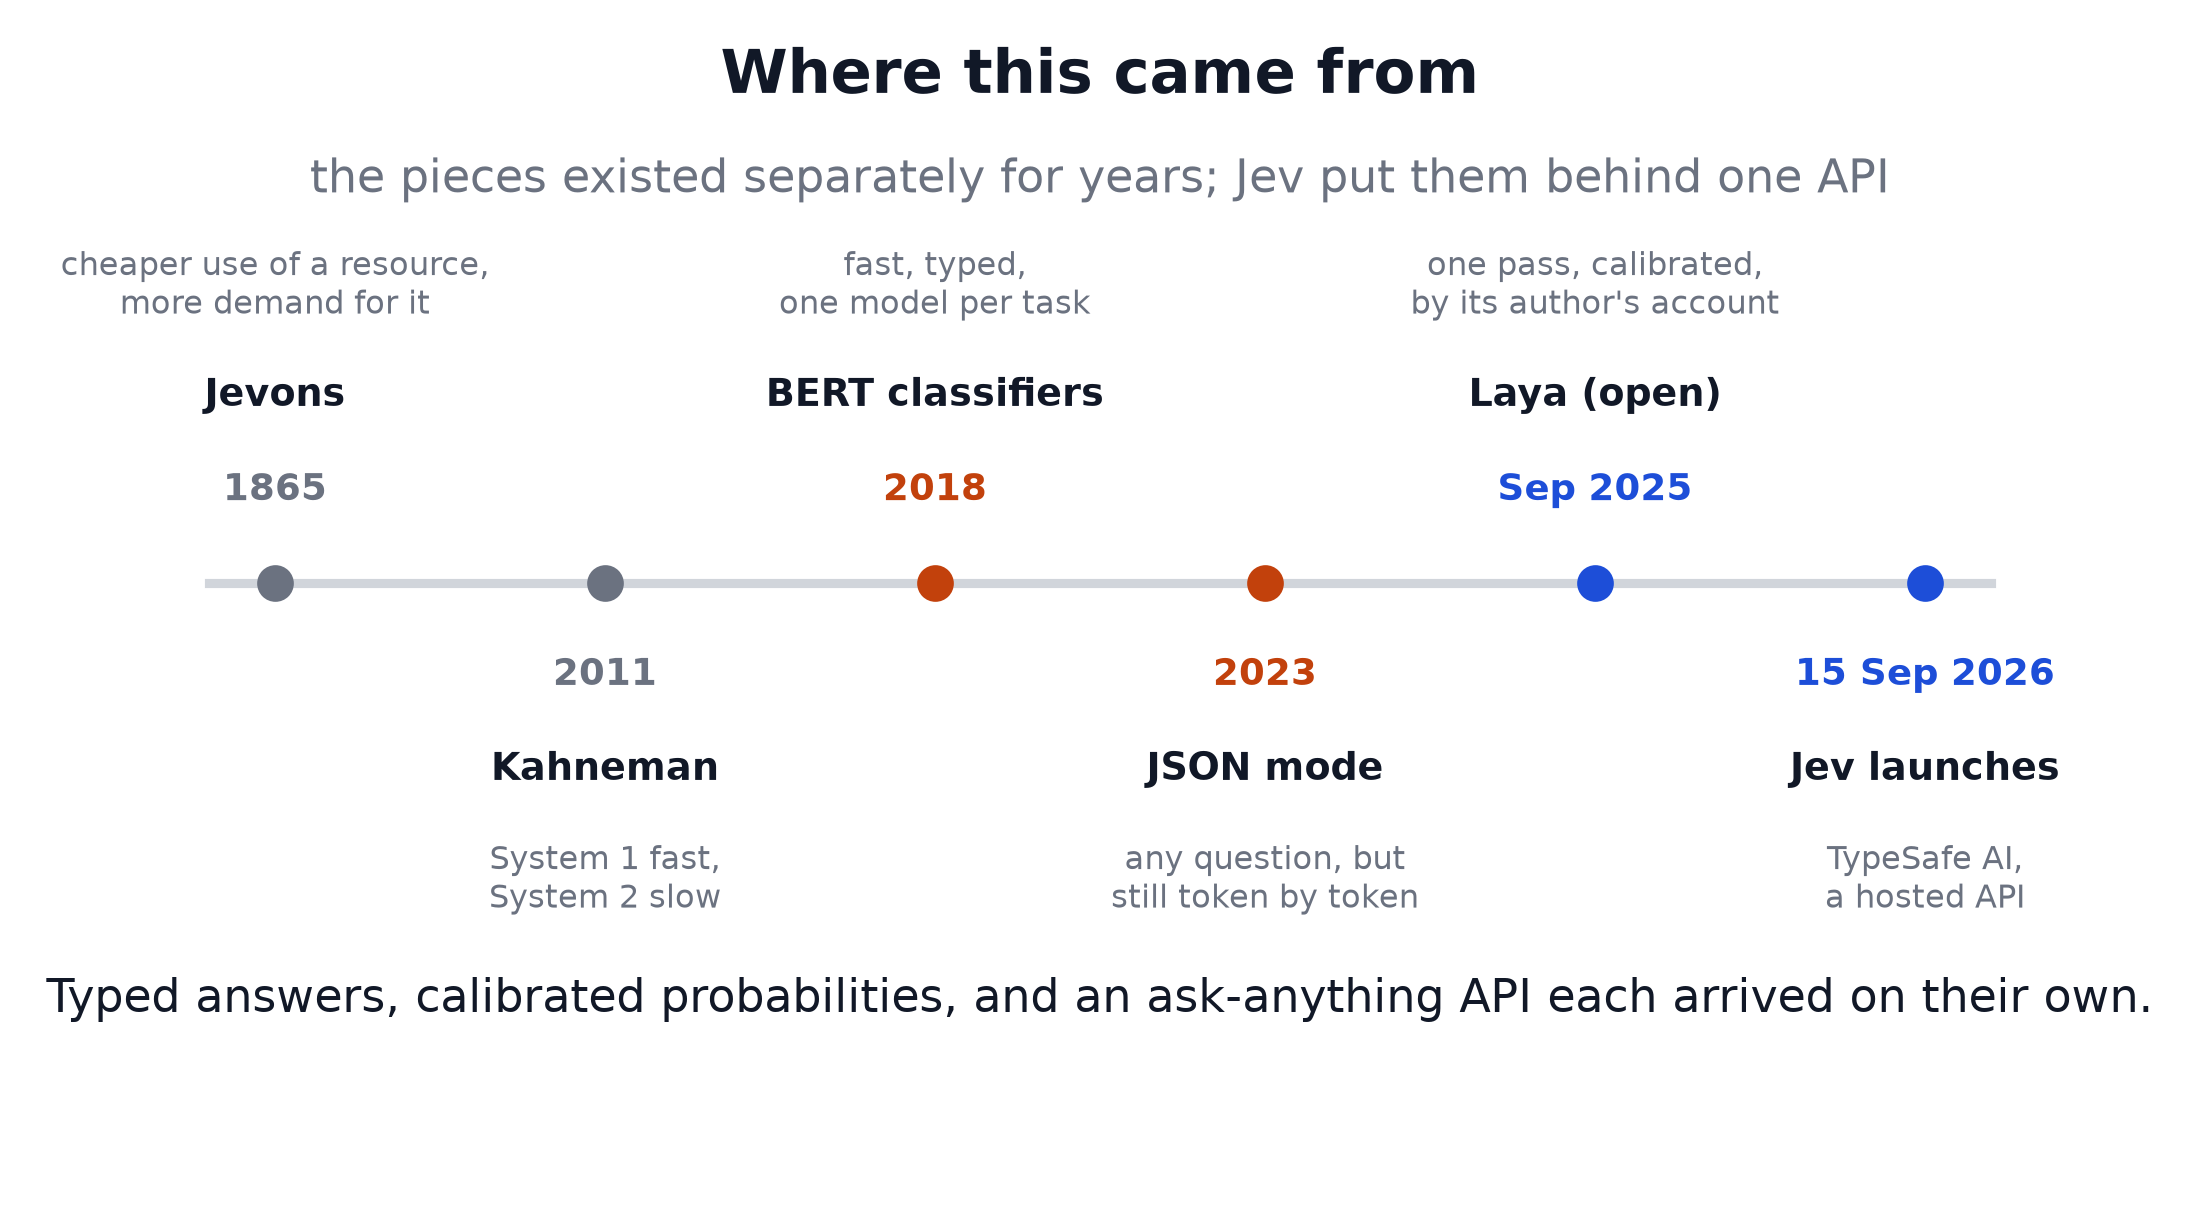
Jev is named after William Stanley Jevons, the 19th century economist behind what became known as the Jevons paradox. In 1865, he argued that making steam engines more efficient could actually increase coal consumption, because cheaper power encouraged people to use more of it. The name fits the ambition here: if AI decisions become cheap and fast enough, developers may start using them in places where calling a large model would previously have felt excessive.
“System One” comes from Daniel Kahneman’s Thinking, Fast and Slow. Kahneman used System 1 to describe fast, intuitive judgments and System 2 for slower, more deliberate thinking. It is a useful metaphor for Jev’s intended role, although it says more about what the model is for than how it works internally.
On the other hand, the technical idea is not entirely new. BERT-style classifiers have been assigning text to categories for years, but their labels are usually fixed during training. LLMs later made this more flexible through features such as JSON output and constrained decoding, where the model is restricted to a required format. The difference is that an LLM still generates its answer token by token.
System One models try to sit somewhere between those approaches: flexible prompts and predefined outputs, without needing to generate a full textual response. An open model called Laya explored a similar idea in 2025, and TypeSafe AI launched Jev in September 2026 after two years of private development.
What interested me was how quickly people started testing it. Independent benchmarks appeared within days of launch, giving some early signals about where the approach works well—and where the results depend heavily on the task.
3. What Jev actually gives you
The easiest way to think about Jev is as a multiple-choice system. You give it some context, ask a question, and define the answers it is allowed to choose from. Jev then returns its choice, the probability it assigns to each option, and a confidence score.
In the API, the input context is called the state. That could be a customer message, a proposed tool call, or any other piece of application data. Each question also includes a schema that defines what a valid answer looks like. For a Choice question, you can provide up to 255 possible options. This is what type-safe means in practice: Jev has to stay within the structure you give it. If the only choices are billing, technical support, and other, it cannot suddenly return a fourth department.
But that does not mean the answer is always right. This was one of the things I wanted to pay attention to in my testing. A model can produce a perfectly valid answer and still make the wrong decision. PriorBench showed a good example of this: when Jev was given 30 messages that did not belong to any available category, with no “none of these” option, it still chose one of the listed categories every time, with confidence of at least 0.99.
That makes schema design more important than it first appears. If an input might not fit any of your categories, you need to give the model a way to say so. In practice, defining the available answers is part of the reasoning system itself, not just a formatting detail.
4. Why Jev behaves differently from an LLM
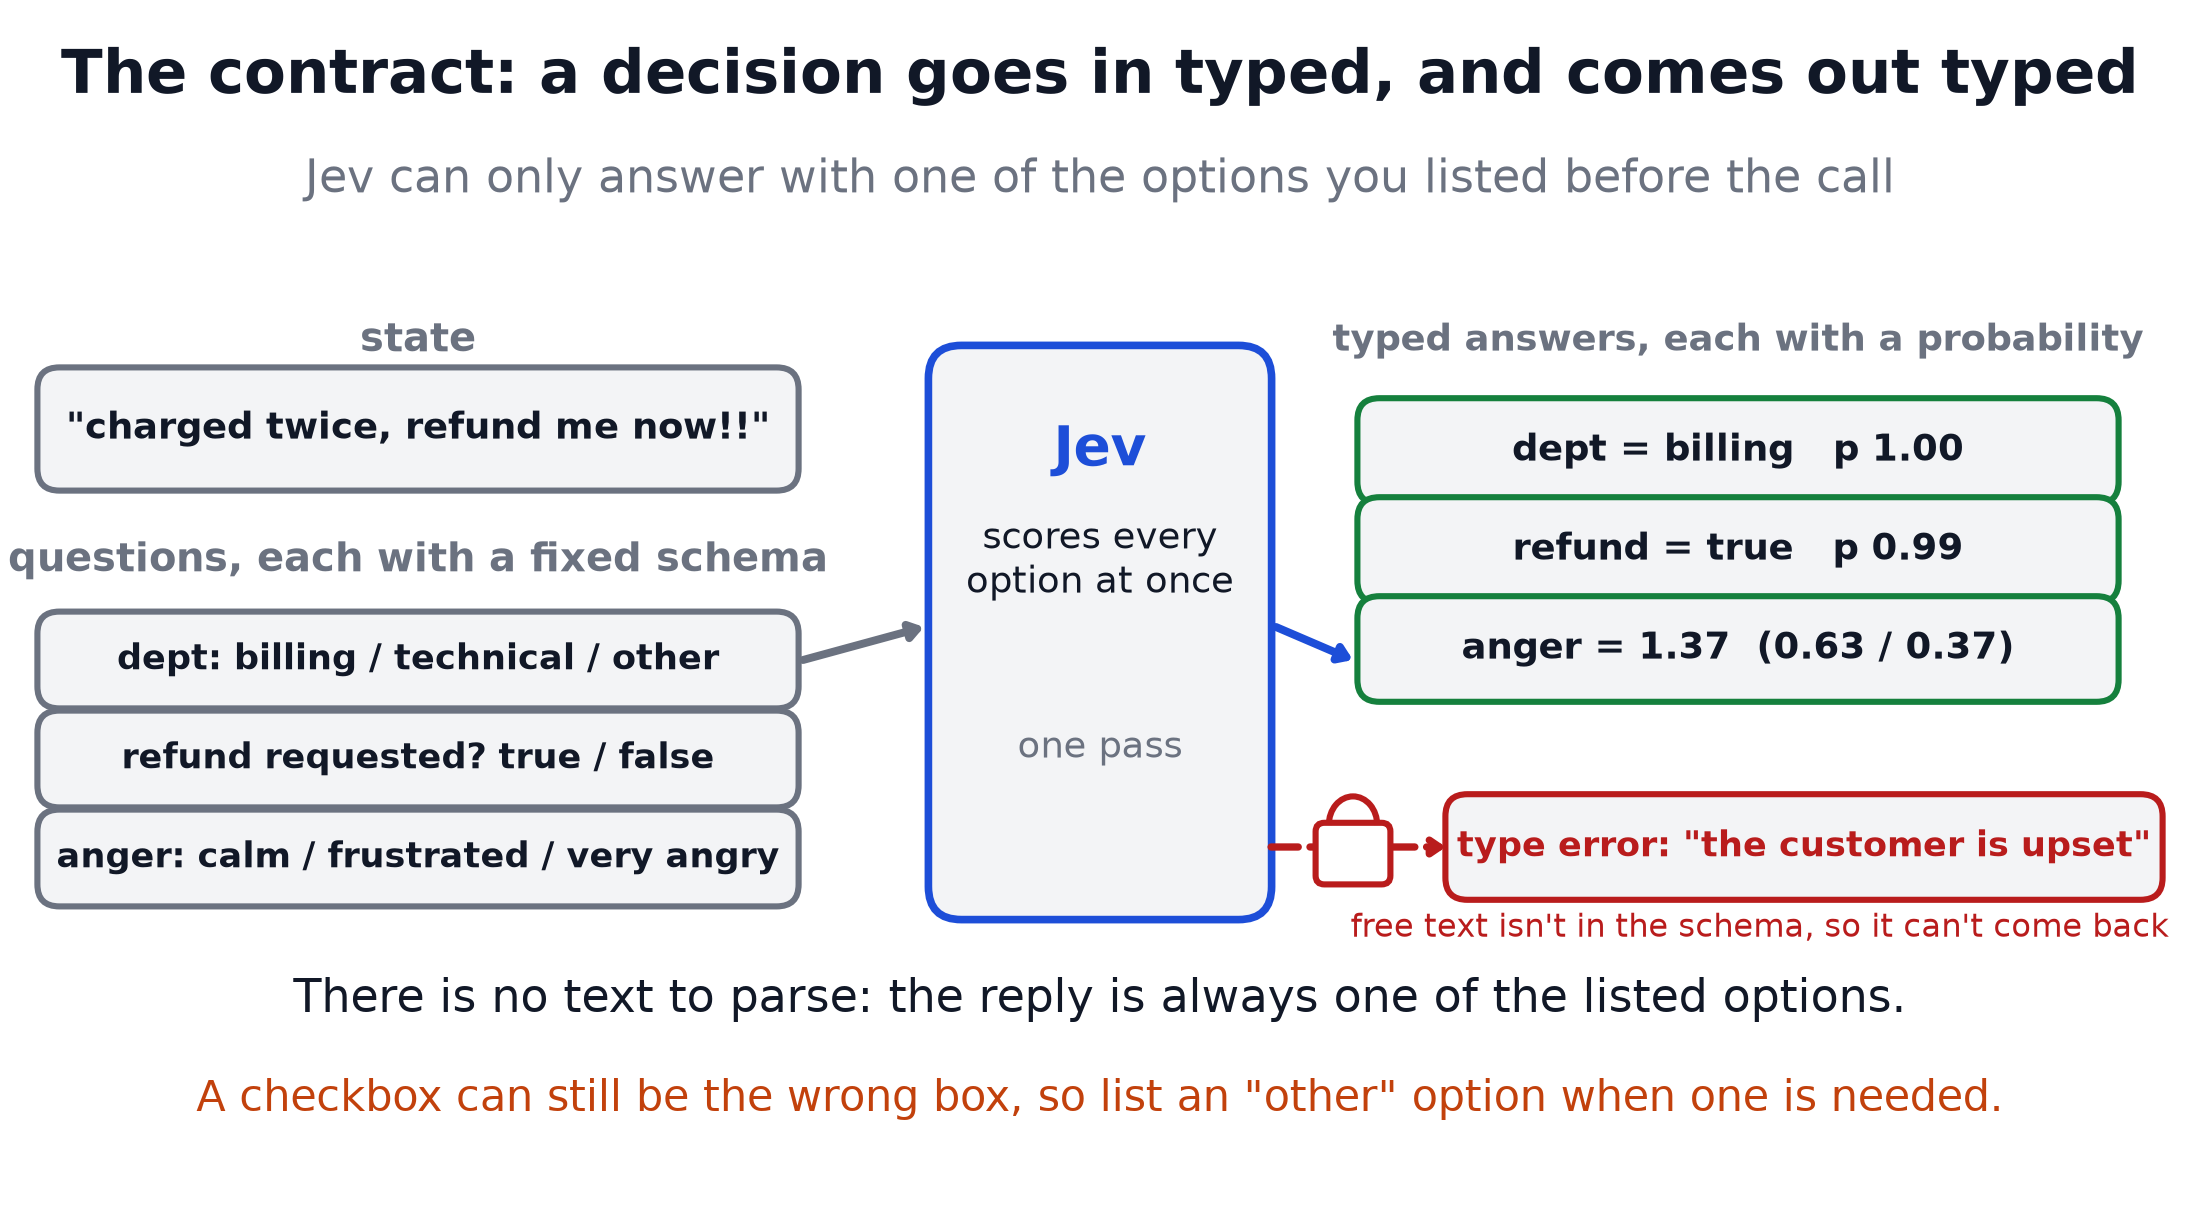
The beauty of Jev is the fixed answer list, which makes it fundamentally different from a chat model. An LLM generates its response step by step. It predicts one token at a time, then uses what it has already generated to predict the next one. This is known as autoregressive decoding. Even something as simple as {"team": "billing"} still has to be produced over several generation steps.
Jev, according to TypeSafe, does not generate an answer this way. It scores the available choices in a single pass and returns their probabilities together. For a task where the possible answers are already known, that removes the need for a generation loop entirely. That difference also shows up in pricing: TypeSafe charges for input tokens only, currently $0.042 per million, with no output-token fee.
Faster does not mean instant
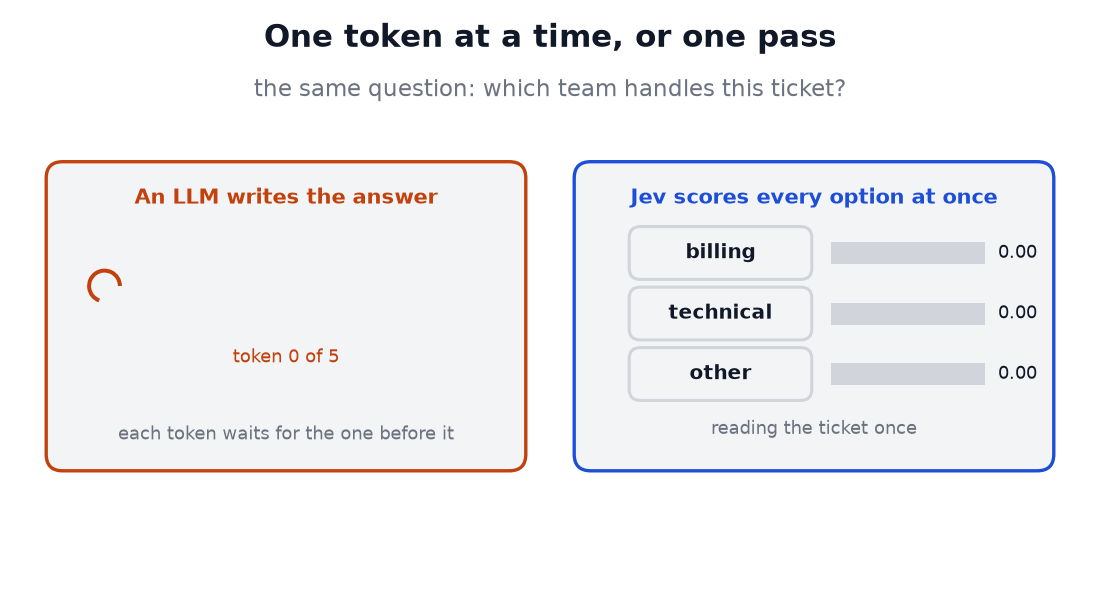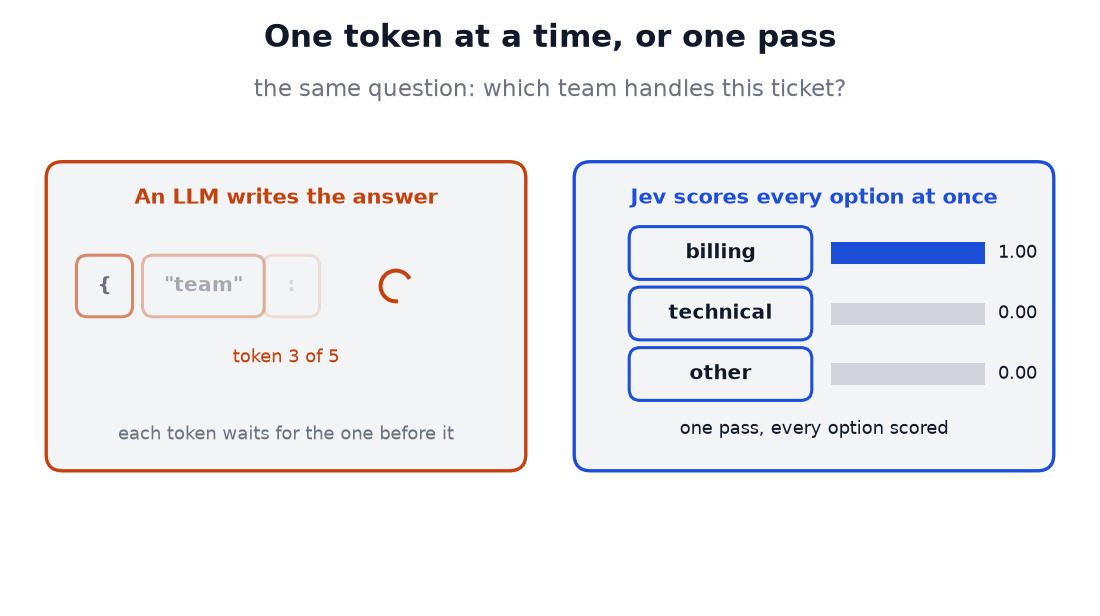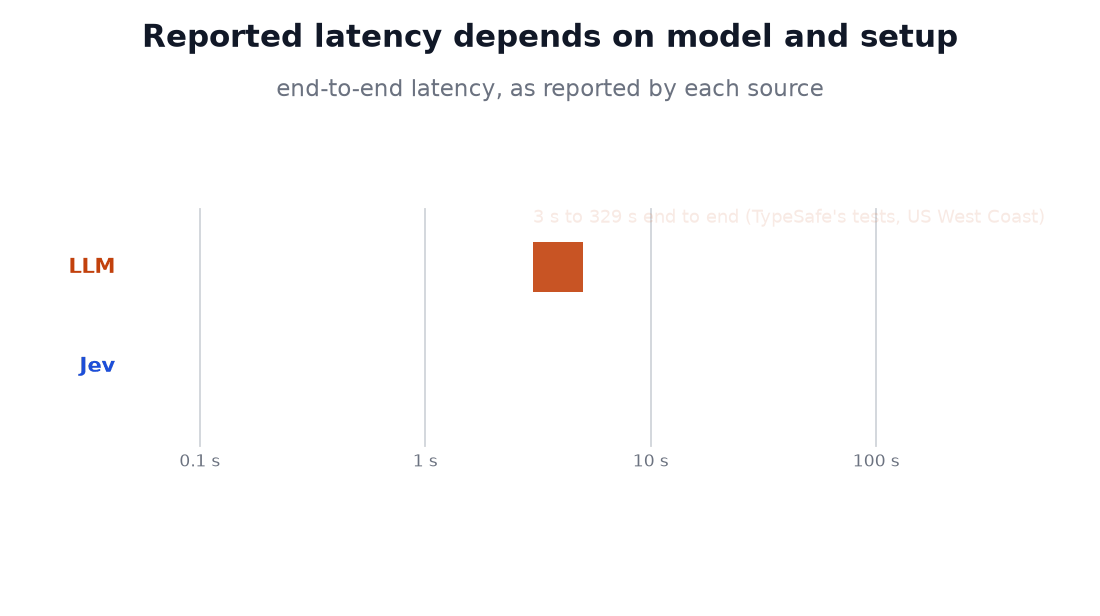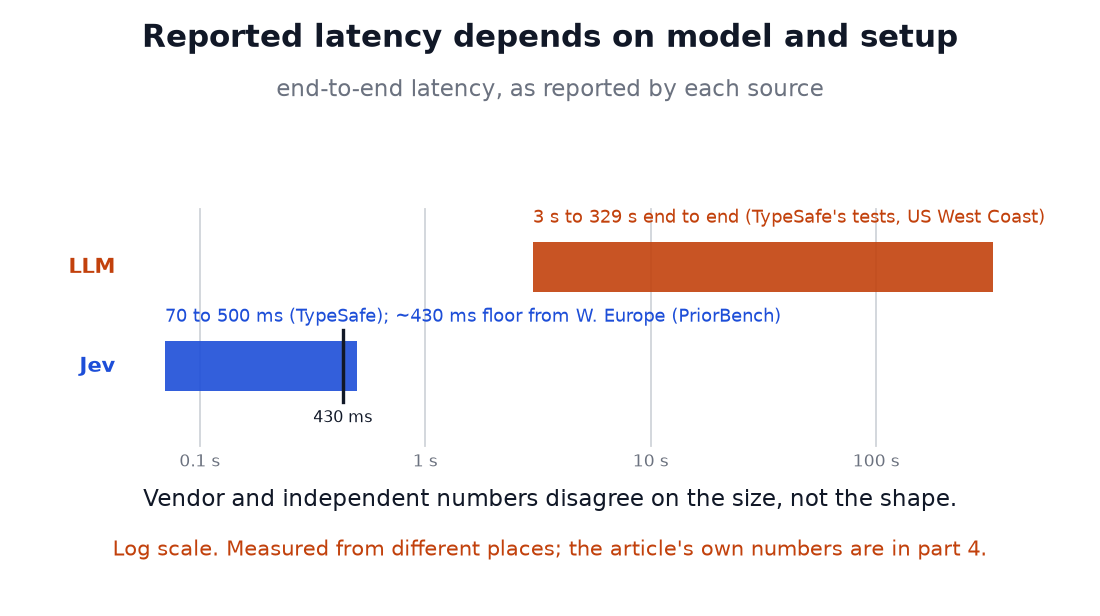
I would not take this to mean that Jev will always beat an LLM on latency. Input length, hardware, network conditions, and model settings all matter. In my test, Qwen sometimes returned very short answers in milliseconds. Moreover, Jev still has to read everything you send it. Hence, a long document takes more time, and costs more than a short message. What changes is what happens after the input has been read: Jev can score a fixed set of choices instead of generating a response token by token.
|
An LLM asked for JSON |
Jev |
|
|---|---|---|
|
Response |
Generated text; output constraints can enforce the allowed format |
An answer in the required format, with probabilities |
|
How it answers |
Generates one token after another |
Scores the options in one pass, according to TypeSafe |
|
Reported response times |
8.83 s median for Fable 5.1 in Every.to‘s test; 3–329 s in TypeSafe’s tests |
0.35 s in Every.to‘s test; 70–500 ms reported by TypeSafe on the US West Coast; about 430 ms minimum reported by PriorBench in Western Europe |
|
Pricing |
API services typically charge for input and output tokens |
$0.042 per million input tokens; output free |
|
Confidence |
A number written into the response if requested |
Probabilities over the options, plus a separate confidence field |
|
Other tasks |
Can write explanations, work through steps, and use connected tools |
Does not generate text, show reasoning steps, or look up information |
What we know—and what we do not
There is also a limit to how far we can explain what happens inside Jev. TypeSafe has not published its model size, training data, or full architecture, so this is still a black box. To measure this and easier to imagine, I take a related model, called Laya, and give it a useful example to see how this kind of system can work. Laya uses a ModernBERT encoder, which reads the input rather than generating text, and scores markers representing the available answer choices. Its confidence is then derived from the probability distribution across those choices.
That makes the idea easier to picture, but it does not mean Jev uses the same architecture. For my purposes, the more important question is what this design difference looks like in practice—which is what I wanted to measure in the benchmark.
5. Three ways to ask Jev a question
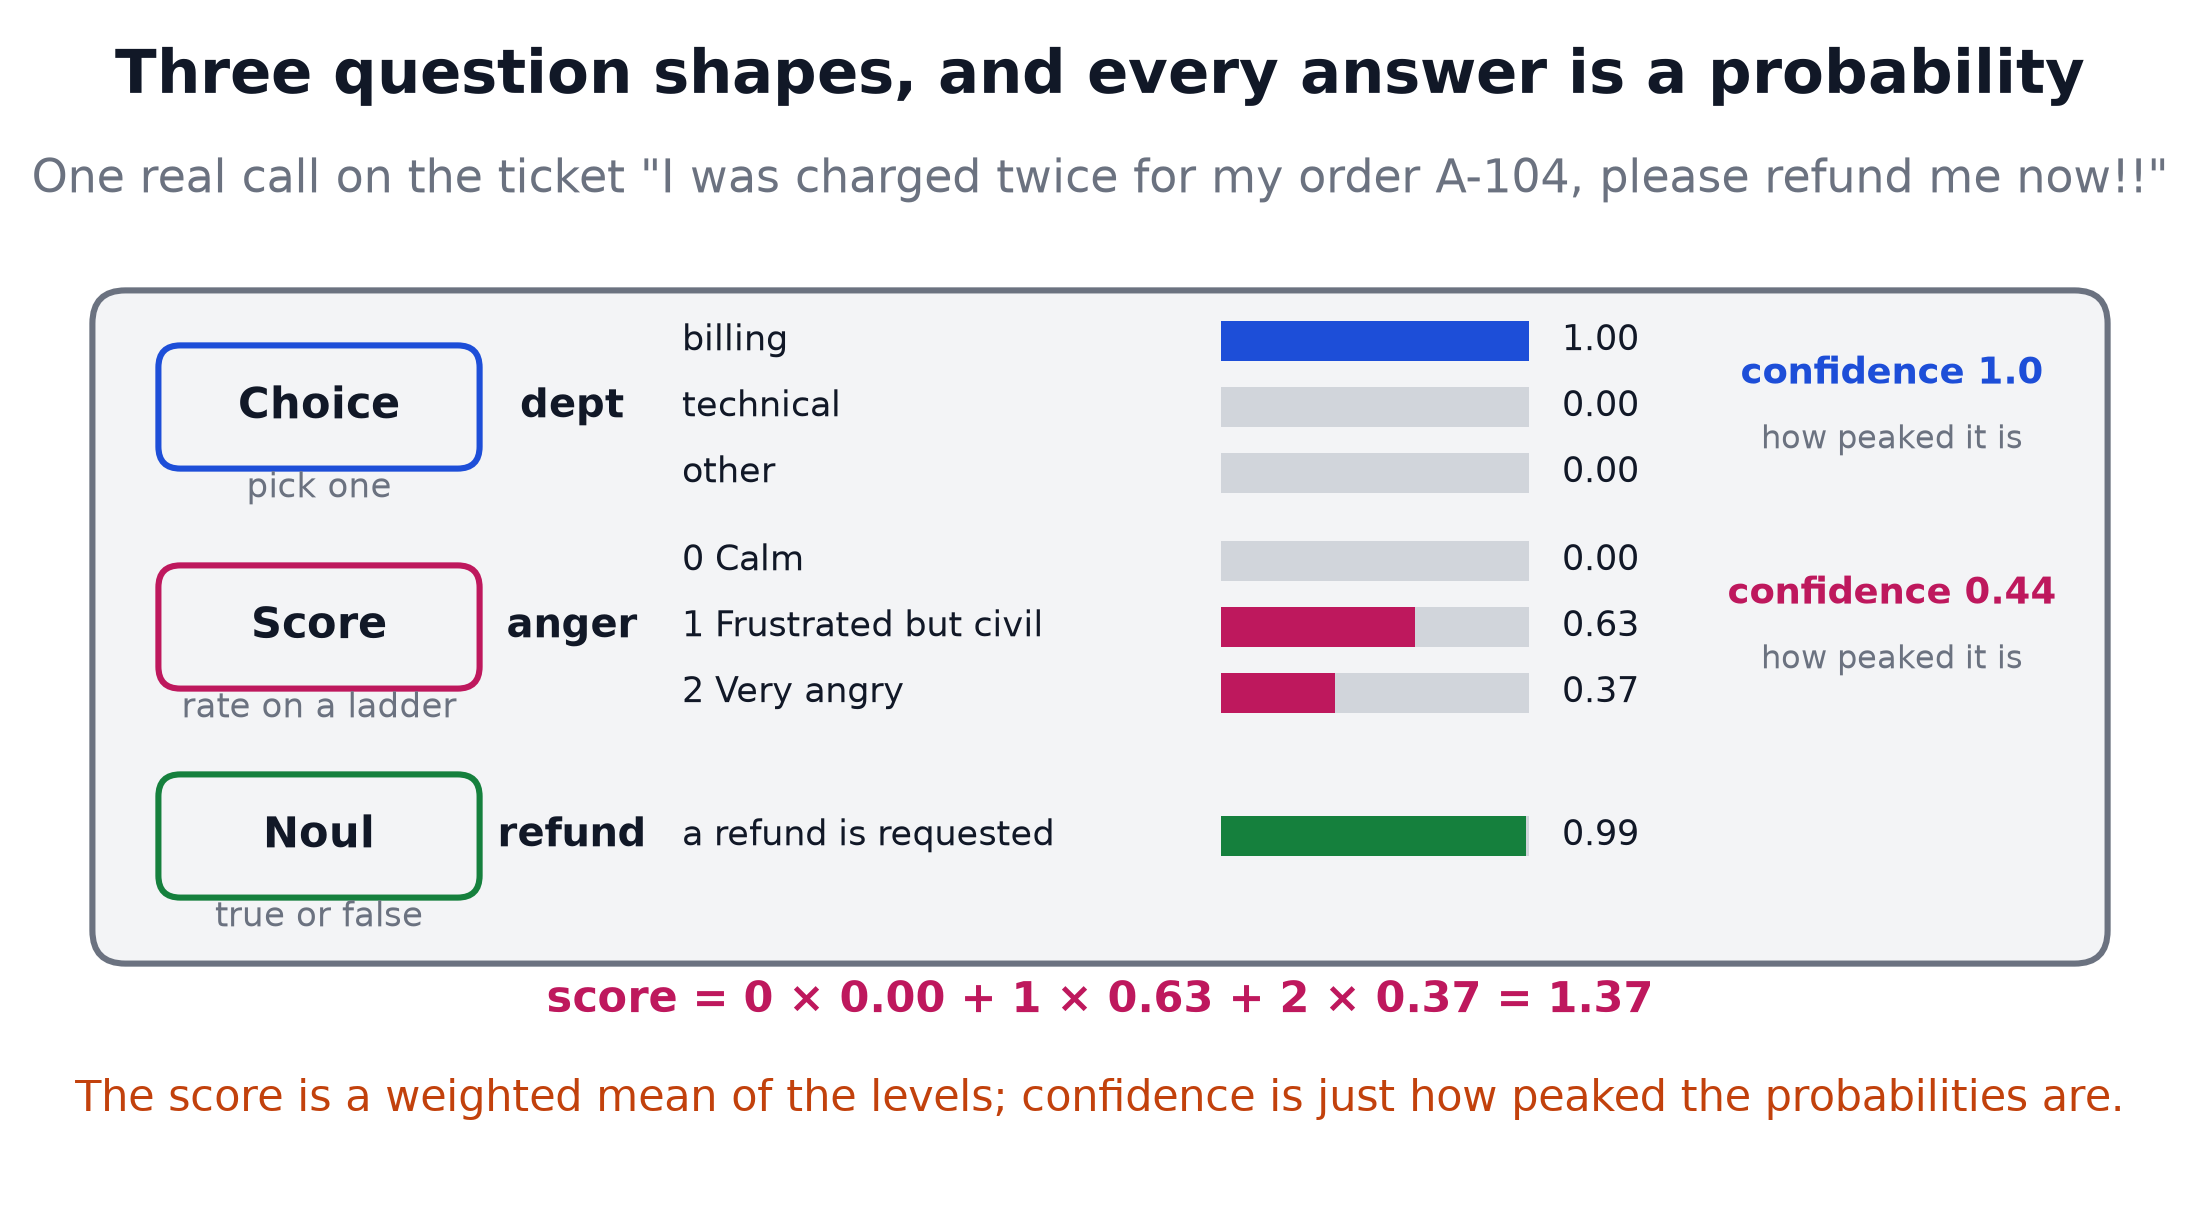
So far, I have focused on classification, but Jev supports three different question types: Choice picks one option, Score rates something on a scale you define, and Noul returns the probability that a statement is true.
I tested all three on the same support message:
“I was charged twice for my order A-104, please refund me now!!”
I asked Jev which department should handle it (dept), whether the customer was requesting a refund (refund), and how angry the message sounded (anger). Below is the raw response:
Choice and Noul are easy to read
For dept, Jev gave billing a probability of 1.0 and the other options 0.0. These values form a probability distribution: the probabilities across the available choices add up to one.
For refund, the result was 0.99. In other words, Jev assigned a 99% probability to the statement that the customer wanted a refund.
Score is a little different
For anger, I defined 3 levels: calm, frustrated but civil, and very angry. Jev assigned 0.63 to “Frustrated but civil” and 0.37 to “Very angry,” then combined them into a score:
0 × 0.0 + 1 × 0.63 + 2 × 0.37 = 1.37
That 1.37 is a weighted average. It places the message somewhere between frustrated and very angry, but I would not interpret it as a precise measurement of emotion. The scale is one I defined, and the distance between each label is not necessarily equal.
One detail initially caught me out: anger had a confidence of 0.44 even though its top option had a probability of 0.63. They are not the same thing. The option probability tells you how much weight Jev gives to a particular answer, while the confidence field reflects how strongly the overall distribution points toward one answer. A result concentrated entirely on billing has high confidence; a result split between two anger levels does not.
TypeSafe says multiple questions in the same request are evaluated independently against the same input, which makes this format useful when you want several decisions from one piece of text. In this example, the full request used 411 input tokens and cost roughly two-thousandths of a cent. The API output is easy enough to read. The harder question—and the one I cared about more—is whether these probabilities actually match how often Jev is right.
6. Can we trust the confidence score?
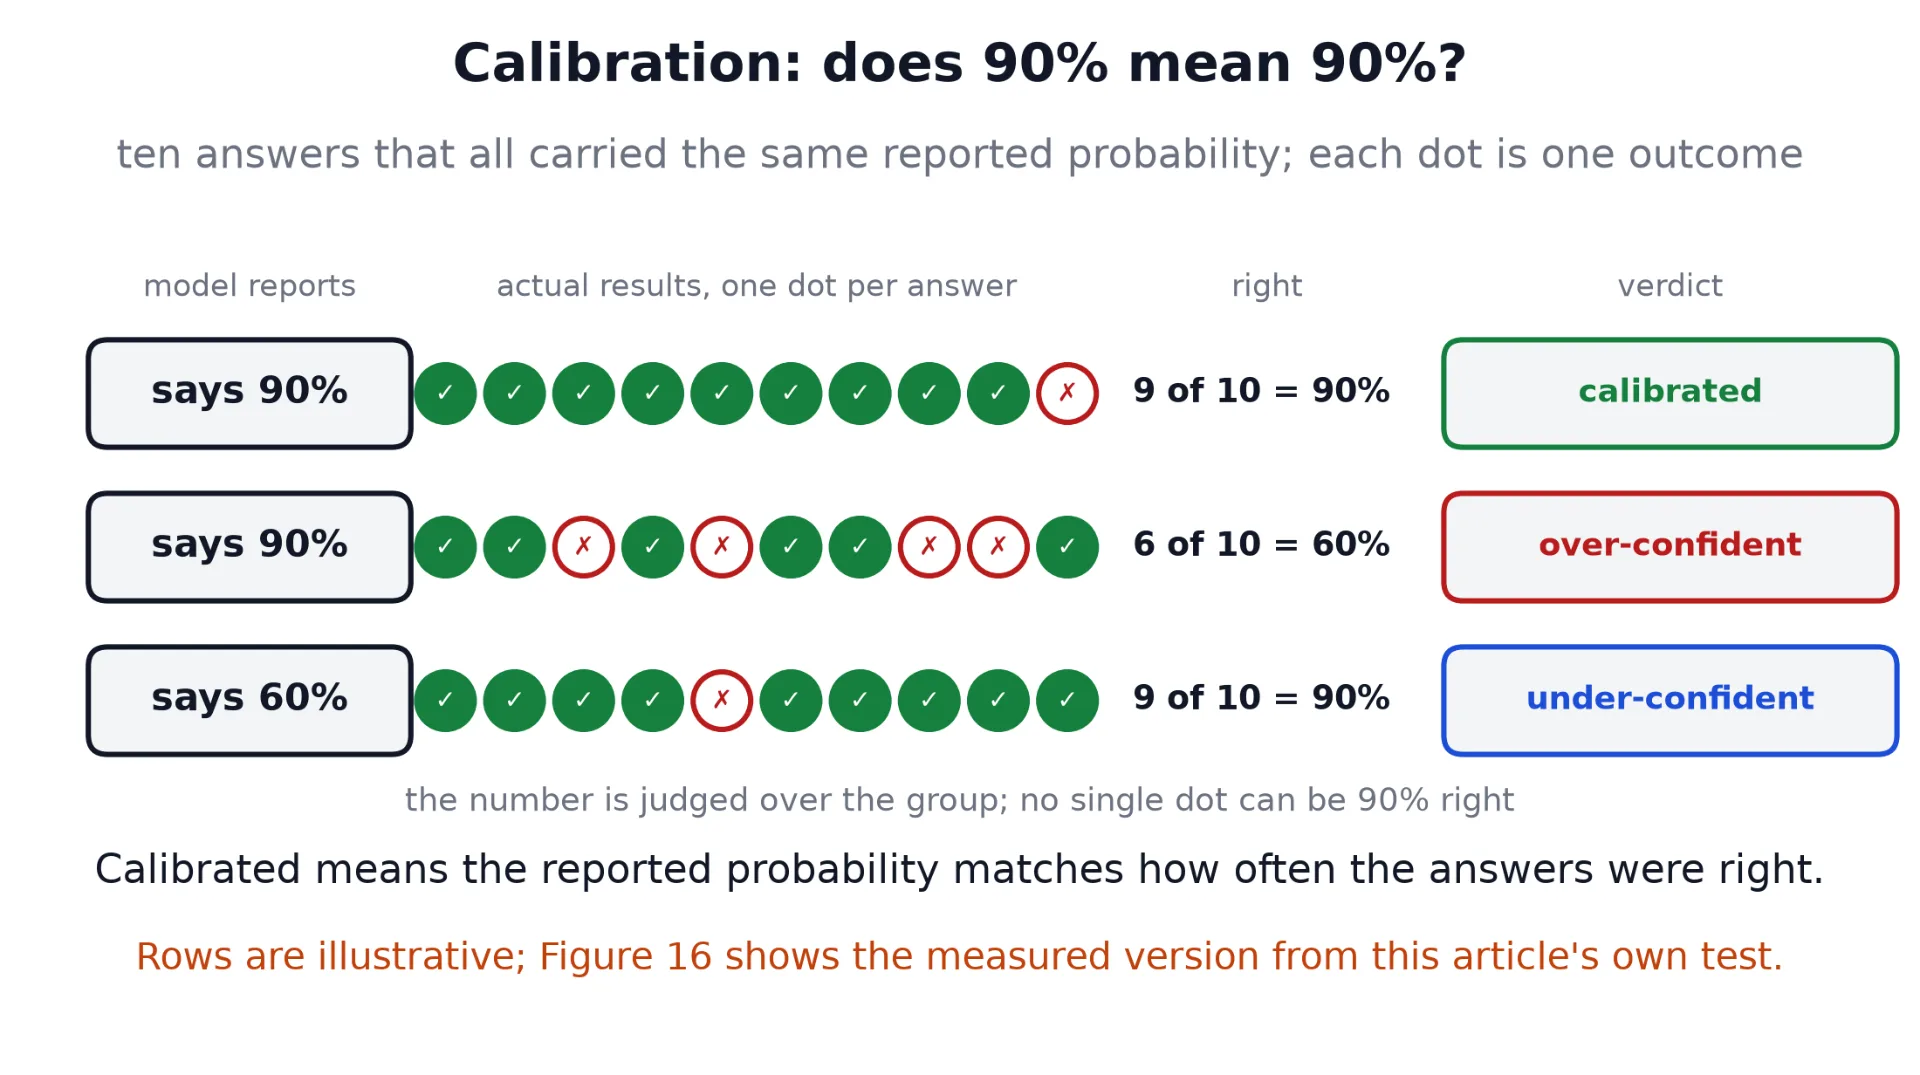
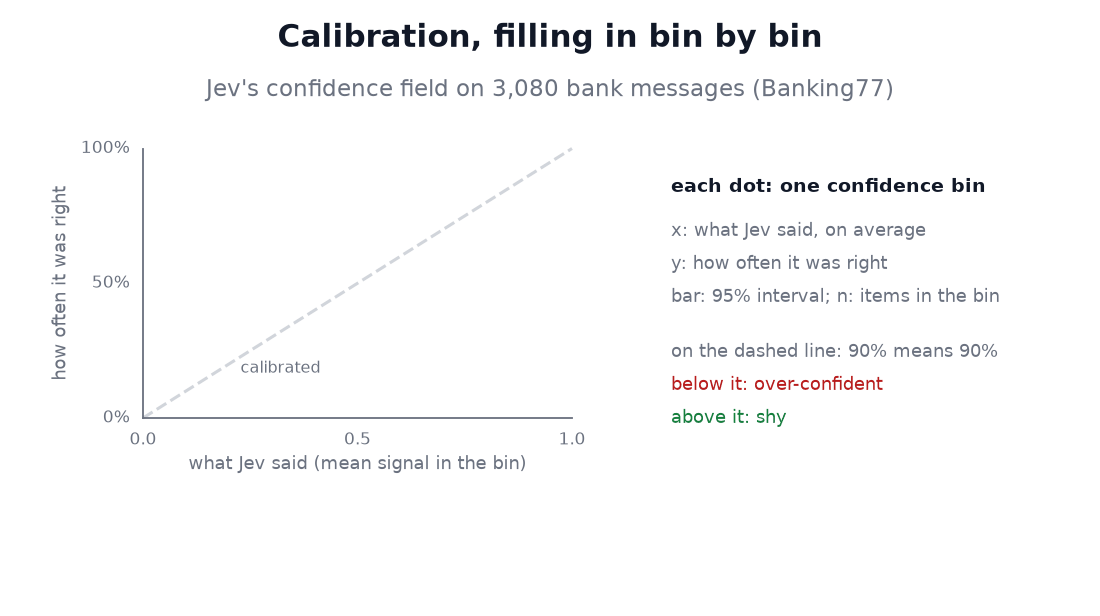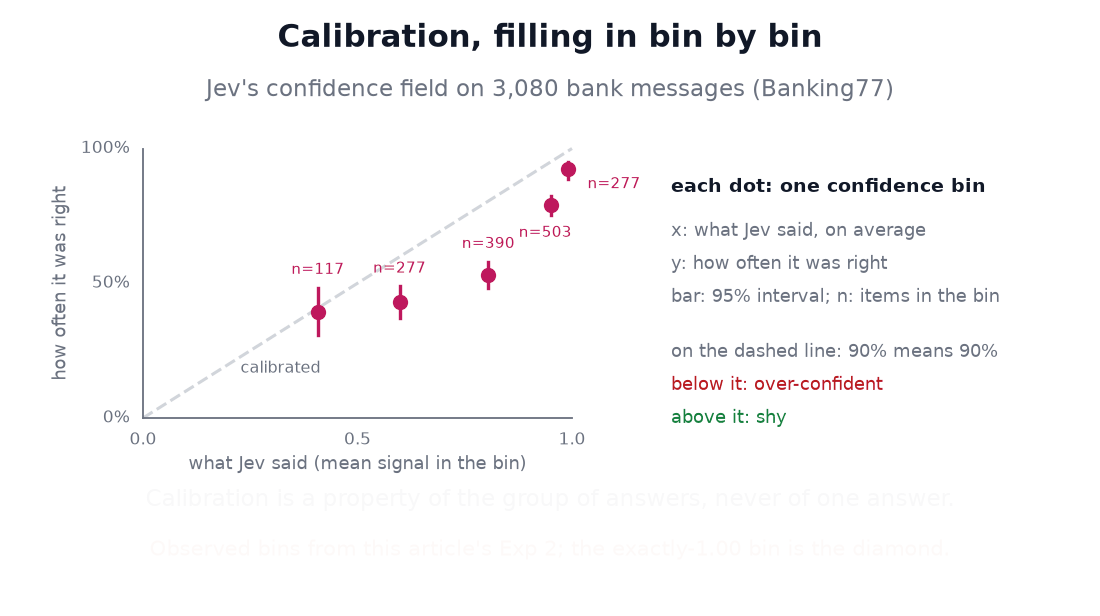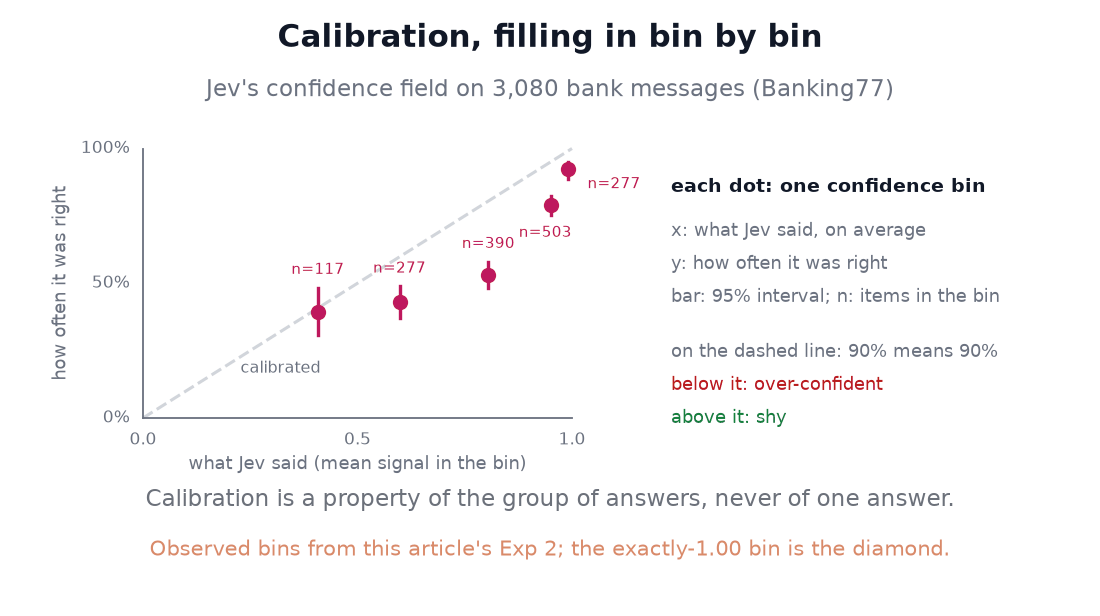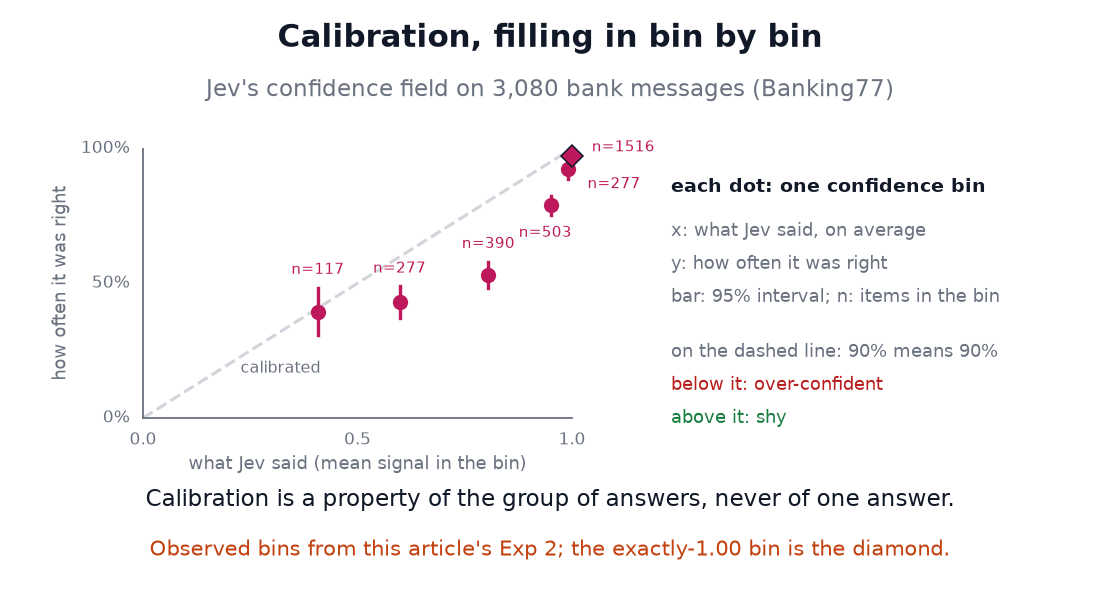
If a model says it is 90% confident, I want that number to actually be trustworthy. Think of a weather forecaster who says there’s a 90% chance of rain: if you tracked all the days they said that, it should have rained on about nine out of ten of them. In other words, a 90% chance of rain does not mean it must rain today. It means that, across many days given a 90% forecast, rain should occur about 90% of the time. The same idea applies to AI. If you gather every answer where the model claimed 90% confidence, roughly 90% of those answers should turn out to be right. A model that meets this standard is called “well-calibrated,” meaning its confidence matches how often it’s actually correct. A model that says “90% sure” but is right only half the time is overconfident, and its confidence numbers can’t be relied on. That relationship between confidence and actual accuracy is called calibration.
That is how I approached Jev’s confidence scores: not by asking whether a single 90% prediction was right, but whether predictions with similar confidence were actually correct at roughly that rate.
How calibration can be improved
There are two broad ways to improve calibration: adjust the probabilities after training, or train the model to produce better probabilities in the first place.
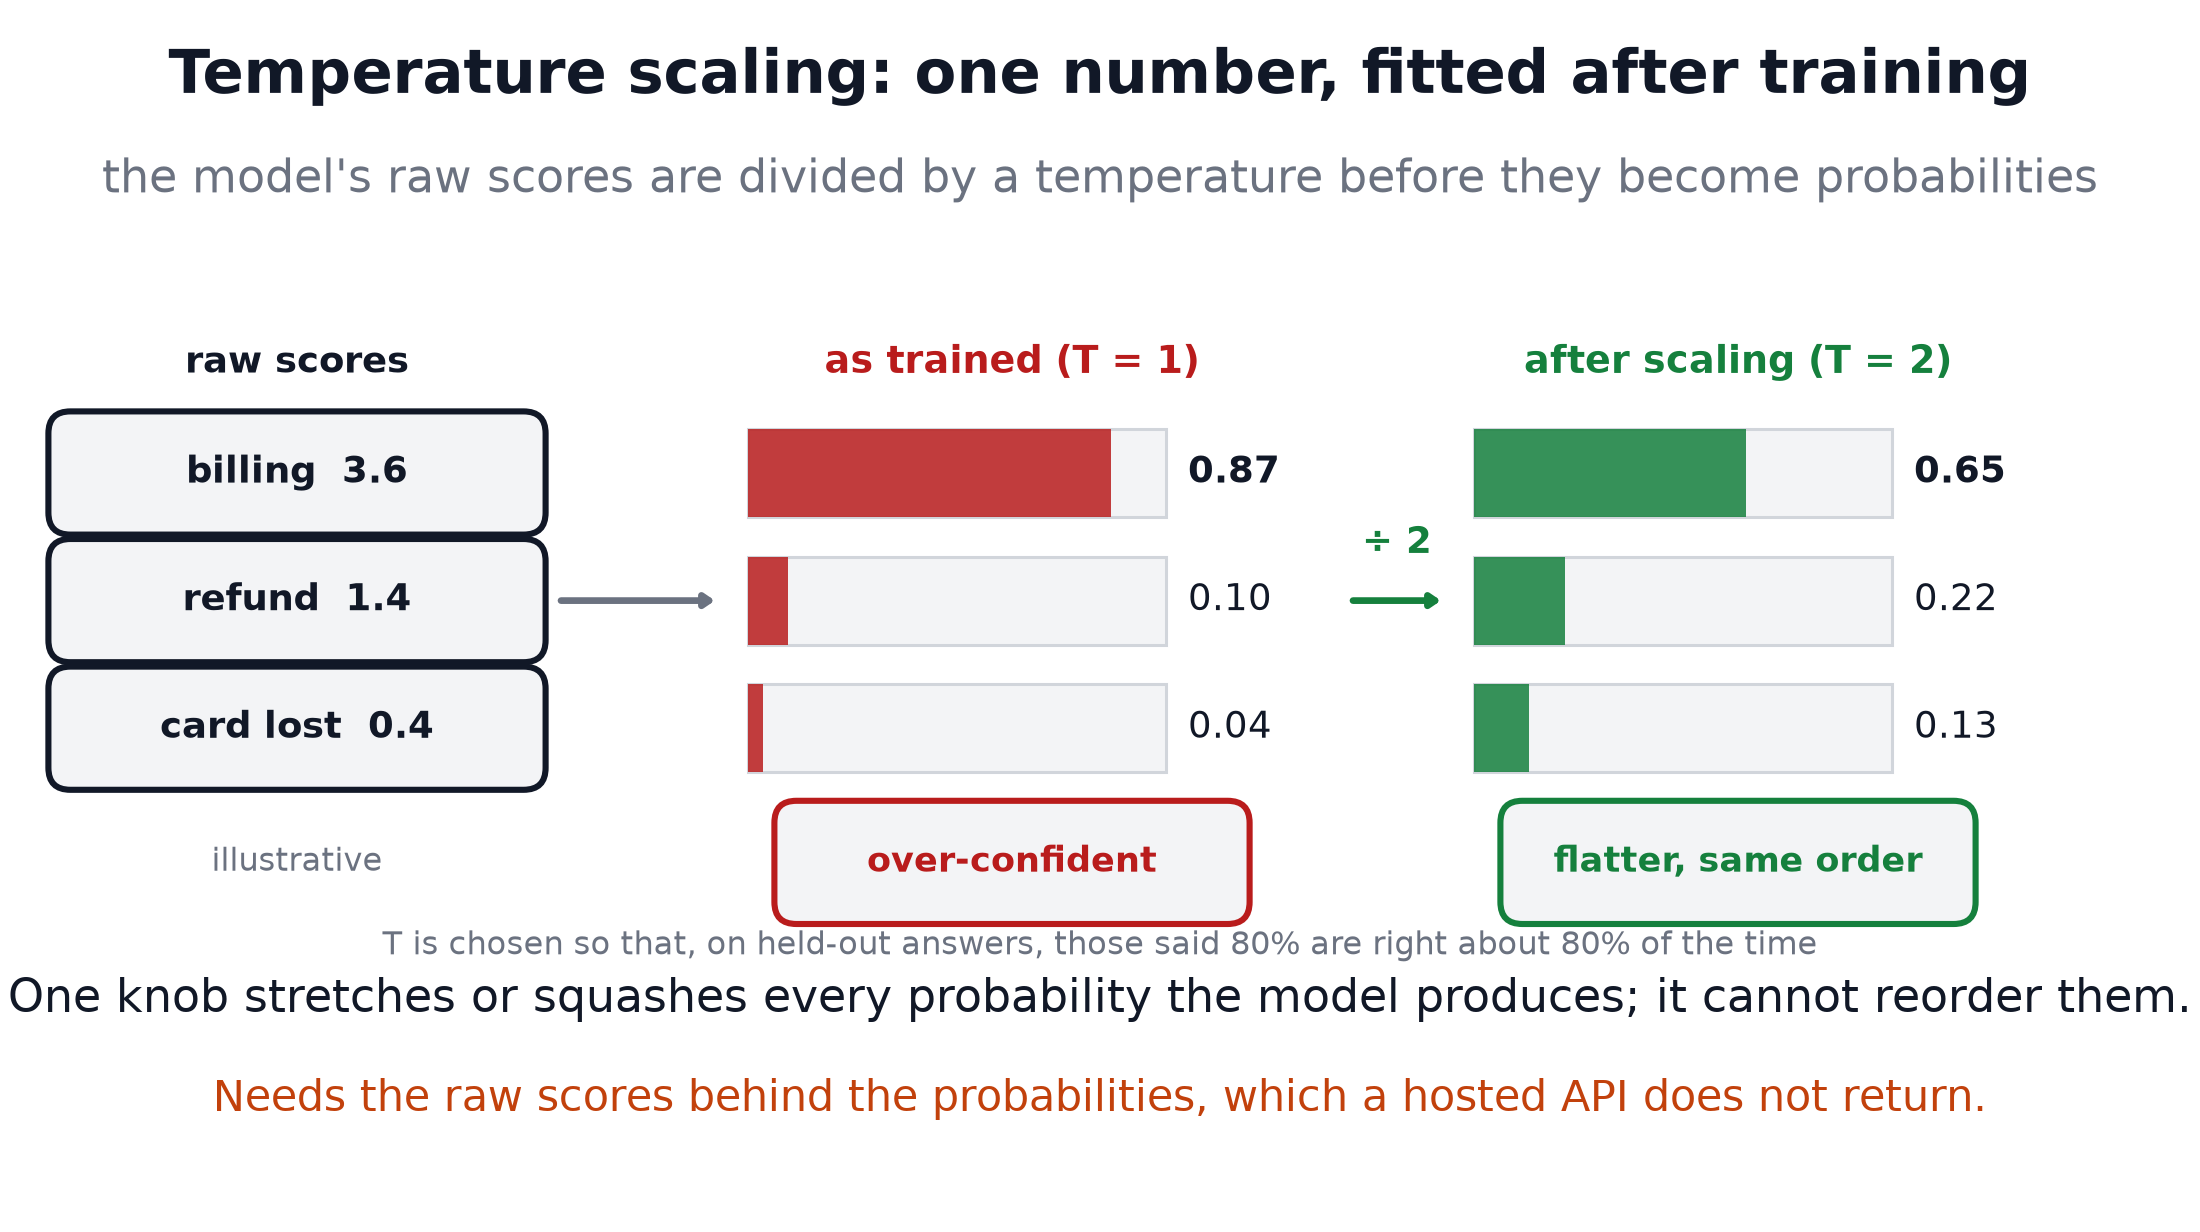
One common post-training method is temperature scaling. It applies a single adjustment to the model’s raw scores, usually making overconfident predictions less extreme without changing which answer ranks first. Guo and colleagues showed in 2017 that this simple method could perform as well as or better than more complicated calibration techniques.
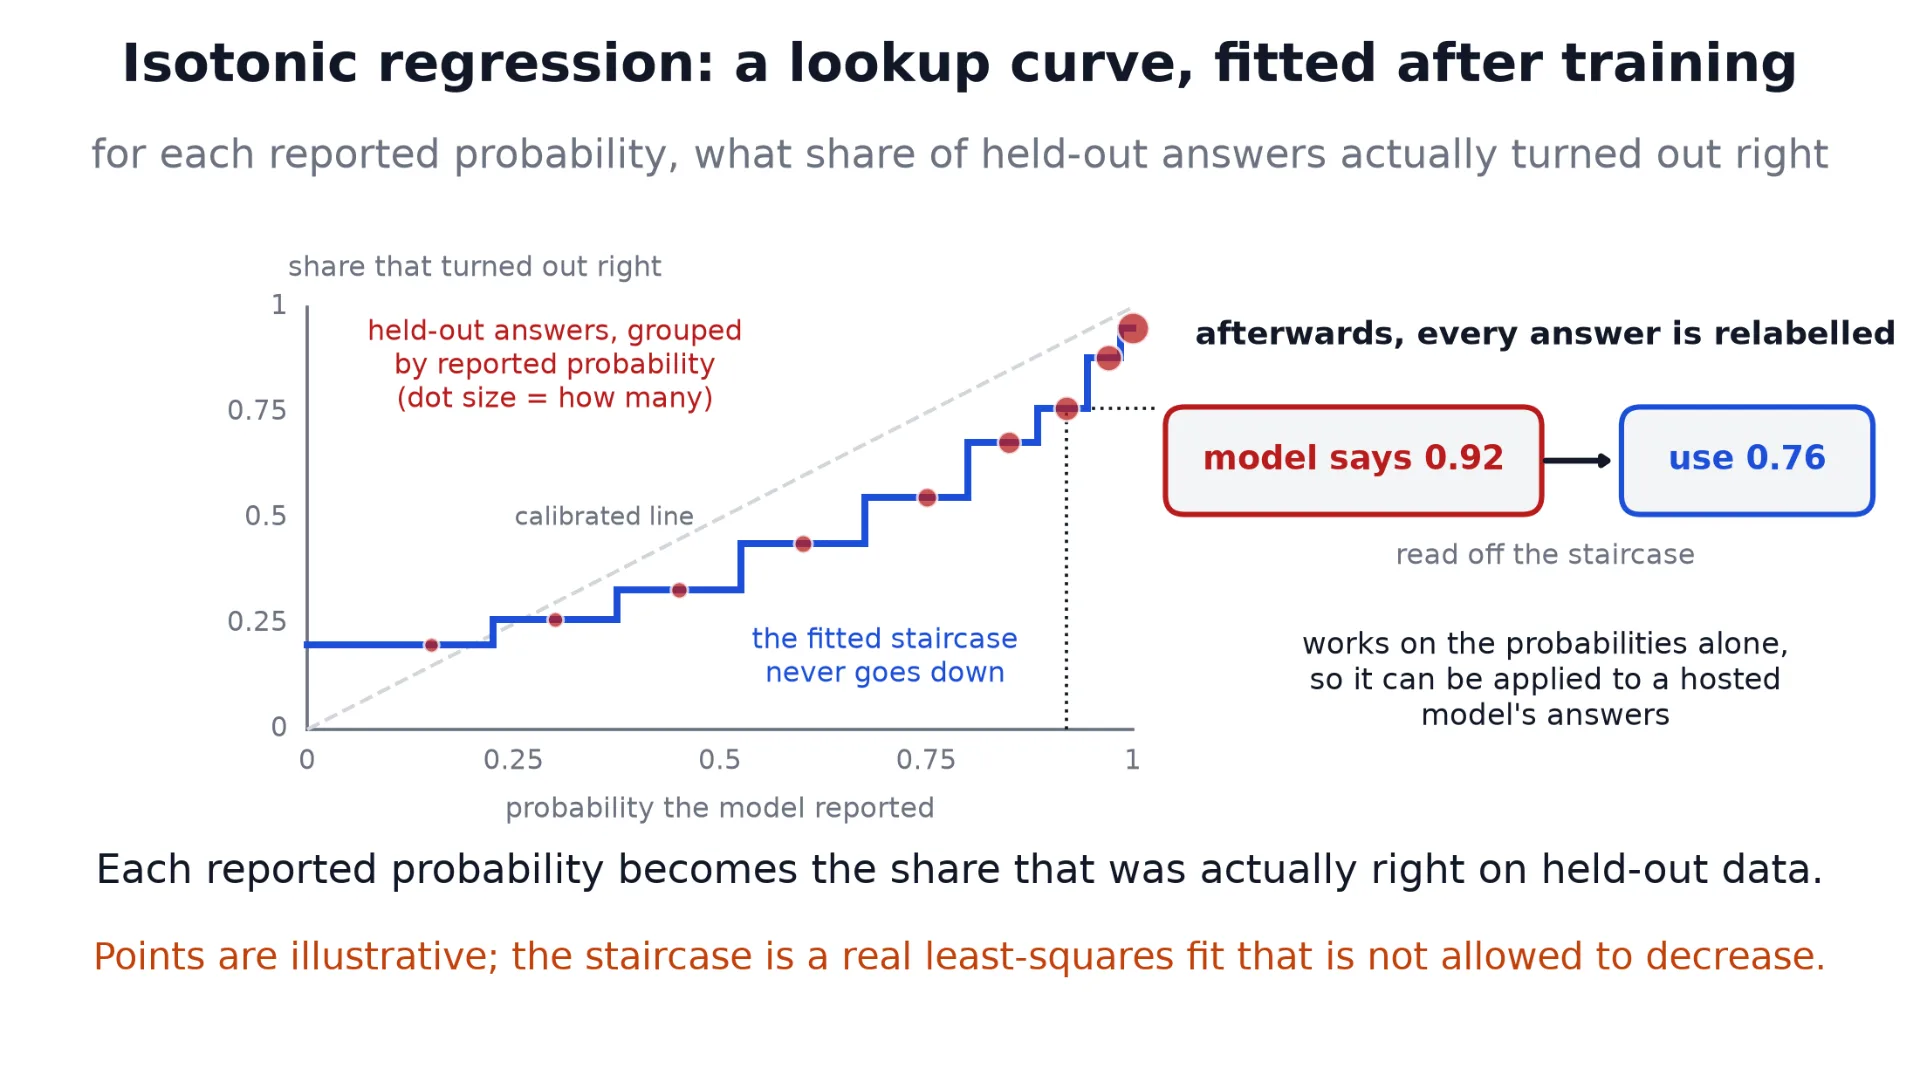
A more flexible approach is isotonic regression. Instead of applying one adjustment everywhere, it learns a correction curve from labelled examples. If predictions reported as 92% confident are only correct 76% of the time, for example, the calibrated score can be adjusted closer to 76%. For Jev users, there is an important practical difference. Temperature scaling normally requires access to the model’s raw internal scores, which a hosted API does not expose. Isotonic regression can work from the returned probabilities alone, so it is something an API user could apply independently with enough labelled data.
Calibration during training
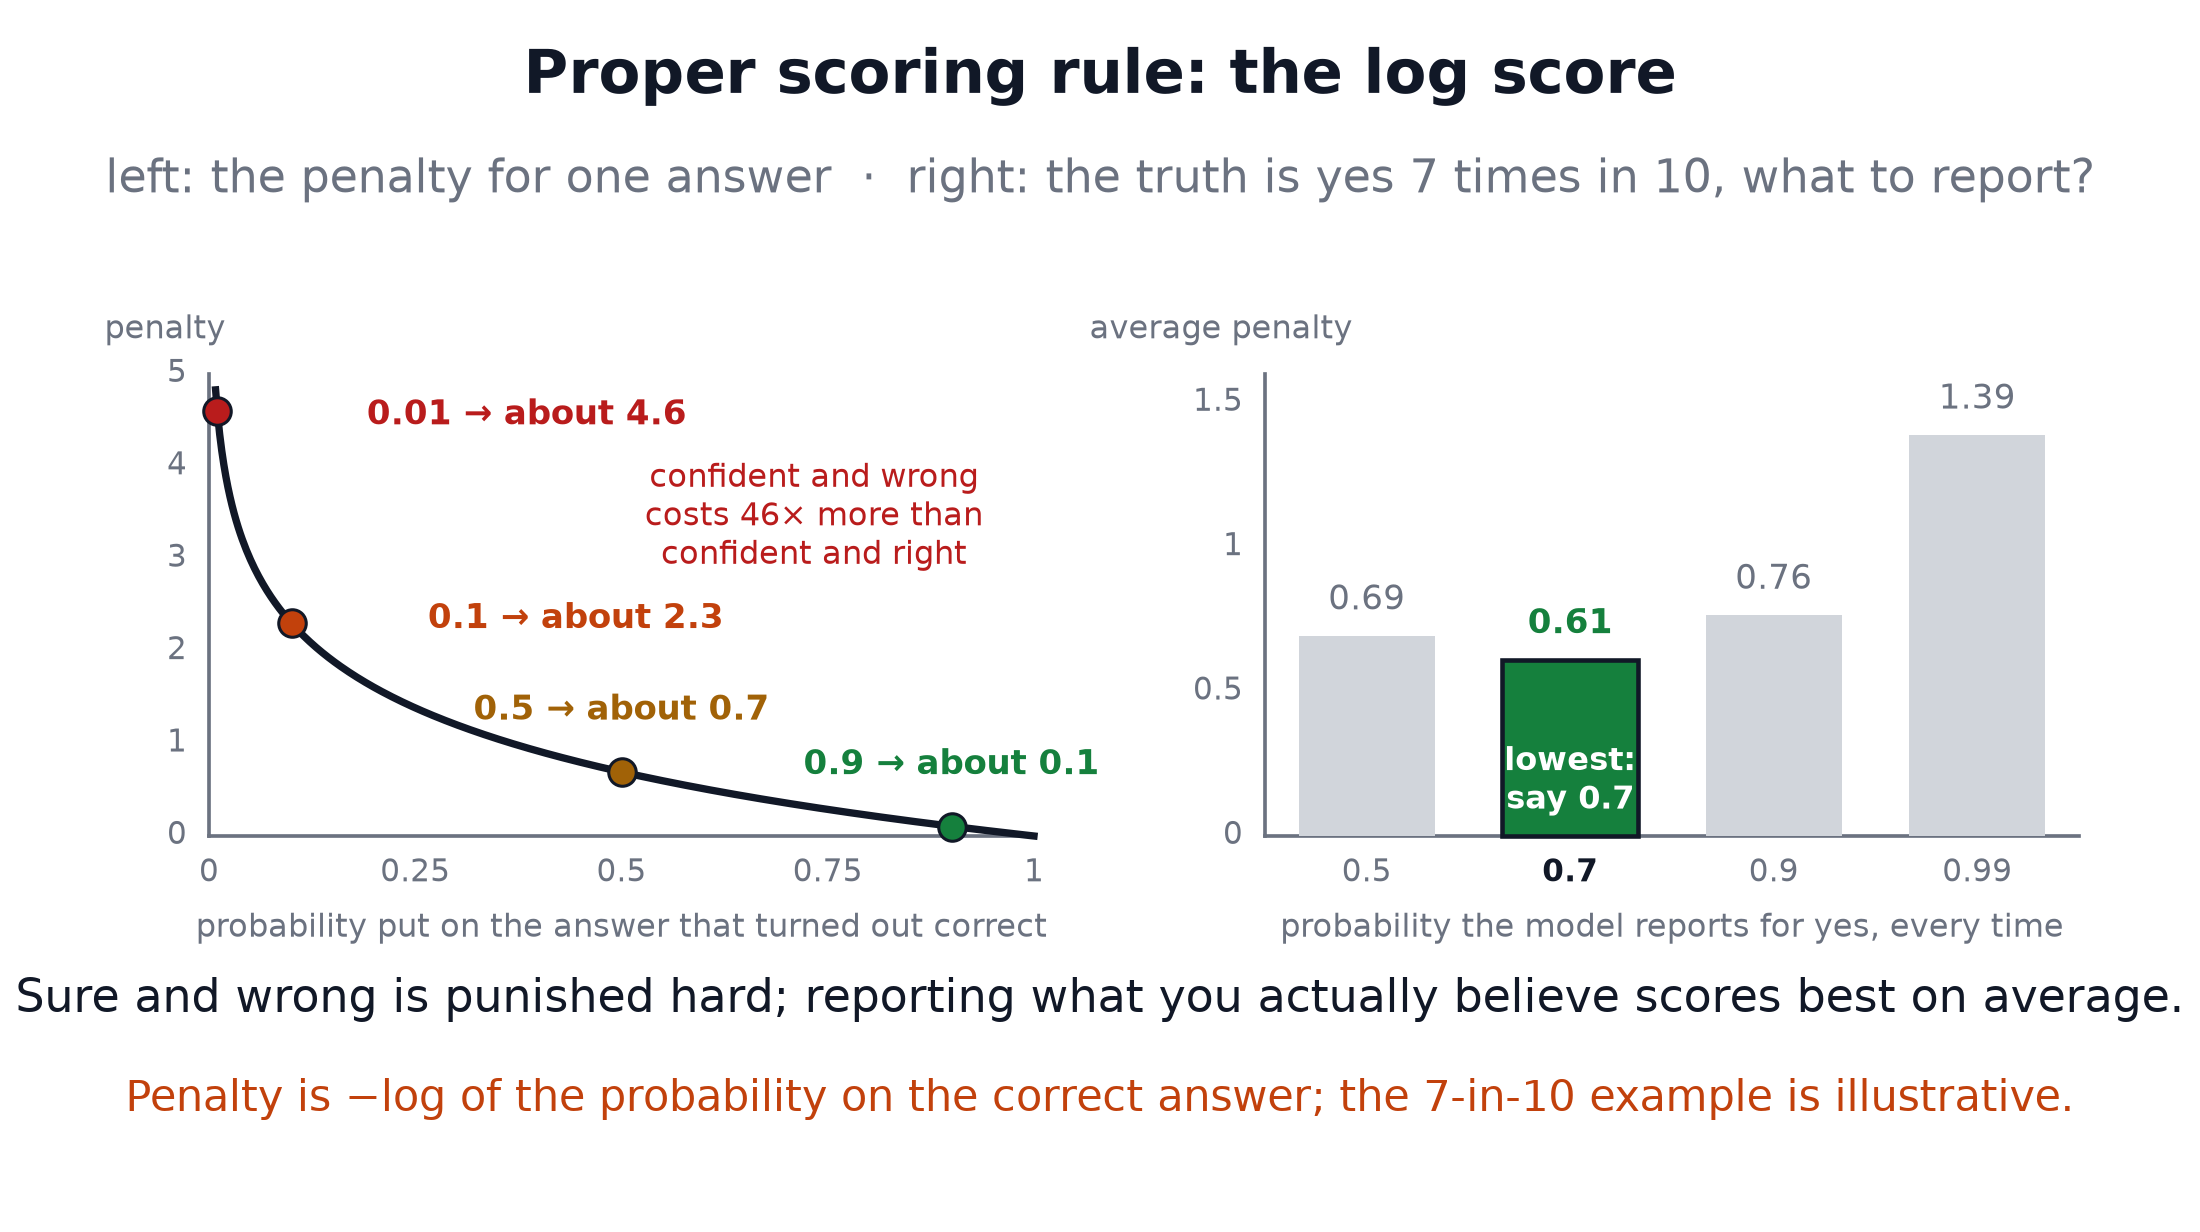
The other approach is to make probability estimates part of the training objective so that the good probability is estimated during training as well. To do this, proper scoring rules are used. They reward a model for assigning high probability to outcomes that turn out to be correct, while heavily penalising confident mistakes. Under a common logarithmic scoring rule, assigning 0.9 probability to the correct answer produces only a small penalty, while assigning 0.01 to it produces a much larger one.
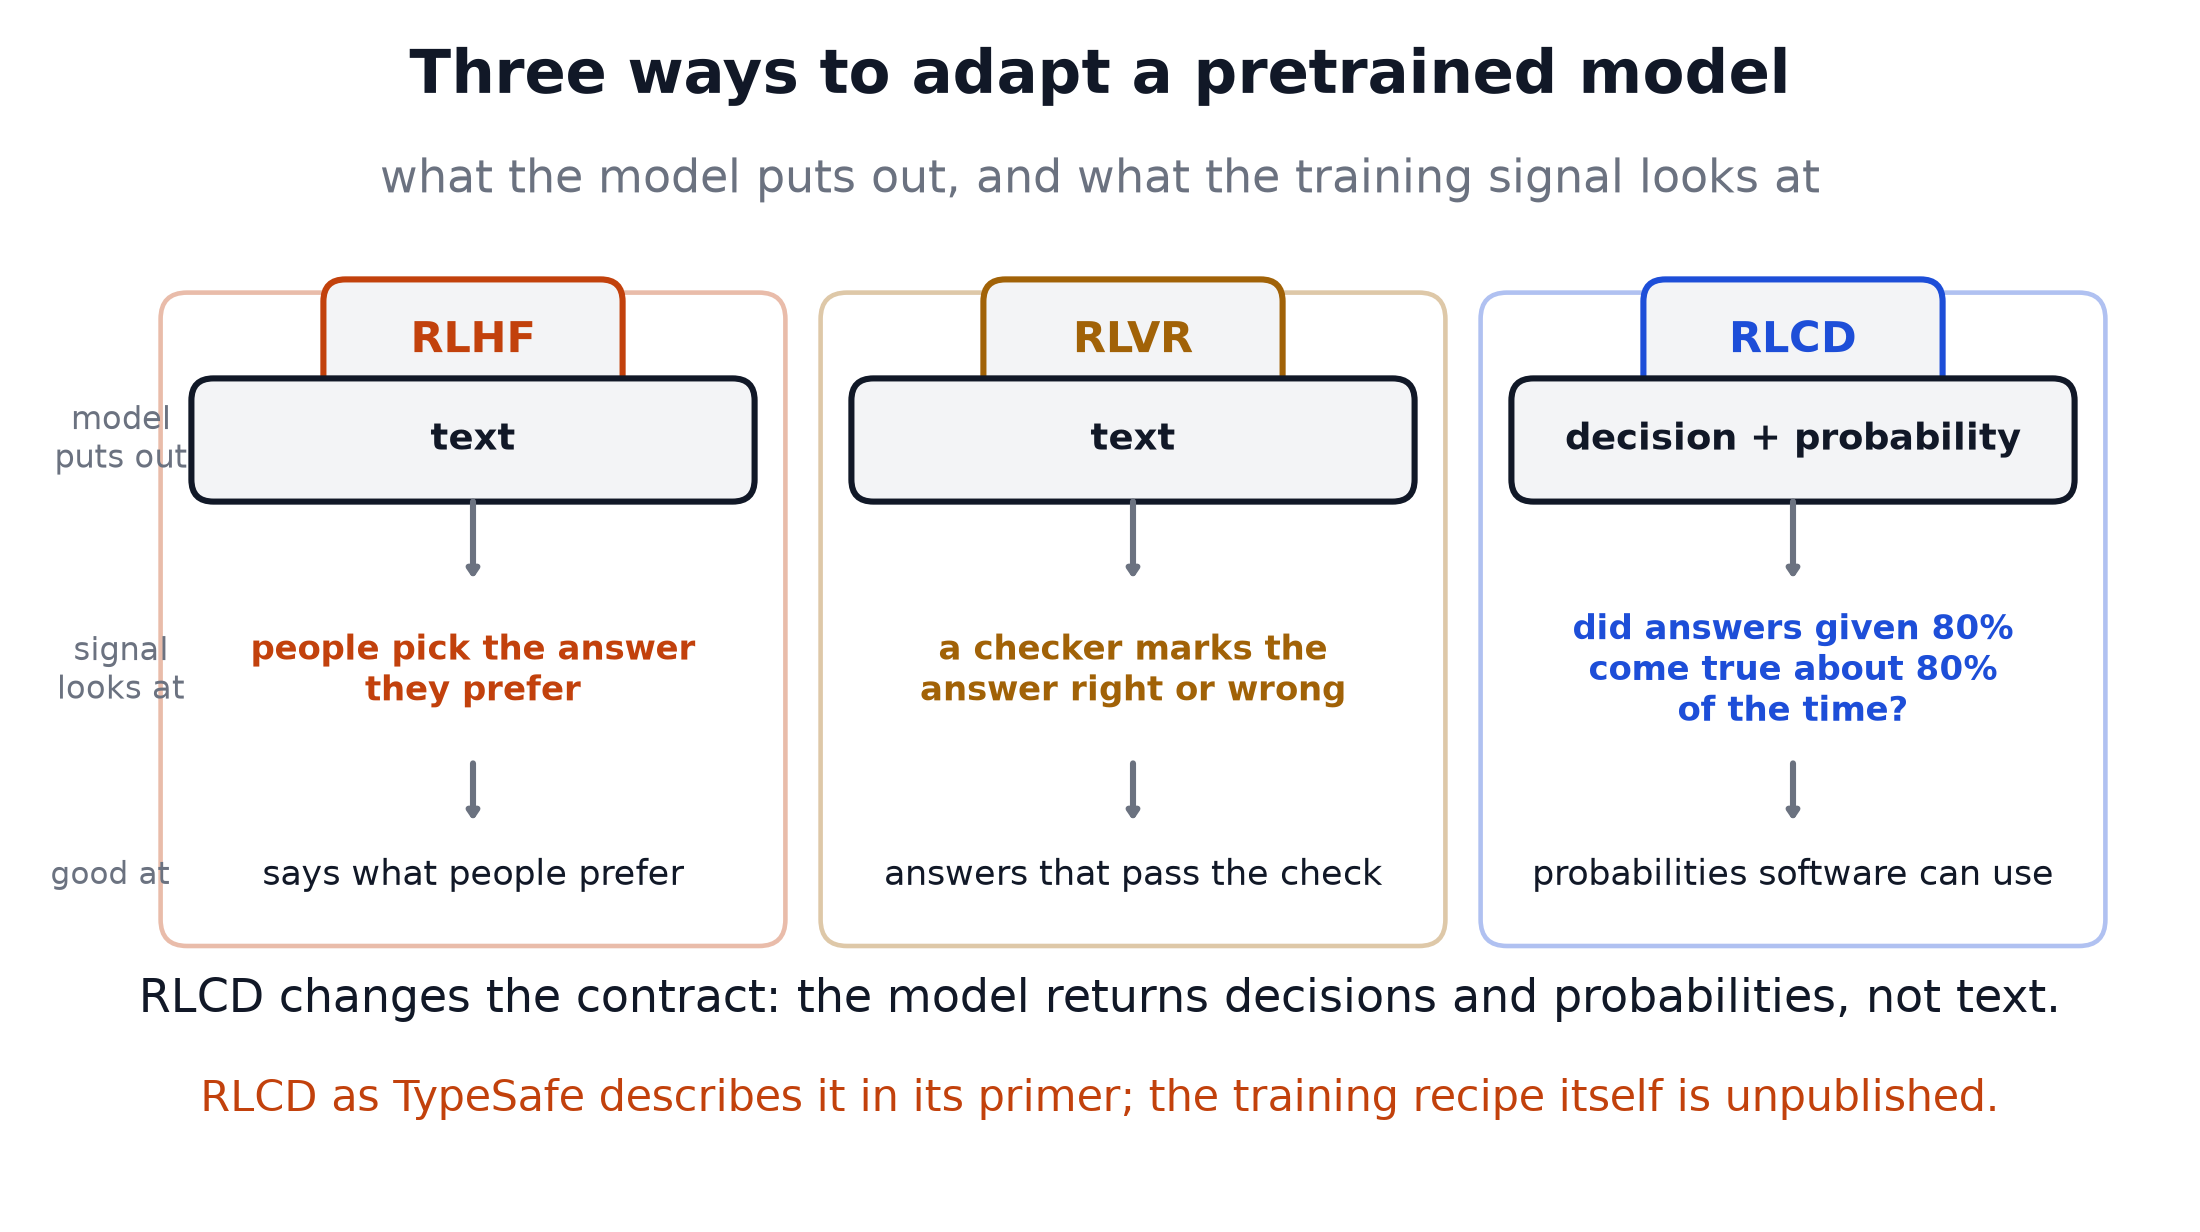
TypeSafe calls its approach RLCD, or “Reinforcement Learning for Calibrated Decisions,” and says the model is rewarded for probabilities that match real outcomes. That is a different goal from RLHF, which optimises for human preferences, or RLVR, which rewards answers that can be verified as correct. TypeSafe has not published the full details of how RLCD is implemented.
However, training for calibration does not guarantee that a model will stay calibrated on new data. A model can look reliable on one benchmark and become overconfident when the task changes. That is why I wanted to measure Jev’s confidence on my own bank-message dataset rather than assume the launch results would transfer.
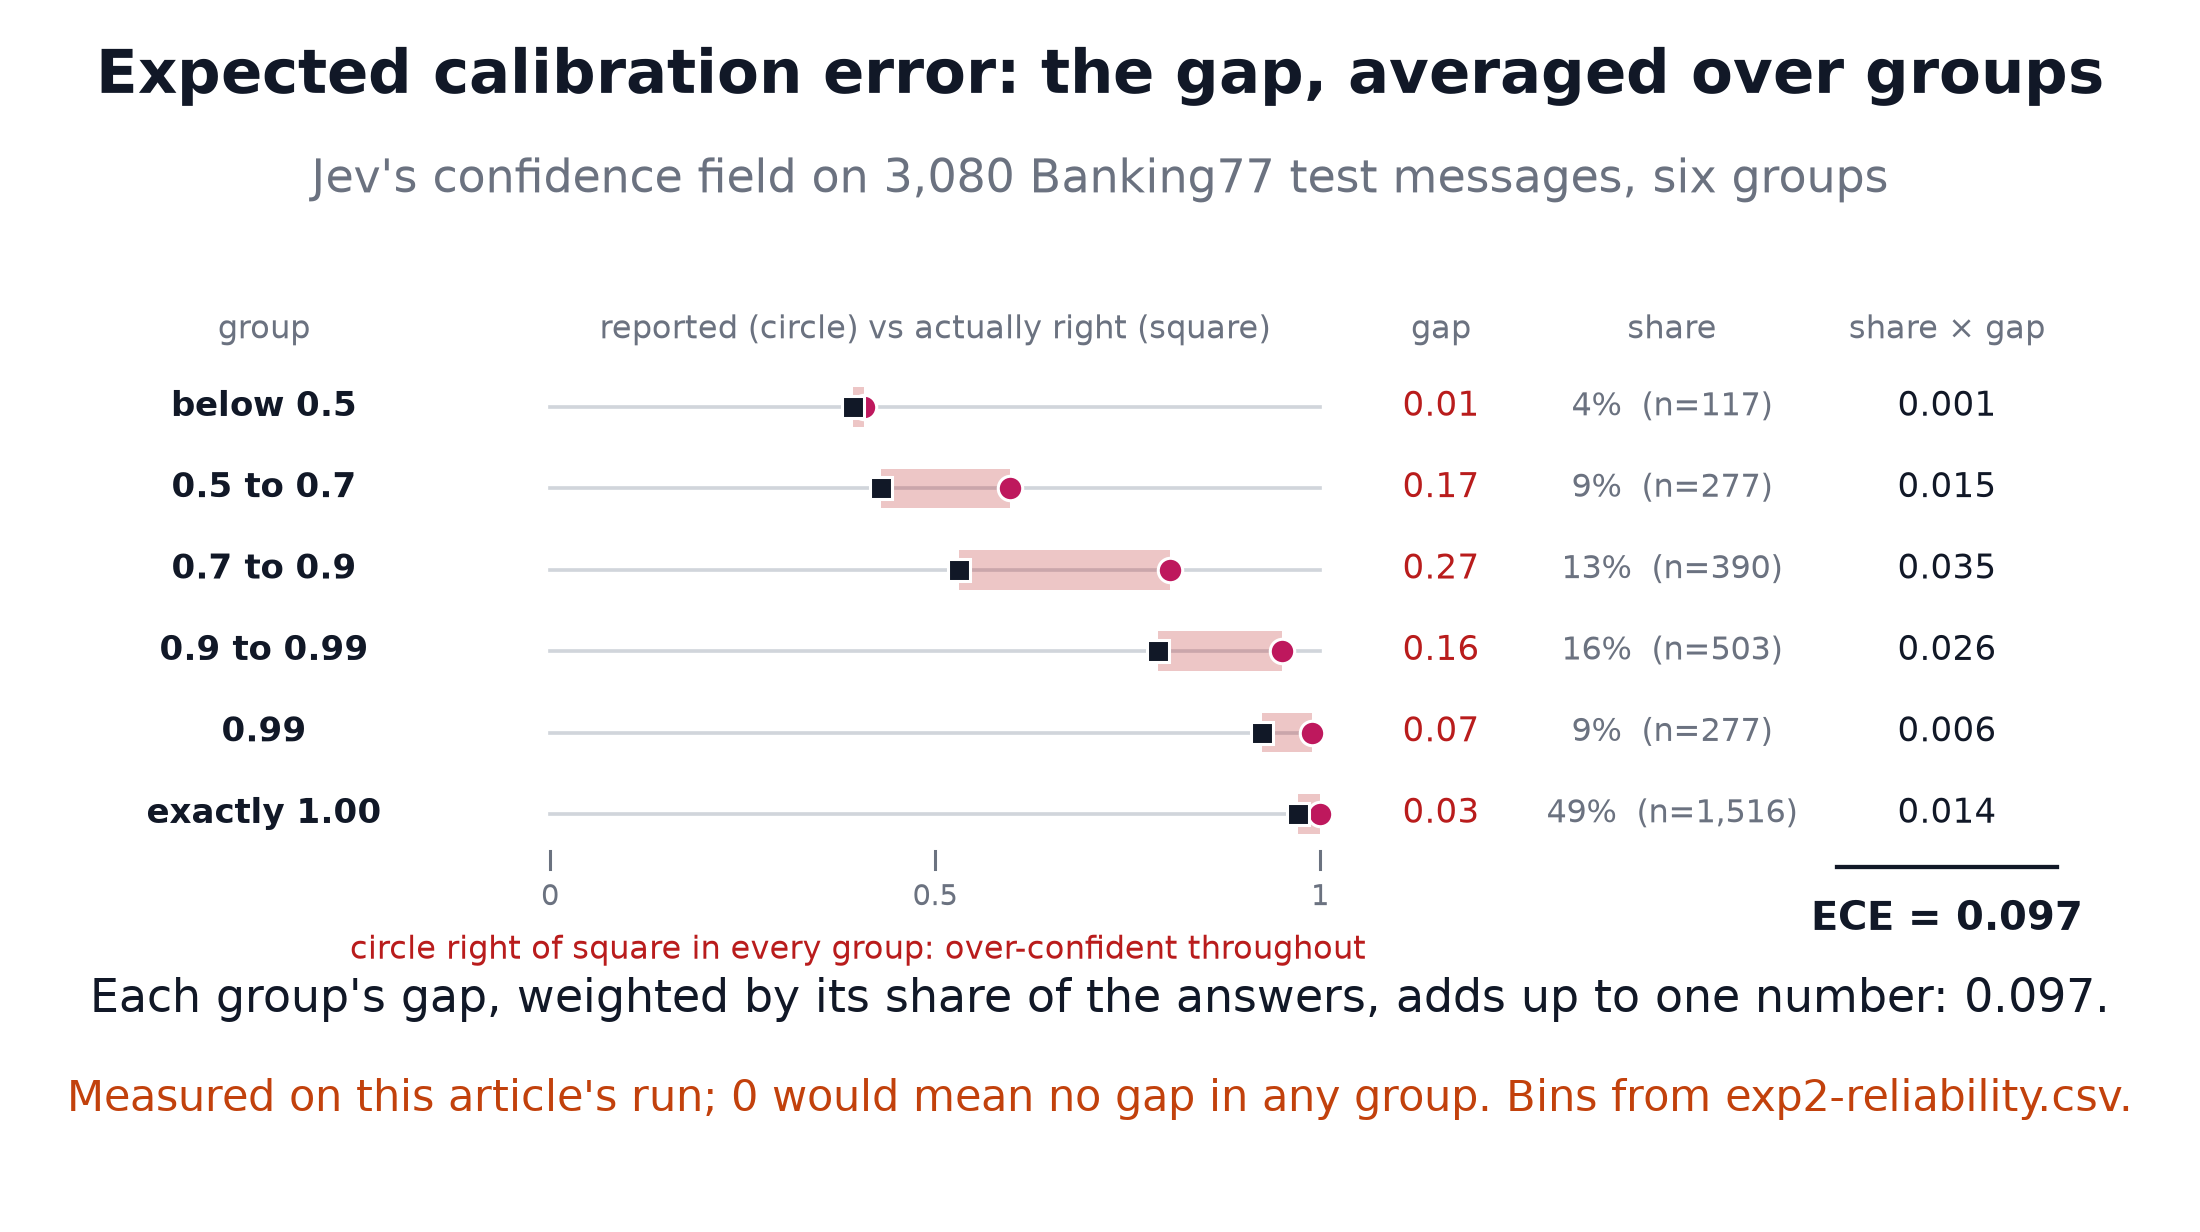
The existing results are mixed. One useful metric is expected calibration error, or ECE, which measures the gap between reported confidence and actual accuracy across groups of predictions. Lower is better.
In an evaluation published by scienthoon, Jev recorded ECE values of 0.082 on Choice, 0.079 on true-or-false questions, and 0.325 on Score. In other words, calibration looked reasonably close on the first two tasks but much weaker on Score.
Moreover, other small tests were more impressive at very high confidence. In themsquared’s evaluation, all 40 predictions with confidence exactly 1.000 were correct. PriorBench similarly reported 100% accuracy for predictions at 0.99 confidence or above, covering 60.2% of its test traffic.
However, my results were not quite that clean. I also looked at two signals separately: Jev’s reported confidence value and the probability assigned to its most likely option. That distinction matters because scienthoon found the maximum option probability tracked real accuracy better than the separate confidence field. Jev also rounds probabilities to two decimal places, so I paid particular attention to predictions reported as exactly 1.00.
Ultimately, calibration is useful because it tells us how much trust to place in groups of predictions. A well-calibrated 90% score still means some answers will be wrong. Confidence thresholds can help decide when to automate and when to send a case for review, but they cannot tell us in advance exactly which individual prediction will fail.
7. Using Jev efficiently
7.1 Using Jev and an LLM together
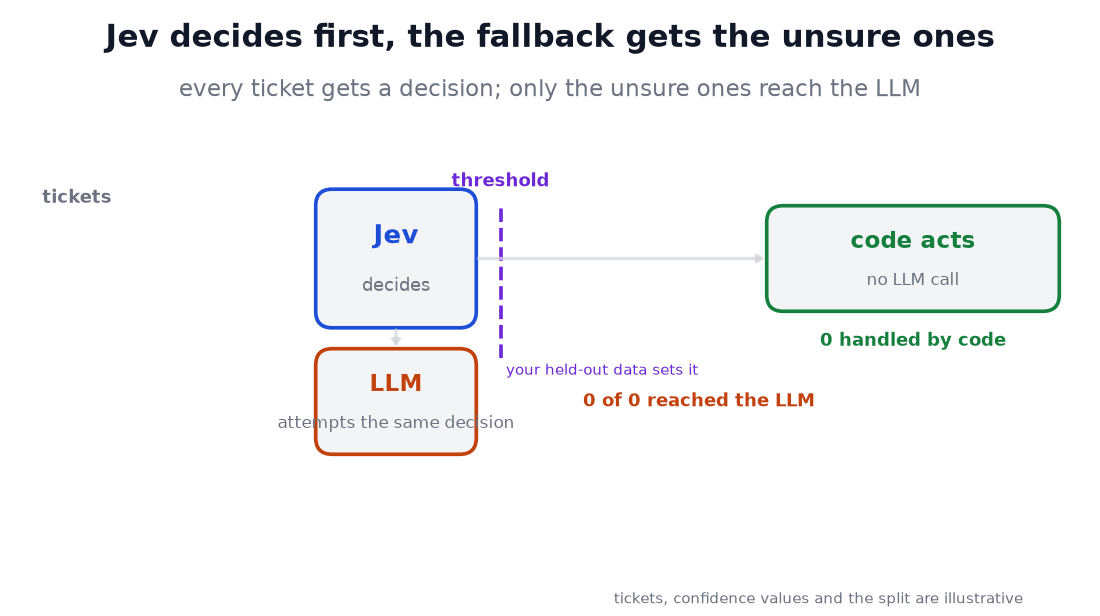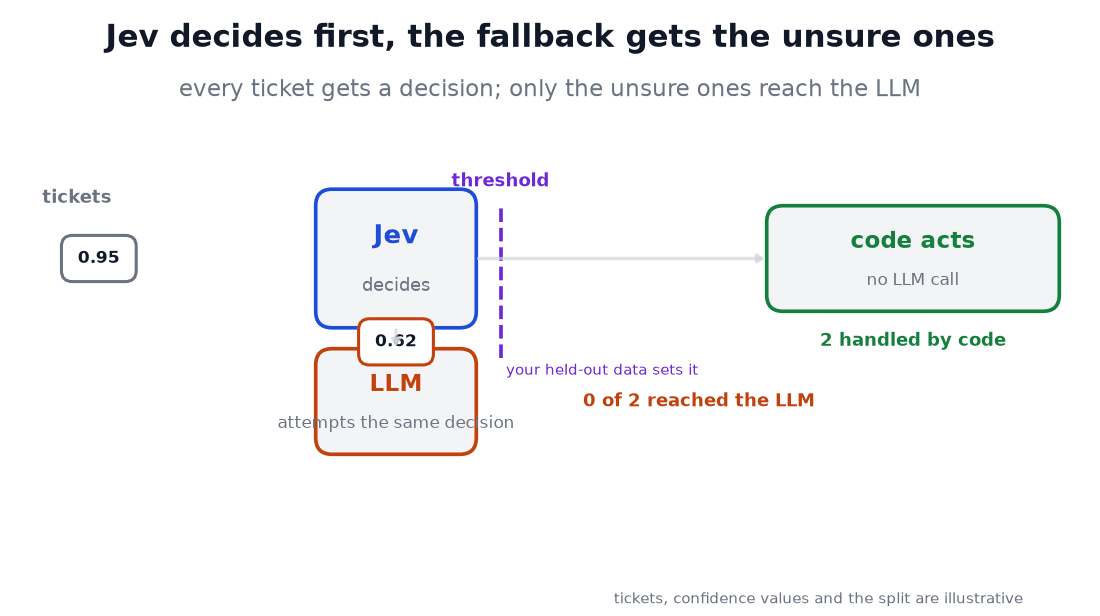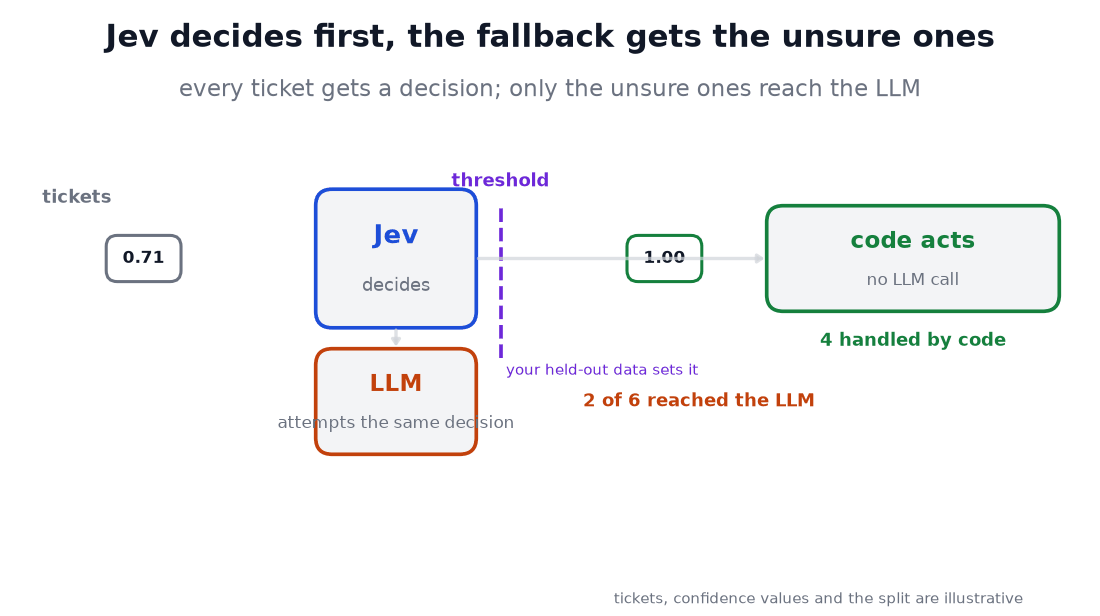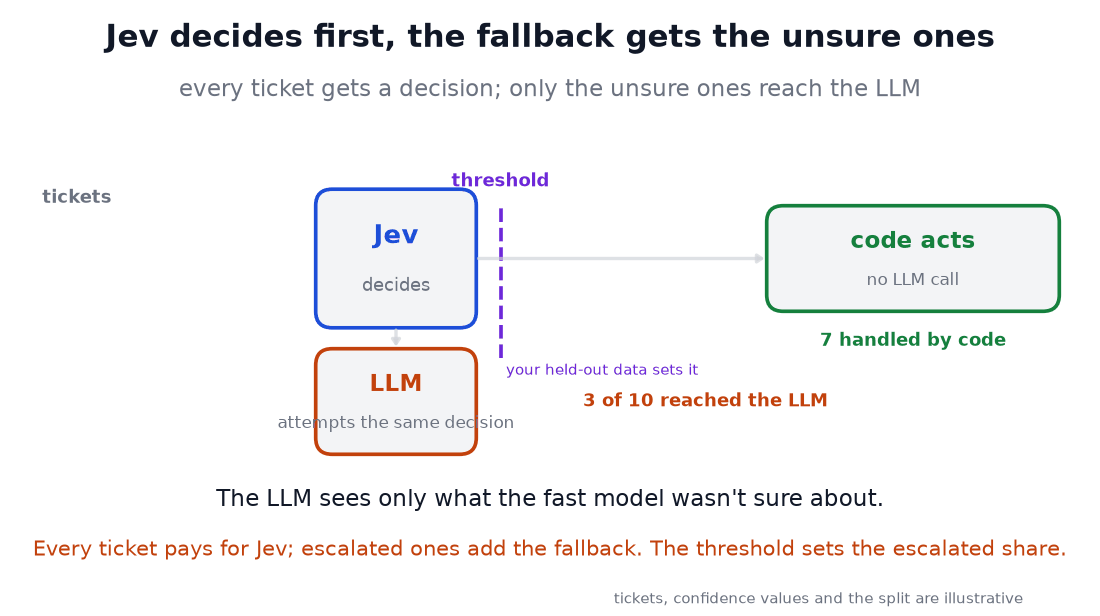
In some cases, what if Jev is not confident enough? How should we solve this? A simple approach is a cascade. Jev makes the first decision, and if its confidence is above a chosen threshold, the application accepts the result. If it falls below that threshold, the request is passed to an LLM or a person for another look. In practice, this lets Jev handle routine cases quickly while reserving more expensive models for the harder ones.
There are other ways to use the same pattern. TypeSafe’s cookbook shows that several related questions can be bundled into one Jev request: for a 54,000-character document, 13 separate calls took 2.71 seconds and cost $0.00609, while a single combined call took 0.27 seconds and cost $0.000497. LangChain has also shown Jev checking whether tool calls appear safe before execution, while DevelopersIO used it to route requests between LLMs and reported 40 correct routes out of 40.
The code below shows the cascade I had in mind using typesafe-sdk 0.7.0 and an OpenAI-compatible LLM client. The basic idea is simple: Jev handles the first pass, and uncertain cases are escalated.
There is a trade-off. Every request still goes through Jev, and every escalation adds the cost and latency of a second model. A higher threshold means more requests get escalated, so calibration matters if you want that threshold to mean something useful.
But there is an even more important limitation: low confidence from Jev does not mean the LLM will get the answer right. It only tells us Jev finds the case difficult. That distinction ended up being one of the most useful findings from my own test.
7.2 Where you need to be careful when using Jev
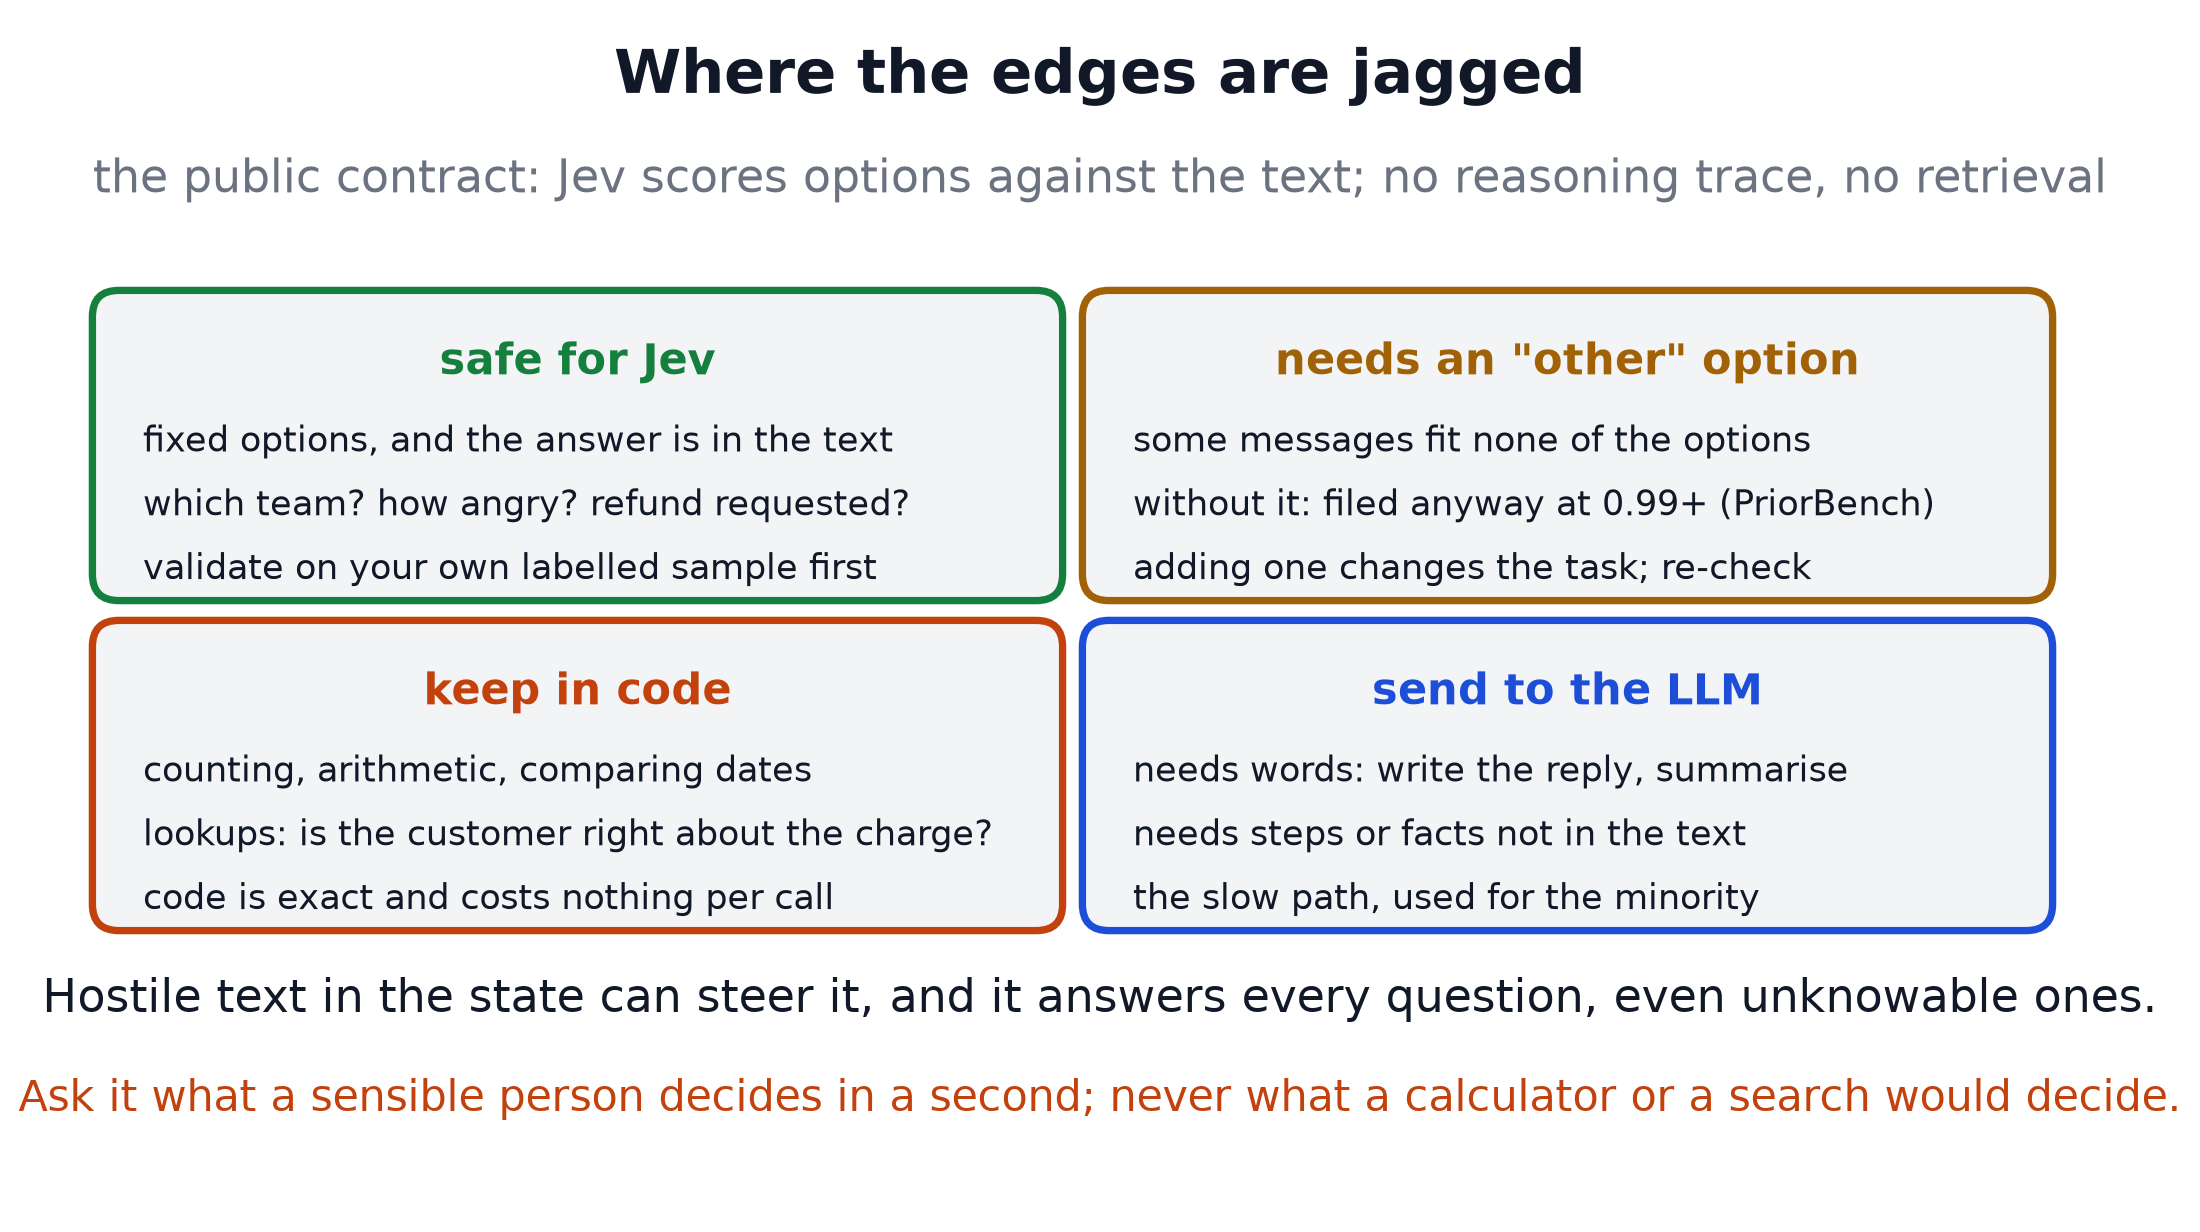
One thing I had to keep in mind during testing was the difference between a hard question and an unanswerable one. A message might clearly ask for a refund, for example, but say nothing about whether the customer is actually eligible. If the required account data or policy is missing, Jev cannot fill in the gap. TypeSafe also cautions that Jev tends to interpret inputs literally and can struggle with counting, arithmetic, and date comparisons. Irrelevant context can hurt performance, and instructions embedded inside user input can influence the result through prompt injection. Unlike an LLM, Jev does not produce an explanation you can inspect afterward.
That means the input has to be designed carefully: give it the information it actually needs, keep the question narrow, and leave exact calculations or record lookups to code.
7.3 Confidence is not the same as knowing
PriorBench found that Jev performed very well on some structured tasks, including 99.6% accuracy on number comparison and 100% on negation. But its behavior on inputs that did not fit any available category was much less reassuring: all 30 out-of-category examples still received confidence scores of at least 0.99. Moreover, a separate test by scienthoon showed a similar problem. When Jev was asked to apply a “priority” rule that could not actually be determined from the text, accuracy fell to 44.7% while average confidence remained 0.74.
So high confidence does not necessarily mean the model has enough information to answer.
TypeSafe’s own launch benchmark points to the same need for caution. Across 711 workflow cases, Jev reported 67.8% average agreement with GPT-6 Astra and Fable 5.1, compared with 74.1% for the strongest comparator. That benchmark measures agreement with other models rather than correctness against independently verified answers, so I see it more as a signal of consistency than a final measure of quality. For me, the practical takeaway is simple: design each question around what the input can actually support. Add an “other” option when real inputs may fall outside your categories, and test that case explicitly. And when a decision depends on missing records or potentially hostile input, raising the confidence threshold is not enough.
8. What I found in my own tests
8.1 Test setup
I did the test on my own so that I can confidently understand how Jev performs instead of relying on other benchmarks. Below is the test setup:
-
Dataset: Banking77, a dataset of 3,080 bank-support messages across 77 intents such as “card arrival,” “wrong exchange rate,” and “top-up failed.” (CC BY 4.0 license)
-
Models: Jev is tested against Qwen3-Coder-Next-80B-A3B (run with vLLM with 4-bit weights, temperature set to 0, and thinking disabled).
-
Both models received the same list of categories and short descriptions.
-
Jev answered through a Choice question, while Qwen was prompted to return exactly one category name.
After a 100-example pilot to settle the prompts, I ran each model once across the full test set. I alternated between them in blocks of 250 and did not include an “other” category because every message in Banking77 has a valid label.
8.2 Jev was more accurate
Jev beat Qwen by 4.7 percentage points on classification accuracy. When I resampled the test set to estimate uncertainty, the 95% interval for that gap was +3.7 to +5.7 points, so the difference was fairly consistent across the dataset.
|
Model |
Accuracy (95% interval) |
Median time per call |
Input tokens per call |
|---|---|---|---|
|
Jev |
81.1% (79.6–82.4) |
245 ms |
2,288 |
|
Qwen3-Coder-Next-80B-A3B |
76.4% (74.8–77.8) |
249 ms |
1,350 |
|
Jev minus Qwen, comparing the same messages |
+4.7 percentage points (+3.7 to +5.7) |
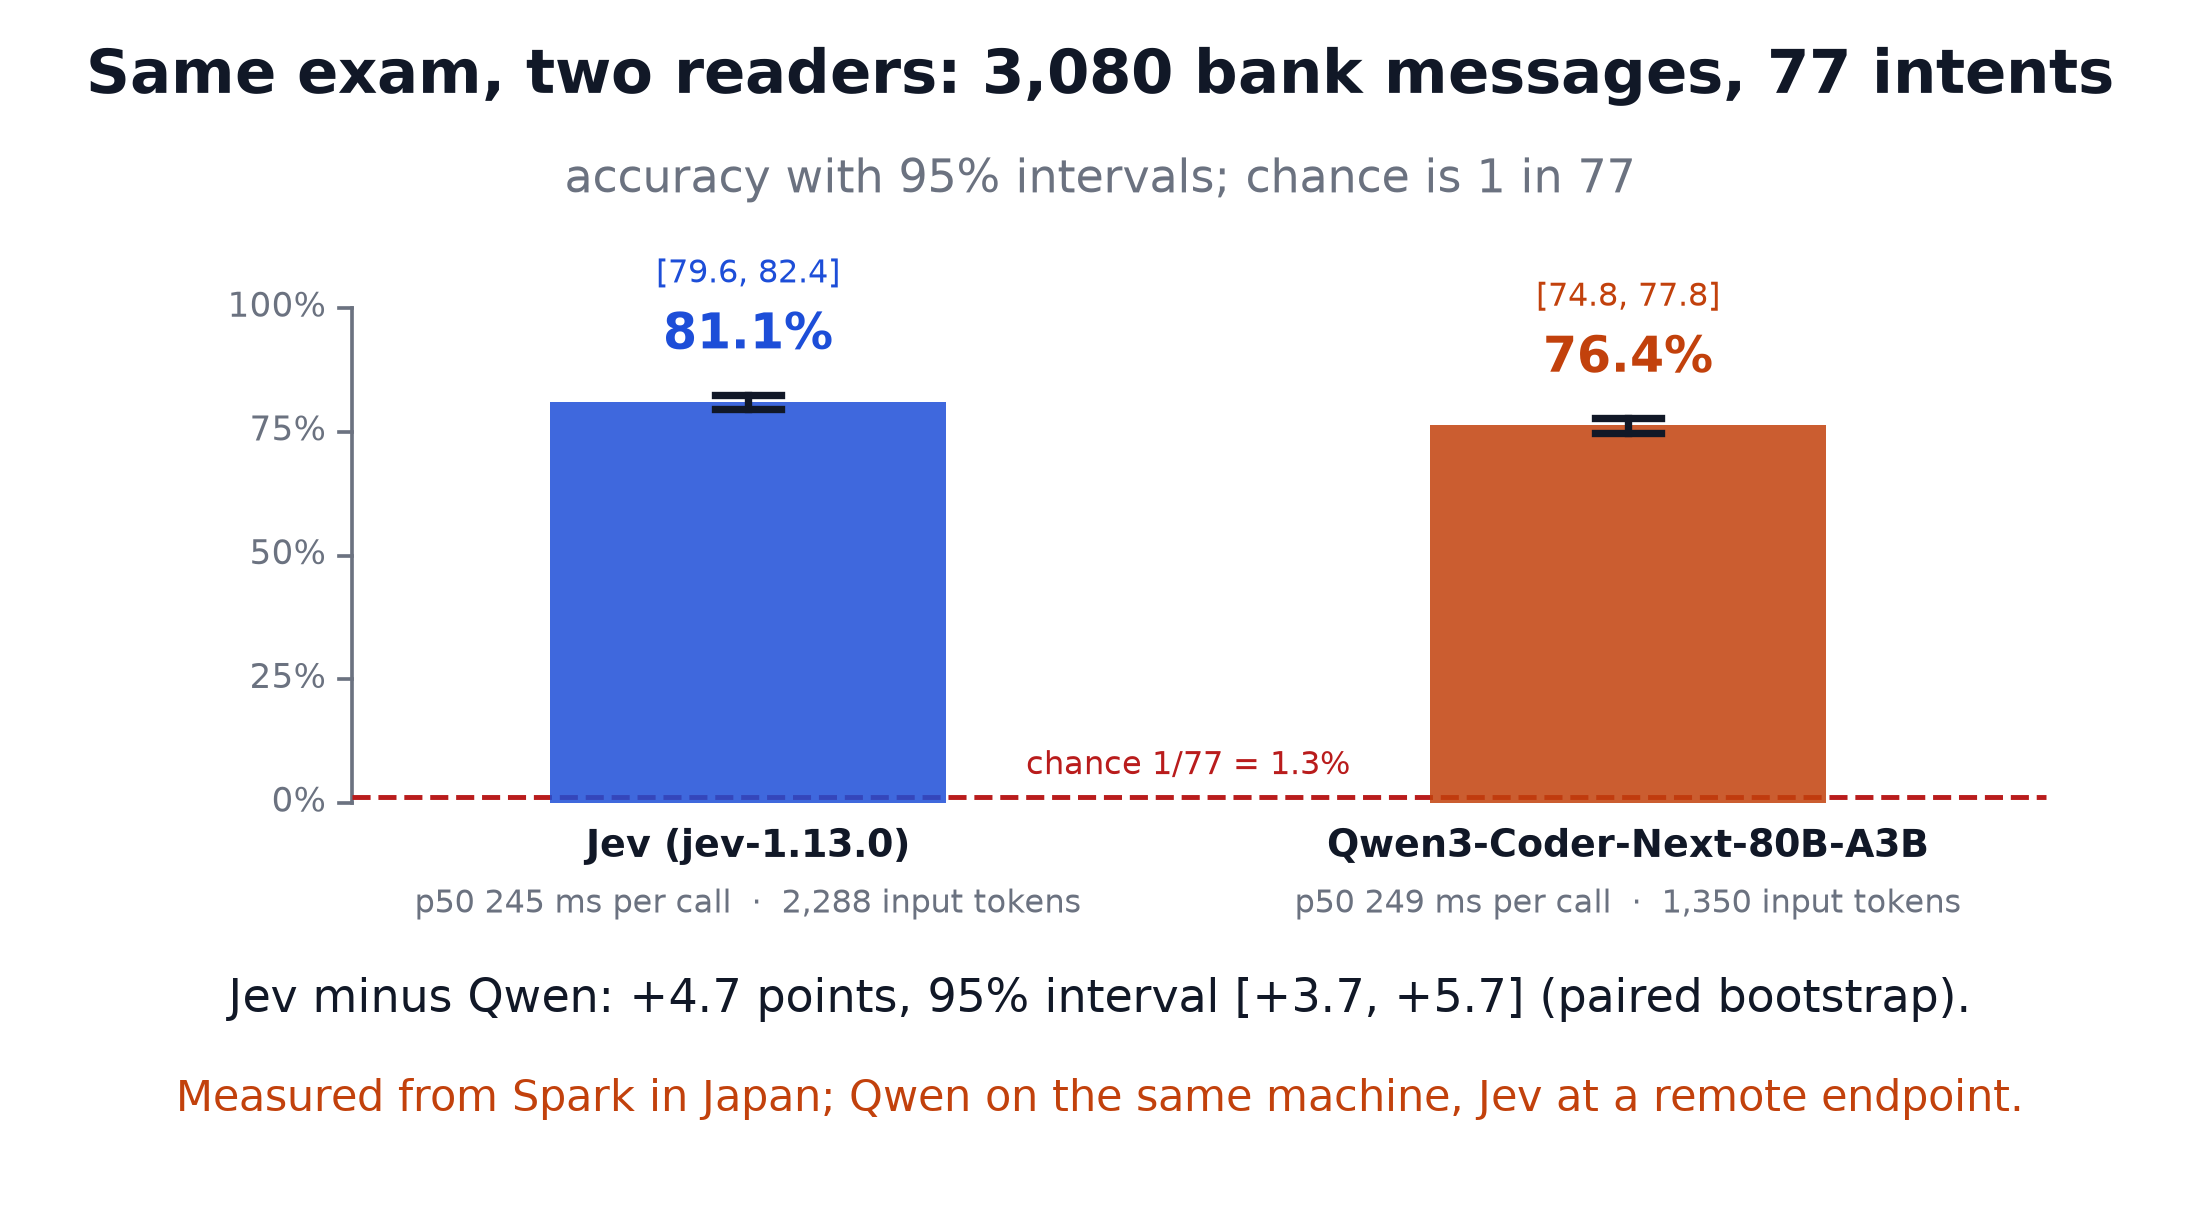
Speed was much closer. Jev took a median of 245 ms per request, while Qwen took 249 ms. I would not treat that as a clean speed comparison, though. Qwen was running locally and benefited from prefix caching, while Jev’s timing included a network request from Japan to a remote server.
There was also an important difference in output constraints. Qwen produced 53 invalid labels, or 1.72% of its answers, because nothing technically prevented it from returning something outside the allowed set. Jev’s output was constrained to valid choices. Even if I generously counted all 53 invalid Qwen answers as correct, Jev would still lead by about 3 percentage points.
So I see this result as evidence for this particular setup, not a general claim that Jev will outperform every LLM. I tested one Qwen model, with one prompt and one inference configuration.
8.3 Confidence was useful—but not reliable everywhere
I was also interested in Jev’s confidence scores, especially whether they could tell me when to hand a difficult case to another model.
|
Threshold on Jev’s confidence field |
Share handled by Jev |
Cascade accuracy |
Random routing at the same share |
|---|---|---|---|
|
Jev only |
100% |
81.1% |
|
|
≥ 0.5 |
96.2% |
80.7% |
80.9% |
|
≥ 0.7 |
87.2% |
80.5% |
80.5% |
|
≥ 0.9 |
74.5% |
79.7% |
79.9% |
|
≥ 0.99 |
58.2% |
77.6% |
79.1% |
|
= 1.00 |
49.2% |
76.9% |
78.7% |
|
Qwen only |
0% |
76.4% |
To understand that table, it helps to look first at how confidence matched accuracy.
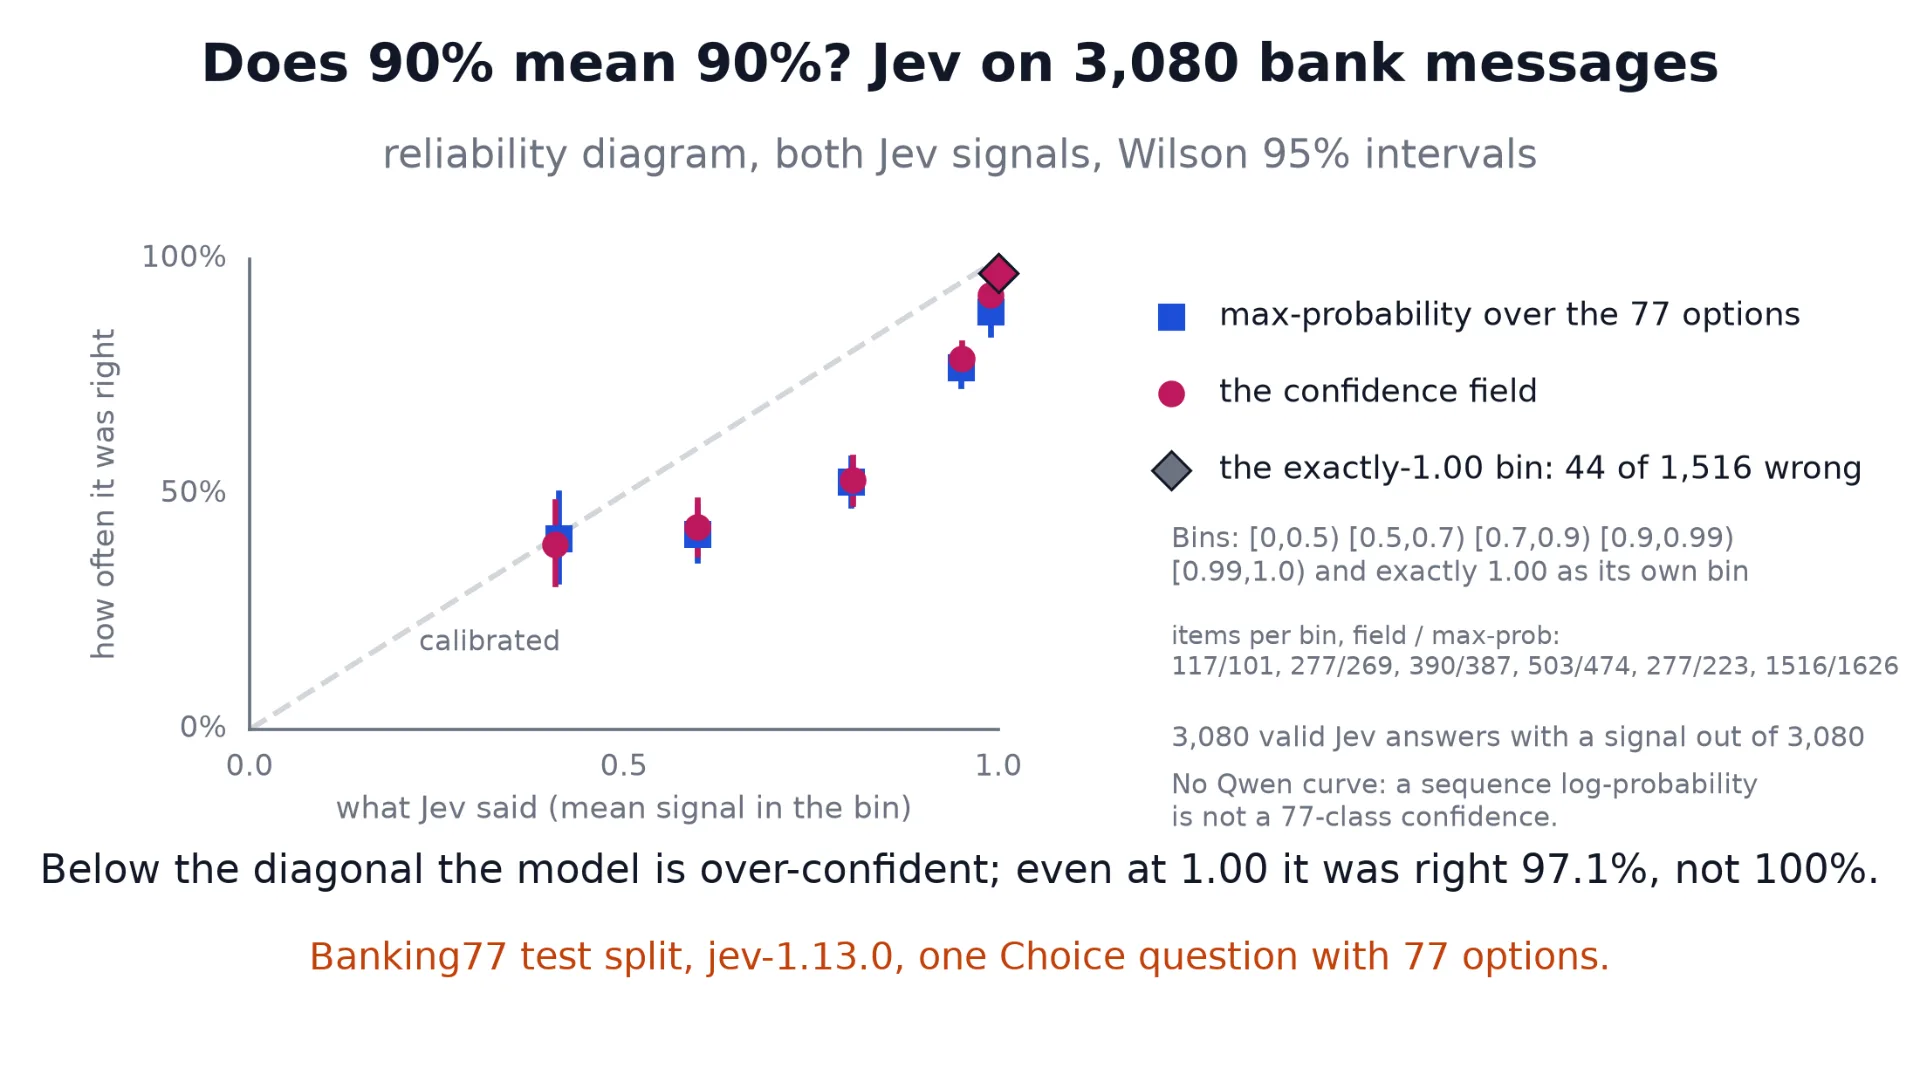
At the extremes, they worked reasonably well. For answers below 0.5 confidence, Jev was correct 39% of the time, against an average reported confidence of 0.41. At exactly 1.00 confidence, it was correct 97.1% of the time. That group contained 1,516 messages, including 44 mistakes, so full confidence was a strong signal—but certainly not a guarantee.
The middle was much less reliable. Between 0.7 and 0.9 confidence, Jev reported an average confidence of 0.81 but was correct only 53% of the time. Between 0.9 and 0.99, average confidence was 0.95 while accuracy was 79%. In other words, Jev became noticeably overconfident in those ranges.
That was useful to learn because calibration can look very different from one task to another. In my test, the separate confidence field and the highest choice probability behaved almost identically, with only a small calibration advantage for the confidence field.
8.4 The fallback model made things worse
Now I try the hybird approach: let Jev handle the cases it seemed sure about and give the harder ones to another model, Qwen in this case. In other words, I kept Jev’s answers above a confidence threshold and sent the lower-confidence cases to Qwen. This gave me surprising result.
Jev’s confidence did identify harder cases. At the 1.00 threshold, it was right on roughly 97% of the messages it kept, while the forwarded group was much harder. But Qwen only got 57% of those forwarded messages right.
As a result, every cascade I tested performed worse than simply using Jev alone. At the 1.00 threshold, replacing Jev’s low-confidence answers with Qwen fixed 84 mistakes, but introduced 211 new ones.
That was probably the most useful lesson from the experiment. Knowing which cases a model finds difficult is not the same as knowing another model can solve them. Jev’s confidence helped with the first problem; my choice of fallback model did not solve the second.
9. Short summary
9.1 When to use Jev, an LLM, or just code
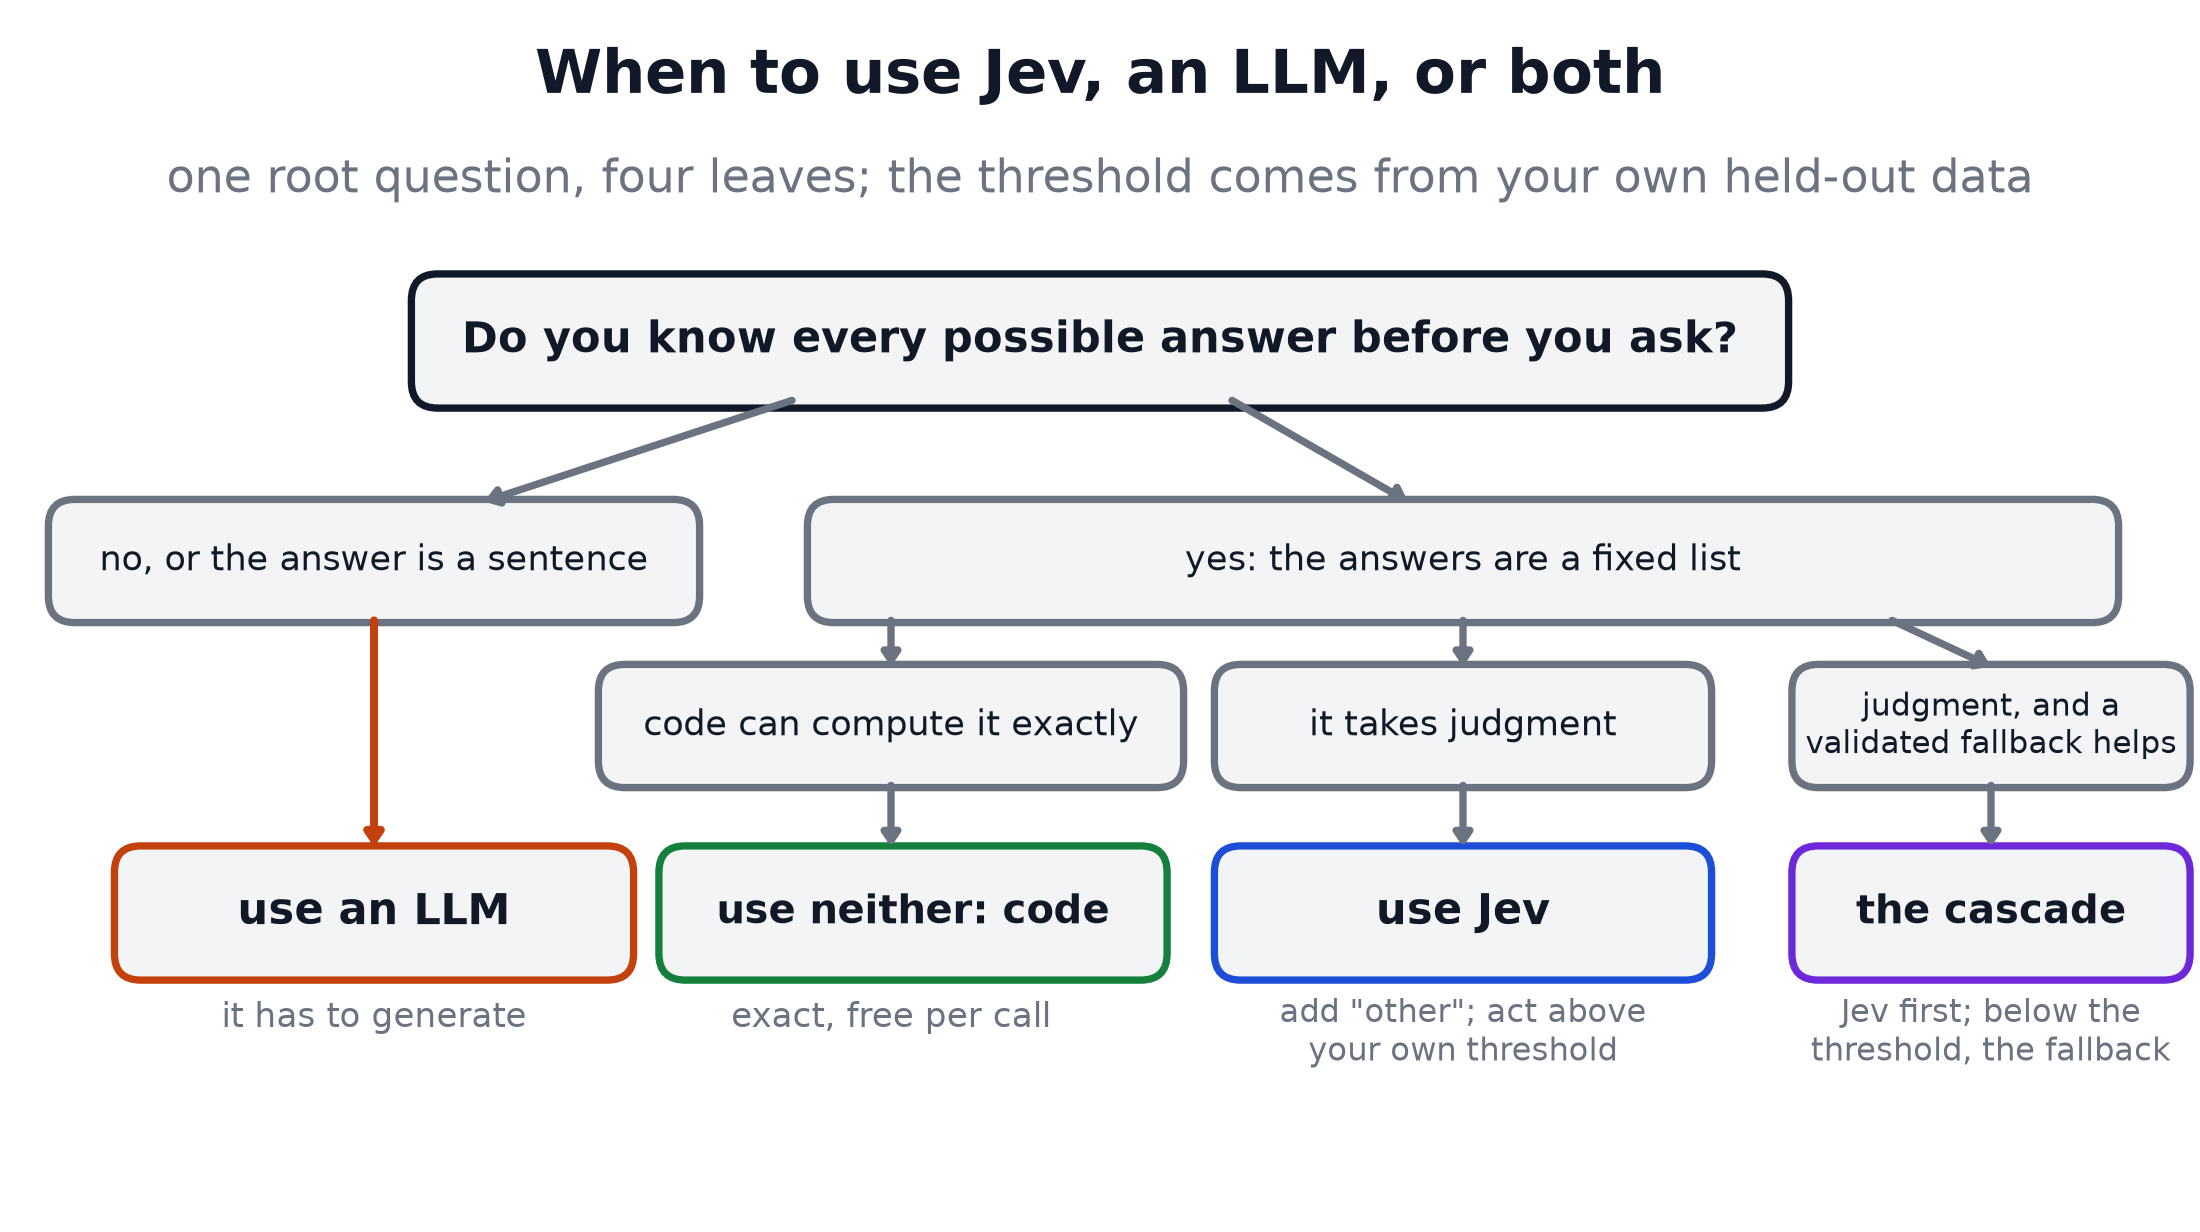
The most important factor to make to right decision is: you have to know what the possible answers are. If you need a paragraph, a summary, or a plan, use an LLM. Jev is not built for open-ended generation. If the answer is fixed, first ask whether you need a model at all. A database lookup, exact match, calculation, or date check is usually better handled with ordinary code. It is faster, cheaper, and easier to verify.
Jev starts to make sense when the input is messy language but the output still comes from a known set of choices. Routing a support message, detecting a refund request, or assigning a category are good examples. More importantly, test the confidence threshold separately rather than tuning and evaluating on the same data. It also helps to include an “other” option when the predefined categories may not cover every case.
And I would only add a fallback—another model or a human—if the results show that it actually improves the uncertain cases. Sometimes the better fallback is not more AI. It may simply be fetching missing data, validating the input, or asking the user for clarification.
9.2 What I learned from testing Jev
What I like most about Jev is how narrow its job is. You give it some information, define the possible answers, and get back probabilities your application can use directly. For workflows built around small, repeated decisions, that simplicity is appealing.
There are limits to what this test tells us. I used one English dataset with no out-of-category messages, one local LLM running on a single GPU, and one remote version of Jev. Jev’s internal architecture is not public, and the jev-latest alias can change over time, so anyone trying to reproduce the comparison should pin a specific version and document the setup.
If I plan to use Jev in real application, at first, I will start with a few hundred labelled examples from that exact use case. I will look closely at the mistakes, set a confidence threshold on separate validation data, and only add a fallback model if testing showed that it actually improved the difficult cases. The main lesson from this experiment is that neither a clean output format nor a high confidence score should be trusted on its own.
9.3 Terms worth remembering
-
System One model: a model that scores predefined answers directly instead of generating a written response.
-
Schema: the allowed structure of the output. Type-safe means the response follows that structure.
-
Probability distribution: probabilities assigned across the available answers, adding up to one. Jev also returns a separate confidence value summarising how concentrated that distribution is.
-
Calibration: how closely a model’s reported probabilities match its actual accuracy over many predictions. ECE measures the average gap across groups of predictions.
-
Temperature scaling / isotonic regression: post-training methods for adjusting probability estimates using held-out examples.
-
RLCD: TypeSafe’s term for training that rewards probabilities that better match real outcomes.
-
Cascade: a workflow where Jev handles the first decision and another model or a person handles cases below a chosen confidence threshold.
10. References and resources
Paper and dataset
-
Efficient Intent Detection with Dual Sentence Encoders — Casanueva, Temcinas, Gerz, Henderson, Vulić, 2020, arXiv:2003.04807. Introduces Banking77 and its 77 banking intents.
-
On Calibration of Modern Neural Networks — Guo, Pleiss, Sun, Weinberger, 2017, ICML, arXiv:1706.04599. Introduces temperature scaling and shows that modern classifiers are often over-confident.
-
Transforming Classifier Scores into Accurate Multiclass Probability Estimates — Zadrozny and Elkan, 2002, KDD. Isotonic regression as a calibration method.
-
Banking77 — Hugging Face
PolyAI/banking77; GitHubPolyAI-LDN/task-specific-datasets; CC-BY-4.0. Contains 10,003 training messages and 3,080 test messages, with 40 test messages per intent and no messages outside the listed categories. The Hugging Face card provides a legacy loading script; this article used the two CSV files from a fixed GitHub commit. -
TypeSafe has published documentation and a launch post for Jev, but no technical paper describing its architecture.
Documentation and tools
-
TypeSafe AI documentation — docs.typesafe.ai:
concepts/system-one,concepts/state,concepts/how-to-build-with-system-one,introduction/machine-learning-primer,models,primitives/choice,primitives/score, andcookbooks/parallel_questions. Covers request formats, limitations, the RLCD training description, and the example of asking several questions together. It does not disclose the architecture, parameter count, or training data. -
typesafe-sdk — pypi.org/project/typesafe-sdk, version 0.7.0, MIT licence. The Python client used in the cascade example.
-
Cloudflare Workers AI,
typesafe/jev— developers.cloudflare.com/ai/models/typesafe/jev. An alternative provider for accessing the model. -
vLLM — github.com/vllm-project/vllm, Apache-2.0. Used to serve Qwen with prefix caching enabled.
-
Code, results, and run log —
experiments/anddocs/run-log.mdin this project. Includes category descriptions, request templates and their hashes, results for each message, and the commands used.