

Full disclosure: I just wasted ~$4,000 in compute costs last month because of this very silent, very real bug that I’ve likely been victim to many times over my career and never even knew it.
If you are an ML practitioner, or work in deep learning, I can guarantee this has already happened to you, and you most likely never even realized it.
It might even be derailing your work right now.
In this article I highlight how a single mismatched tensor dimension can silently rewrite your loss function, gut your gradients, or poison your project, without PyTorch or TensorFlow ever raising an error. Specifically:
-
What silent broadcasting is
-
Real world examples of how silent broadcasting destroys models
-
Preventing silent broadcasting errors in your training pipeline
This problem is notorious, rarely spoken about, and a serious threat to your modeling pipeline. Think I’m being overly dramatic? It’s likely that one (or more) of the models you’ve attempted to train in your career has suffered from this very common bug.
What silent broadcasting is
Broadcasting is sometimes useful. It allows you to do elementwise math on tensors of different shapes without writing tedious loops or reshapes.
It works like so:
-
If two dimensions are equal, they match.
-
If one of them is
1, it gets “stretched” to match the other. -
If a tensor is missing a dimension entirely, it’s treated as
1. -
If none of the above holds, you finally get an error.
Broadcasting was designed to make (N, D) + (D,), ops like adding a bias vector to every row of a batch, simple.
This same rule that makes that op convenient also makes (N, 1) and (N,) “compatible,” even though one is a column vector and the other is a flat vector. Combining them produces an (N, N) matrix that is very likely not what either tensor was supposed to represent.
This (N, 1) and (N,) compatibility is the hidden killer that exists in all tensor frameworks.
For example:
The danger here is that if you intended an elementwise (4,) + (4,) operation, there is no error. You just forgot to squeeze or unsqueeze a perfectly valid mathematical operation in both frameworks.
The failure mode is: this op runs, silently.
The loss goes down and the gradients flow. But your model is training towards garbage.
Let me explain in more detail with some real world examples.
Real world examples of how silent broadcasting destroys models
Example 1: Your regression loss quietly optimizes for the mean, not the input
This is the single most common version of the bug, and it’s brutal because loss curves look completely normal.
In PyTorch:
Same for Tensorflow/Keras:
pred - target broadcasts to (N, N), computing target[i] - pred[j] for every pair (i, j) instead of the N differences you intended. The “loss” you’re minimizing is actually:
Take the derivative with respect to any single prediction and set it to zero, and every converges to the same value: the batch mean of the targets.
The true minimum of this broken objective is a model that ignores its input entirely and just memorizes . Training doesn’t crash, and the loss drops fast, because collapsing to a constant is a super easy thing to optimize for.
You just end up with a model that has learned nothing about the relationship between x and y. I think about how many times I’ve actually encountered this in the wild and I cringe.
Here’s a perfect example from /r/deeplearning:
The answers: New models, new features. Not a single mention of the most common reason for this error. In fact, I’m positive that you’ll see models trained like this in production because the loss looks so asymptomatic and the mean value solution can actually produce reasonable performance.
Another in the wild example:
Again, the answers fail to pinpoint the exact problem, because it’s so notoriously hidden. The output is a linear layer, batched: (N, 1), while the targets are (N,). Even though this post is aged, the cause of this error is nowhere in the comments. I assert that the problem is still plaguing the machine learning community and no one is talking about it.
Example 2: Policy-gradient loss destroys credit assignment in RL
Same shape mismatch, worse consequences, because the whole point of policy gradients is per-sample credit assignment. This cost me actual money.
log_probs * advantages broadcasts to (N, N). Once you take the mean, the algebra collapses to -mean(log_probs) * mean(advantages), a single scalar advantage applied uniformly to every action in the batch, instead of each action being reinforced or punished by its own advantage.
This can be particularly damaging when advantages are normalized to approximately zero mean. In that case, the broadcasted product can produce an extremely weak or nearly zero policy-gradient signal even though the individual advantages contain substantial information.
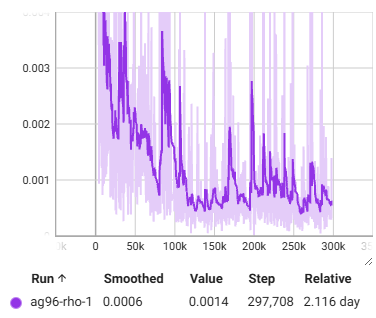
The entire mechanism of “increase the probability of actions that turned out well, decrease the ones that didn’t” is gone. The agent doesn’t obviously fail because RL training is noisy by nature. RL policies plateau for a multitude of reasons, so one that’s stuck because its gradient signal has been averaged looks identical to a policy thats misperforming because of a bad hyperparameters or a poorly tuned reward function.
Turns out, weeks of reward shaping could have been replaced by adding a .squeeze(-1) op on a value head.
Here’s an example right out of my own tensorboard.
So, how might one prevent this “feature” from killing your training process?
Preventing silent broadcasting errors in your training pipeline
The fix for all the examples above is the same one line habit, applied at the two places broadcasting typically errs: loss computation and mask application.
This costs nothing at runtime and turns every silent broadcast into a loud, immediate AssertionError at exactly the line that caused it.
In TensorFlow, tf.debugging.assert_shapes([(pred, target.shape)]) or tf.ensure_shape does the same job and, unlike a bare Python assert, still fires inside a compiled tf.function graph.
For training code, this is often more valuable than trusting the framework to decide whether two tensors are broadcast-compatible. Don’t rely on the framework to answer the question: “is this semantically correct?”
Never trust an implicit squeeze
Prefer pred.squeeze(-1) over bare pred.squeeze() (which silently drops every size-1 dimension, including your batch dimension if N == 1), and prefer libraries like einops for anything with more than two axes:
einops operations fail on shape mismatches instead of broadcasting through them. That’s the entire value proposition for this use case.
Add adversarial shape unit tests, not just correctness tests.
Write tests that deliberately pass in an (N, 1) where an (N,) is expected and assert that your loss function raises, not that it returns a number:
Use static shape typing (if available)
Tools like jaxtyping or torchtyping let you annotate expected shapes Float[Tensor, "batch seq"]) and catch mismatches via runtime checks or static analysis before the tensors ever reach an op that would silently broadcast them.
When loss goes to NaN, bisect the forward pass, don’t just lower the learning rate
Hook into intermediate activations register_forward_hook in PyTorch and check for the first tensor that contains a NaN. Chasing NaNs by shrinking the learning rate or clipping gradients treats the symptom; finding the exact op that produced the first NaN finds mask bugs in minutes.
Wrapping up
Don’t waste time on this bug. Know that it exists, and catch it before it happens with some very easy to implement one line assertions. I assure you, it will show up in your training pipeline at some point or another and baffle you.
Thanks for reading!