

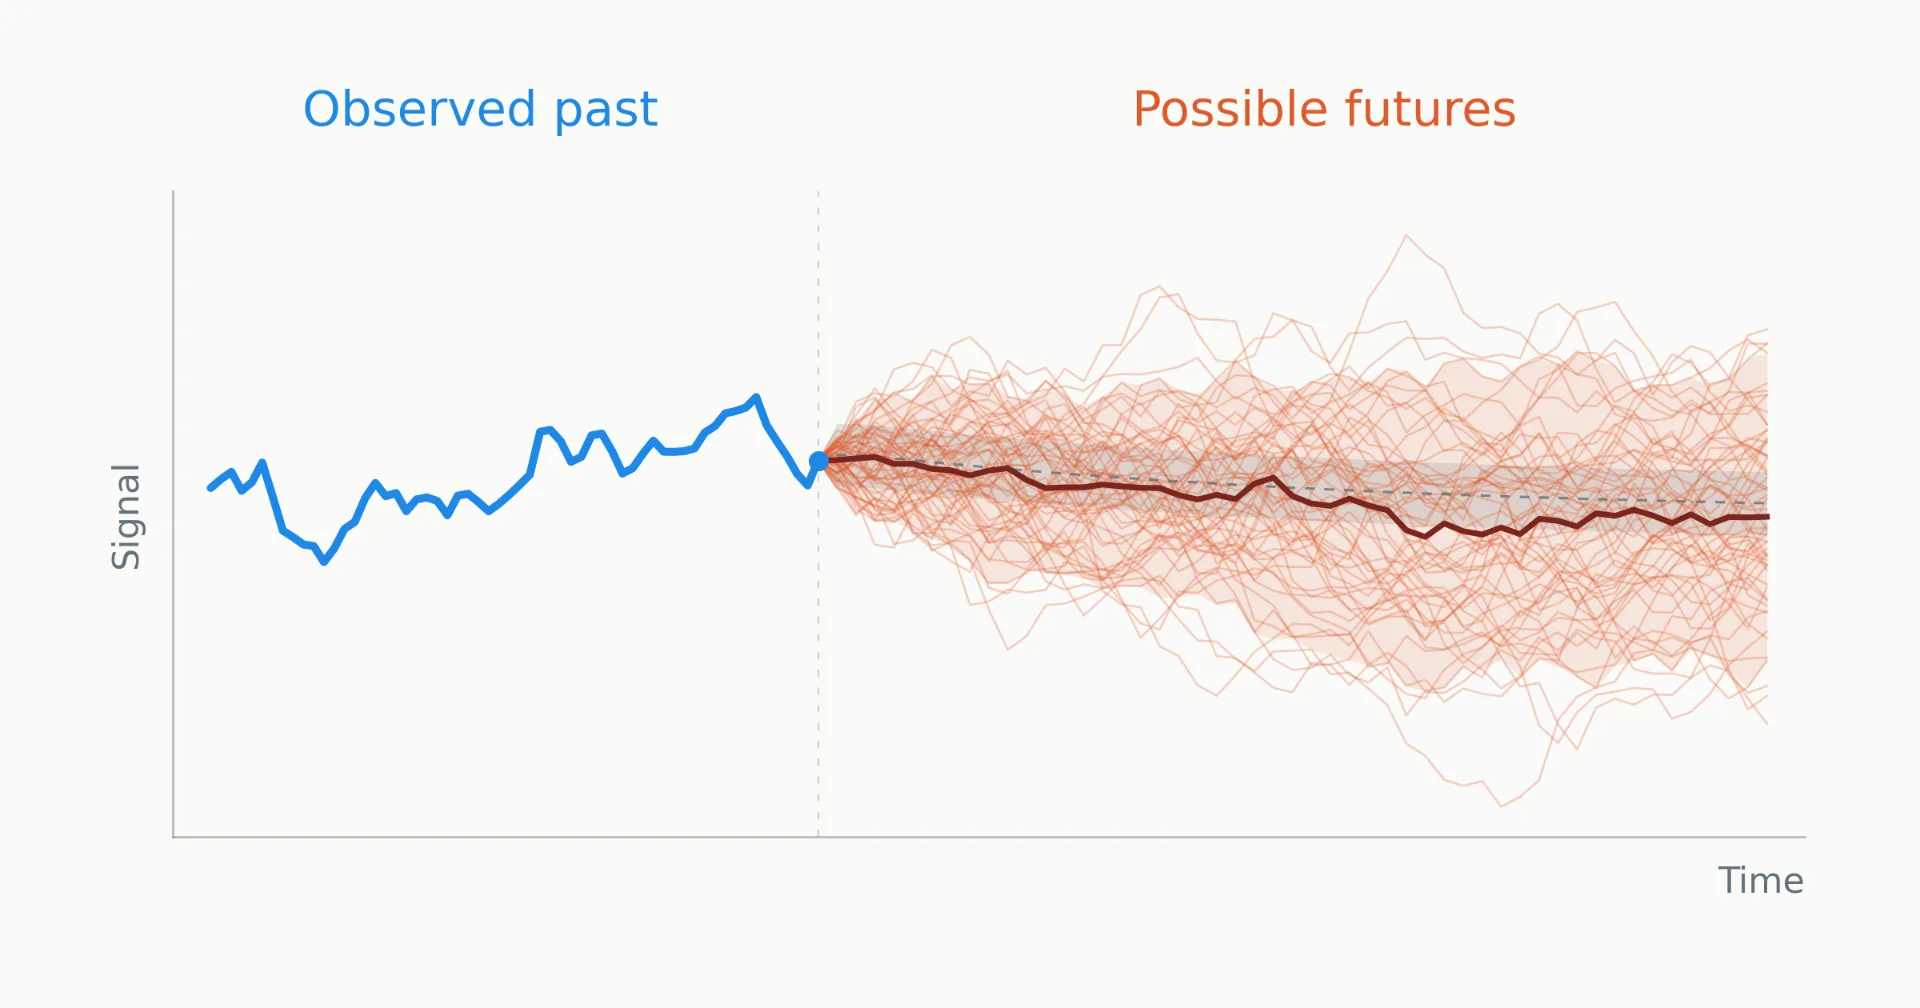
In a previous article, we saw why training with MSE forces a model to report only the conditional mean, and how Gaussian NLL lets it learn an honest per-step uncertainty as well. That was the one-step story. This post picks up where that left off.
Everything we built in Part I — the Gaussian NLL, the two-term loss, the proof that the model learns both the conditional mean and the conditional variance — was about one-step-ahead prediction: given a context window of observed values, predict the distribution of the very next value .
At inference time, in any real application, this is rarely enough. You want to know what happens over the next 10, 100, or 1000 steps. You want a forecast, not a single prediction. And if your model is probabilistic, you want that forecast to carry honest uncertainty all the way to the end of the horizon.
This post is about how to do this correctly. One could think immediately of the naive approach, that is applying the model repeatedly, feeding its predictions back as inputs is secretly a deterministic operation that discards the uncertainty the model spent so much effort learning. Fixing this requires thinking carefully about what a joint distribution over future values actually is, and how to approximate it with Monte Carlo sampling. The fix is barely more code than the naive version, but it gives a fundamentally different and fundamentally better forecast.
Everything here is built and checked in the companion notebook: the two rollout approaches, applied to the same trained model, on the same signal, with coverage and PIT diagnostics (all explained in this post).
···
Recapping the one-step setting
In Part I, we trained a model that takes a context window of observed values and outputs two numbers:
These parameterise a Gaussian distribution over the next time step :
This is a conditional distribution, it tells us everything about given that we know through exactly. The uncertainty captures the irreducible randomness at that one step: the noise we cannot predict no matter how good the model is. The Gaussian NLL loss trained the model to get both and right, that is the conditional mean and the conditional variance at each individual step.
Clean, well-defined, and exactly what the loss was designed to learn. The problem starts the moment someone asks: okay, but what happens over the next 50 steps?
···
The multi-step inference problem
In any real application, you don’t just need the next value. You need a forecast, a prediction over an extended horizon. “Will this signal cross the alarm threshold sometime in the next hour?” “What does the load profile look like for the rest of the day?” These questions require predicting not one step but many.
Suppose we want to forecast the next steps: . The quantity we want is the joint predictive distribution:
Notice what this is. It’s not separate distributions. It’s one distribution over -dimensional space, a distribution over entire sequences. The value at step depends on what happened at steps and . The future values are correlated with each other because each one feeds into the next.
There’s a standard tool from probability theory, which is the chain rule that factors any joint distribution into a product of conditionals:
Each factor is a one-step conditional distribution: “what’s the distribution of the next value given everything before it?”, which is exactly what the model was trained to produce.
So in principle, you can build the joint distribution one step at a time: predict step given the observed history, then predict step given the observed history plus step , then step given all of the above, and so on.
But here’s the catch. For step , the conditioning includes , a value you don’t actually have. You only observed up to . Everything beyond that is the model’s own prediction. And that prediction is uncertain, it’s a distribution, not a number.
How you handle this unknown is the entire story of this post. There are two strategies that look similar in code but are conceptually and statistically very different.
Two approaches for probabilistic autoregressive forecasting.
Strategy A: The deterministic rollout: feed back
The simplest thing you could do: at each step, predict , take only the, plug it into the context as if it were an observed value, and move on. The recursion looks like this:
You get a sequence of means and a parallel sequence of sigmas . Looks like a complete probabilistic forecast. In code, it’s very straightforward:
Simple and clean, but, unfortunately wrong in a way that actually matters.
Think about what the model is being asked at step . It receives a context that ends with , a specific, exact number. The model treats it as if that value actually happened. So when it produces , it’s answering the question: “Given that the previous value was exactly , how uncertain am I about the next step?”
But, this is the wrong question. The previous value was not exactly . It was drawn from a distribution . It could have been higher or lower. The correct question is: “Given that the previous value was somewhere around with spread , how uncertain am I about the next step?”
The second question always has a strictly larger answer. Always. Because it has to account for two sources of randomness: the noise at the current step plus the uncertainty inherited from the previous step.
By feeding back, you’re pretending the previous prediction was perfect. The values you get capture only the local noise at each step in isolation, the irreducible randomness if the input were known exactly. They completely miss the propagated uncertainty, the fact that every input from step onward was itself uncertain. The consequence: deterministic rollout systematically underestimates forecast uncertainty, and the underestimation gets worse the further out you go. At step , you’re ignoring one step of propagated uncertainty. At step , you’re ignoring 49 steps of it.
Imagine you’re navigating by compass, and each reading has a small error. One step off course is fine, that’s . But if you take 50 steps, each slightly off, the errors accumulate. You could be very far from where you think you are.
Now here’s the key: if you recalculate your position at each step assuming you’re exactly where you planned to be, not where you actually are, your navigation uncertainty stays small on paper even though you’re actually drifting. After 50 steps, your map says “uncertainty: 2 meters.” Reality says you might be 200 meters off. The map isn’t lying about any single step’s compass error. It’s lying by pretending that every previous step landed perfectly, which none of them did.
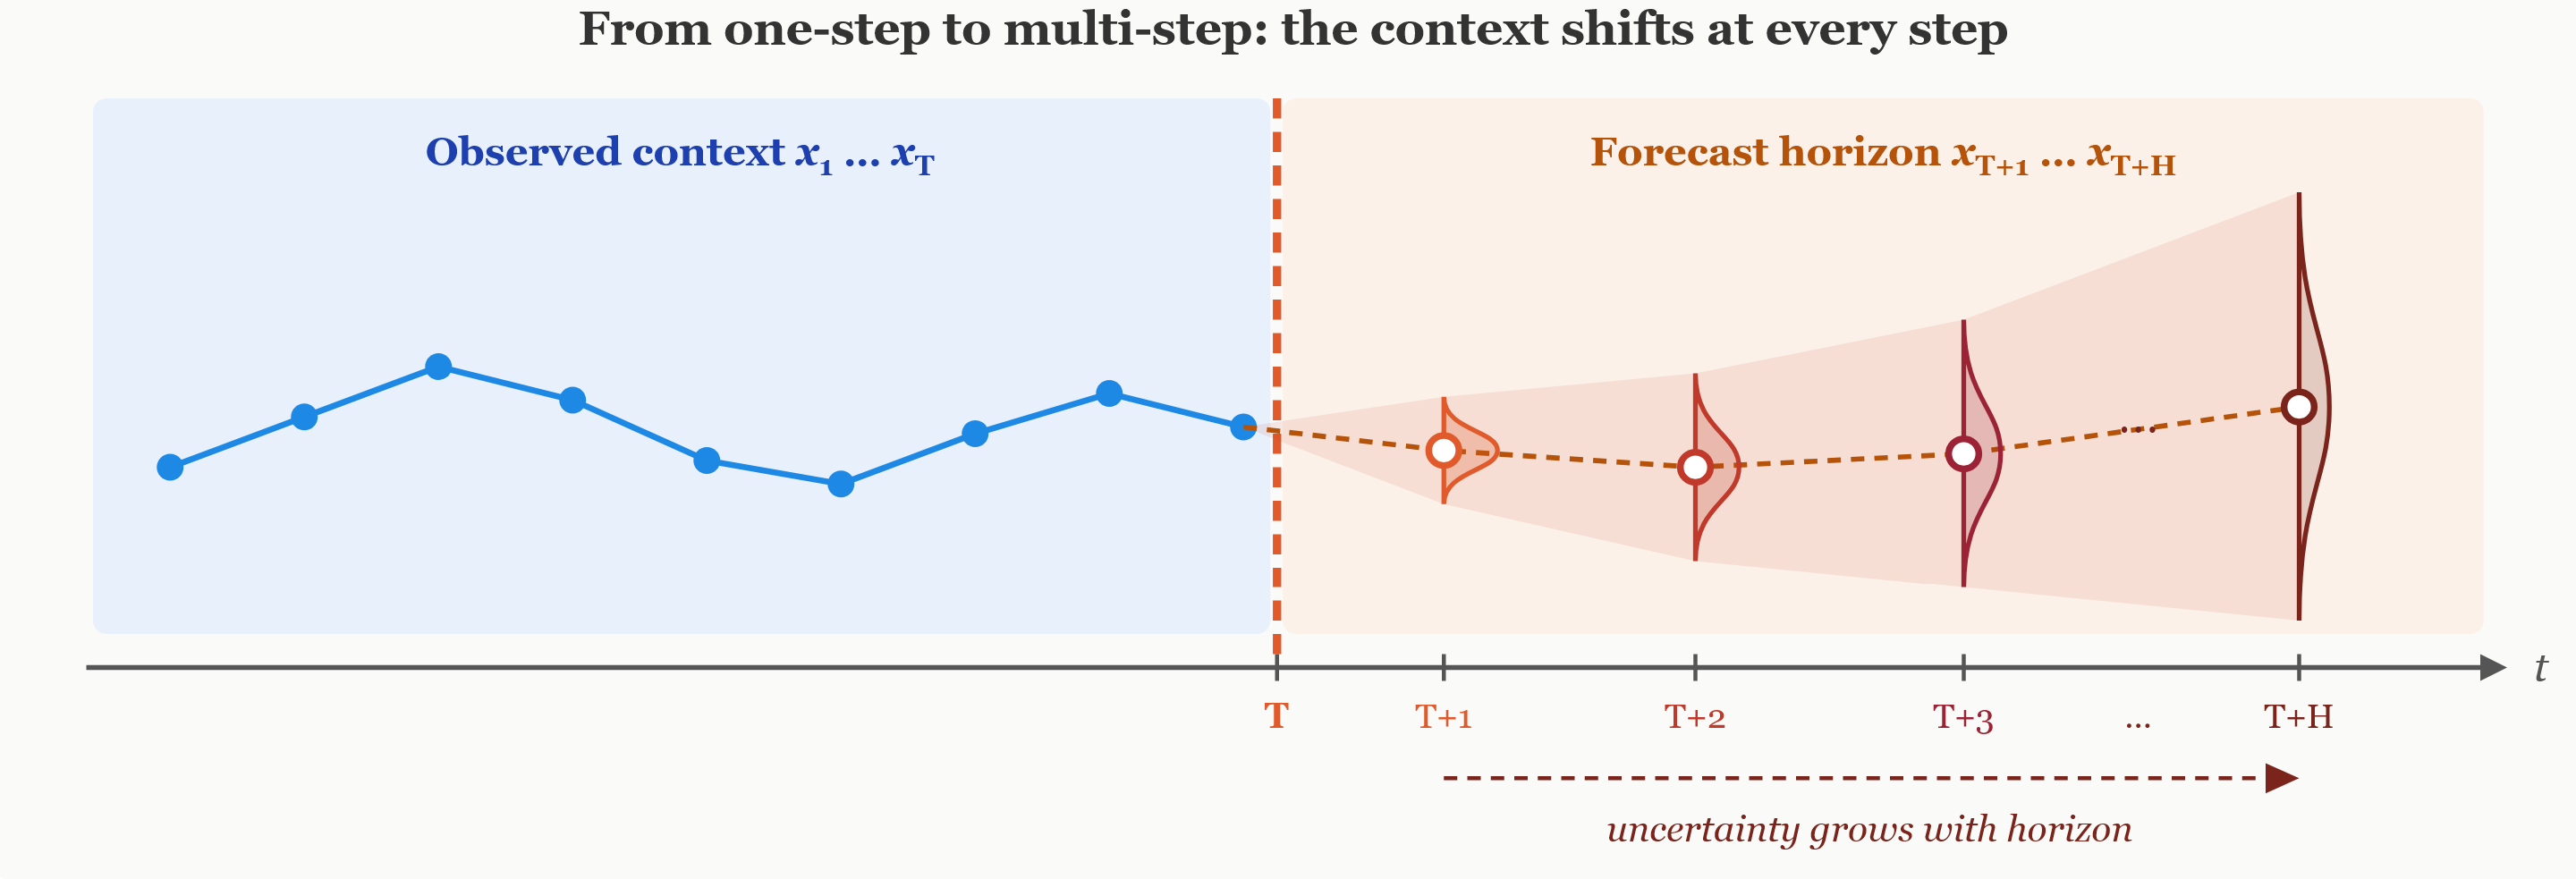
Probabilistic multi-step inference problem.
That’s exactly what deterministic rollout does. Each is an honest answer to a dishonest question. The model is asked “how uncertain are you about the next step, given that the last step was exactly ?” and it answers correctly. But the premise is false. The last step wasn’t exactly . It was drawn from a spread. And by the time you’re 50 steps out, you’ve told 49 lies about perfect inputs, and the accumulated dishonesty shows up as a confidence band that’s far too narrow.
Strategy B: The stochastic rollout: sample and feed back
The fix is simple: instead of feeding back, draw a random sample from the predicted distribution and feed that back. Run this times to get plausible futures.
Step by step, for one trajectory (labeled ):
The superscript marks one trajectory, one possible future. Because step 1 was a random draw, the value differs from . This means the model sees a different context at step 2, producing different , leading to a different sample, and so on. Every downstream step is affected by the randomness at every upstream step. Uncertainty propagates through the chain, compounding naturally.
But one trajectory is just one possible future, a single random path through the space of sequences. To approximate the full joint distribution, you run independent trajectories, each from the same observed history , each diverging because of fresh random draws.
In code, the key trick is to process all trajectories as a single batch, one forward pass per horizon step, not separate passes:
Take a minute to compare the two functions. The structure is identical, a loop over horizon steps, with a sliding context window. The only difference is one line: deterministic rollout appends mu, stochastic rollout appends sample. That one-line change is the difference between throwing away uncertainty and propagating it correctly.
Why uncertainty must grow: the law of total variance
The intuition above, propagated uncertainty makes things wider can be made precise with a single theorem: the law of total variance:
In plain language: the total uncertainty about is the sum of two parts. First, the average noise you’d see even if you knew exactly. Second, the extra spread caused by the fact that different values of lead to different predictions for . Since variances can’t be negative, the total is always at least as large as either part alone.
Apply this to forecasting. Let and :
Term I is the expected one-step noise at step , averaged over possible values of . Even if we knew exactly, the model would still be uncertain about . This is what deterministic rollout captures.
Term II is the variance of the conditional mean caused by the randomness in . Since is uncertain and the prediction for depends on it, the center of the step-2 prediction is itself a random variable. This term is zero in deterministic rollout, because feeding back treats as fixed, making a constant rather than a random variable. Let’s spell it out to see exactly where the gap is. Assume the model is a perfect one-step predictor and define:
-
,
-
, which depends on what was
-
, also a function of
Note the key thing: and are written as functions of because the prediction at step 2 changes depending on what happened at step 1. If is high, shifts one way. If is low, it shifts another.
Deterministic rollout evaluates at one specific input: . It gets:
While stochastic rollout, through its many trajectories, captures both terms of the law of total variance:
Therefore:
The inequality holds because . And it’s strictly positive whenever actually varies with , which is true for any signal with structure. The gap is the propagated uncertainty that deterministic rollout misses entirely.
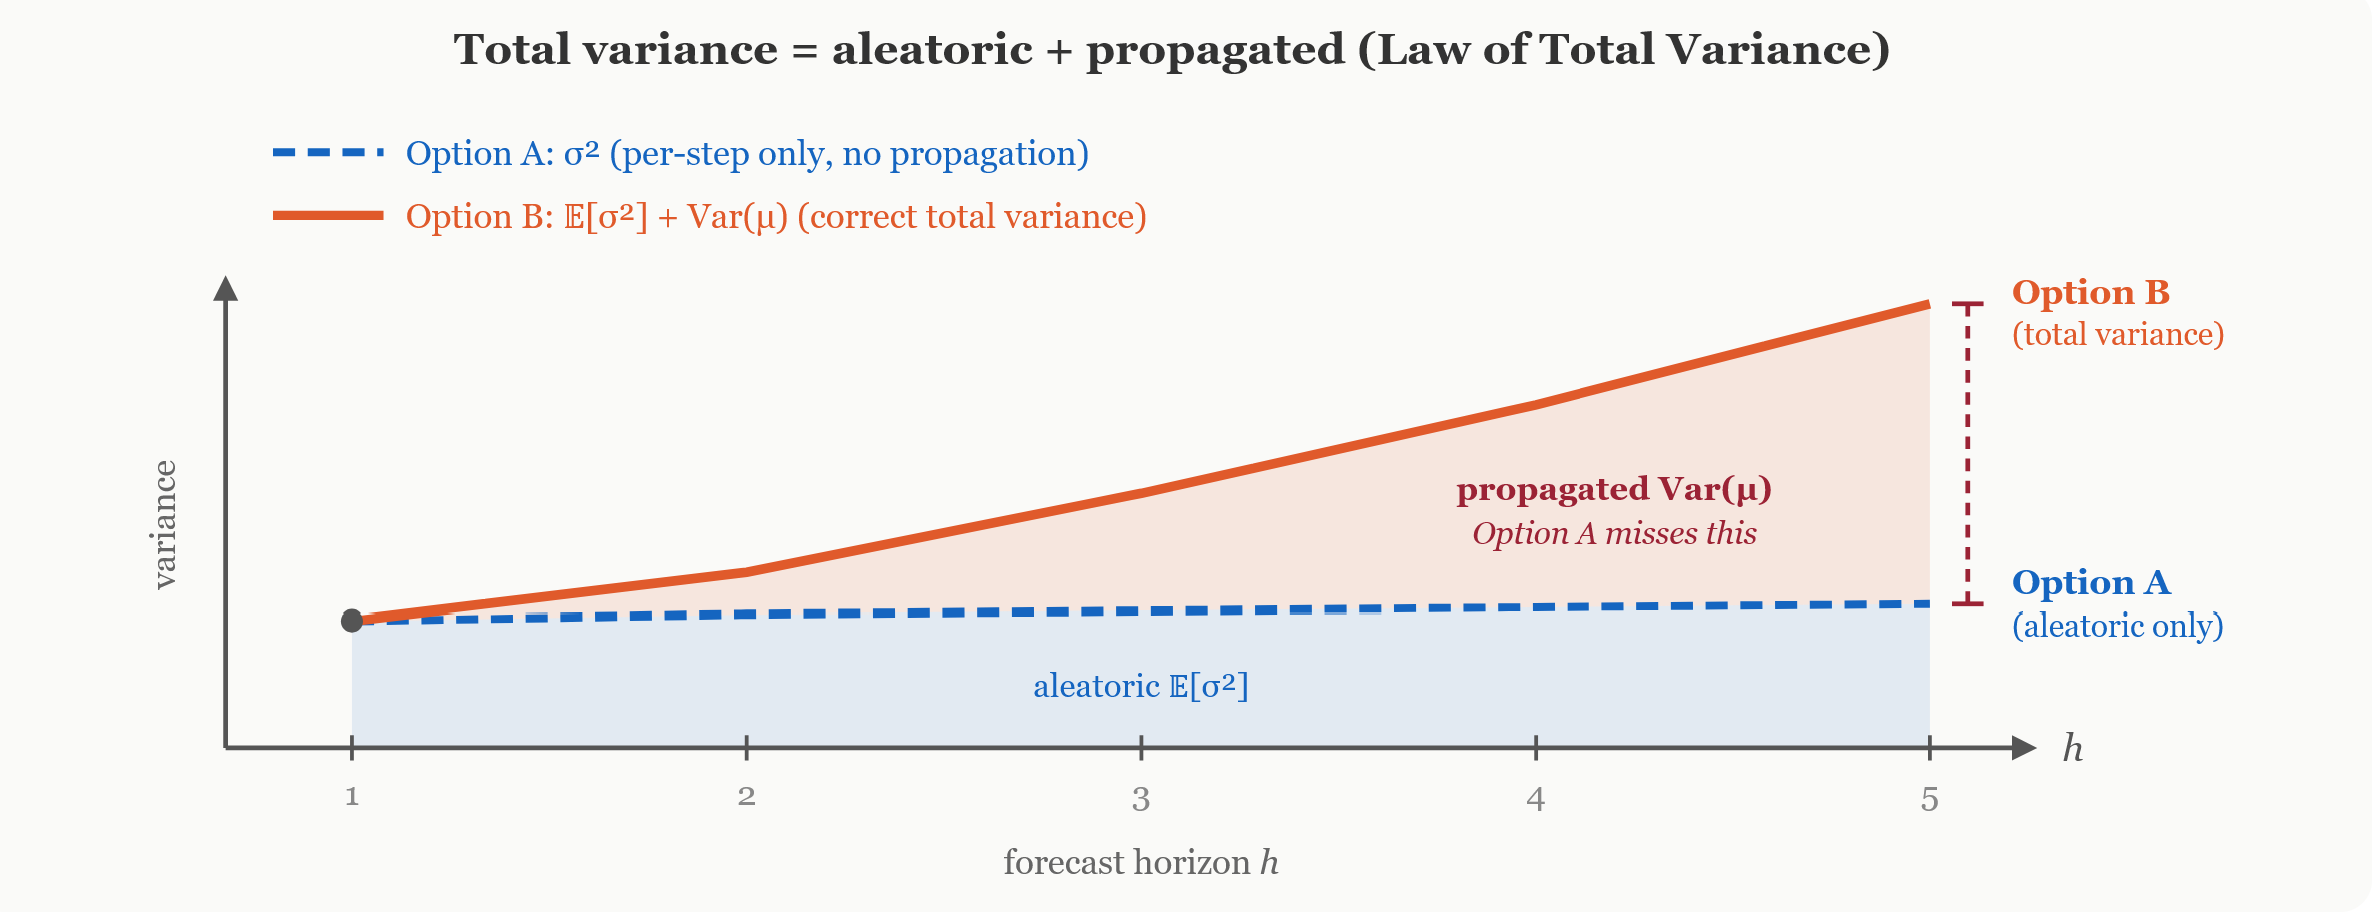
Law of total variance in probabilistic autoregressive forecasting
At step , the same decomposition applies again. The model needs as input, but is itself uncertain and its uncertainty already includes one layer of propagation from step . So step inherits an even larger input uncertainty, which generates an even larger propagation term, which feeds into step , and so on.
Each step adds its own layer on top of everything accumulated before. Deterministic rollout misses every one and the gap doesn’t just exist, it grows at every step.
···
Monte Carlo Approximation: parallel trajectories
The stochastic rollout captures the right uncertainty, but one trajectory is just one sample from the joint distribution. To approximate the full distribution, you run independent trajectories.
Imagine 500 people in a room, each holding a copy of the same observed history on a piece of paper. At this moment, all 500 papers are identical.
Round 1: everyone feeds the same history into the model. Since the inputs are identical, everyone gets the same . Now each person rolls their own dice, drawing a random sample from . Person 1 gets 0.41. Person 2 gets 0.62. Person 3 gets 0.55. All different numbers, because each is a separate random draw from the same bell curve. Each person writes their number at the end of their paper. The papers are no longer identical.
Round 2: each person feeds their own paper into the model. Person 1’s paper ends in 0.41, person 2’s ends in 0.62, just different inputs produce different for each person. Each rolls their dice again. The papers now differ in the last two values.
Round 3, 4, 5, … : same thing. At every round, the papers diverge further because each person’s context is shaped by all their previous random draws.
After rounds, you have 500 different possible futures. They started identical (same real history) and diverged because each person rolled their own dice at every step. This divergence is the uncertainty propagation and the amount they’ve spread apart by round is the honest forecast uncertainty at that horizon.
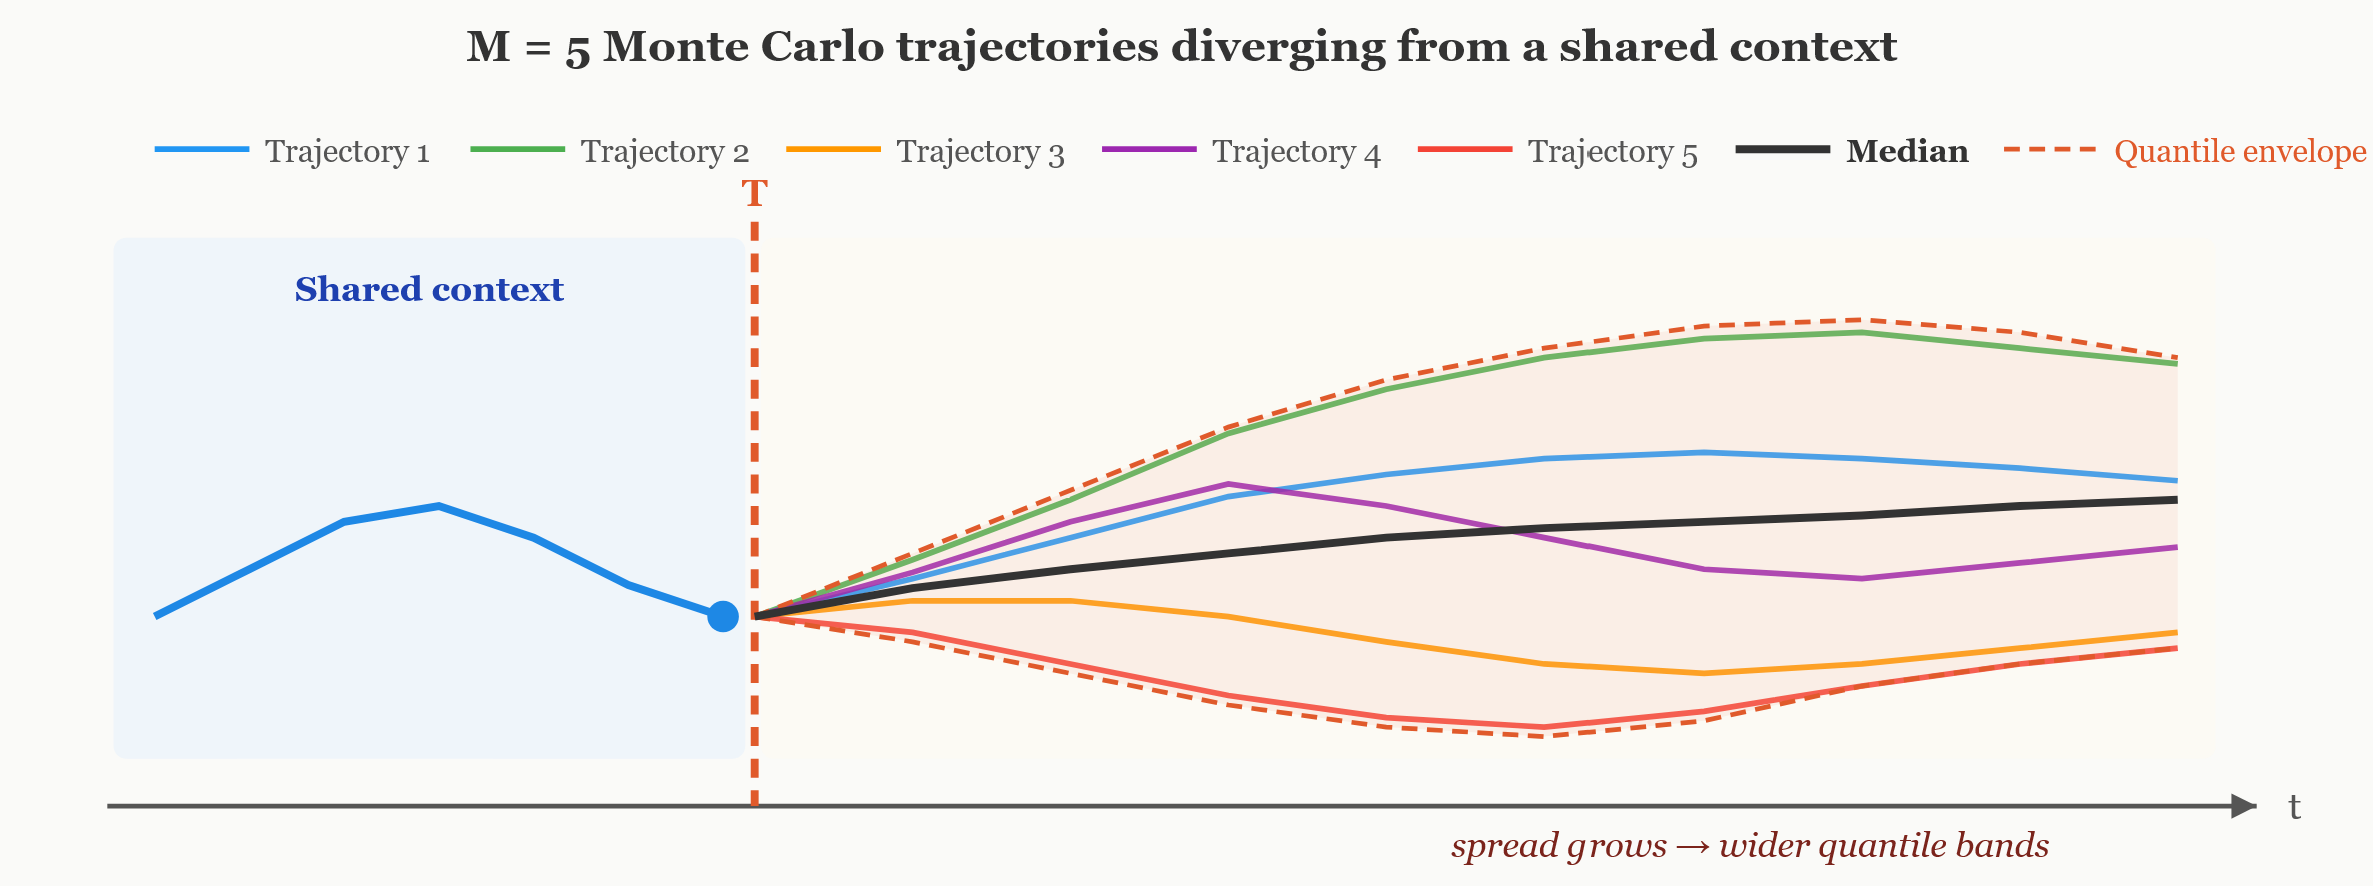
Monte Carlo approximation of stochastic rollout.
This procedure is the Monte Carlo approximation of the joint distribution. You can’t write that distribution down in closed form, since the model is a nonlinear neural network, but you can sample from it exactly through the stochastic rollout. Each trajectory follows the chain rule factorisation we wrote earlier, sampling from the correct one-step conditional at every step. With enough samples, you can estimate any property of the joint distribution you want: means, quantiles, exceedance probabilities, whatever.
How many is enough?
The estimation error shrinks as . In practice:
-
For the median (central forecast): to is usually enough. The median converges fast because it only needs the rough middle of the distribution.
-
For the 5th or 95th percentile (tail behaviour): you need more. At , the 5th percentile is approximately the 2nd or 3rd smallest value out of 50 one different random draw shifts it a lot. For reliable tail estimates, to is safer.
-
For coverage checks across many test examples: moderate per example –) is fine, because averaging across test cases smooths the noise.
The cost is linear: trajectories means forward passes per horizon step. But with batching, processing all contexts as a single batch, as in the code above, this is one GPU kernel launch per step, not separate calls. On the synthetic signal from Part I, 500 trajectories over 50 steps runs in seconds on a CPU.
···
From trajectories to a forecast
You have a matrix of shape : row is one trajectory, column is one horizon step. How do you turn this into a usable forecast?
The central forecast: the median. At each horizon step, take the median across trajectories:
Why median and not mean? If a few trajectories wander off to extreme values (it happens, especially at long horizons), the mean gets pulled toward them. The median doesn’t care, it just looks at the middle. For symmetric distributions both are equivalent, so there’s no cost in switching.
Uncertainty bands: quantiles. Sort the values at each step. The band between the -th and -th percentiles is a prediction interval at level . For a 90% band, take the 5th and 95th percentiles.
No Gaussian assumption here. You’re not computing . You’re reading directly from where the trajectories actually went. If the distribution at some horizon step is skewed or heavy-tailed, the quantile band reflects that automatically.
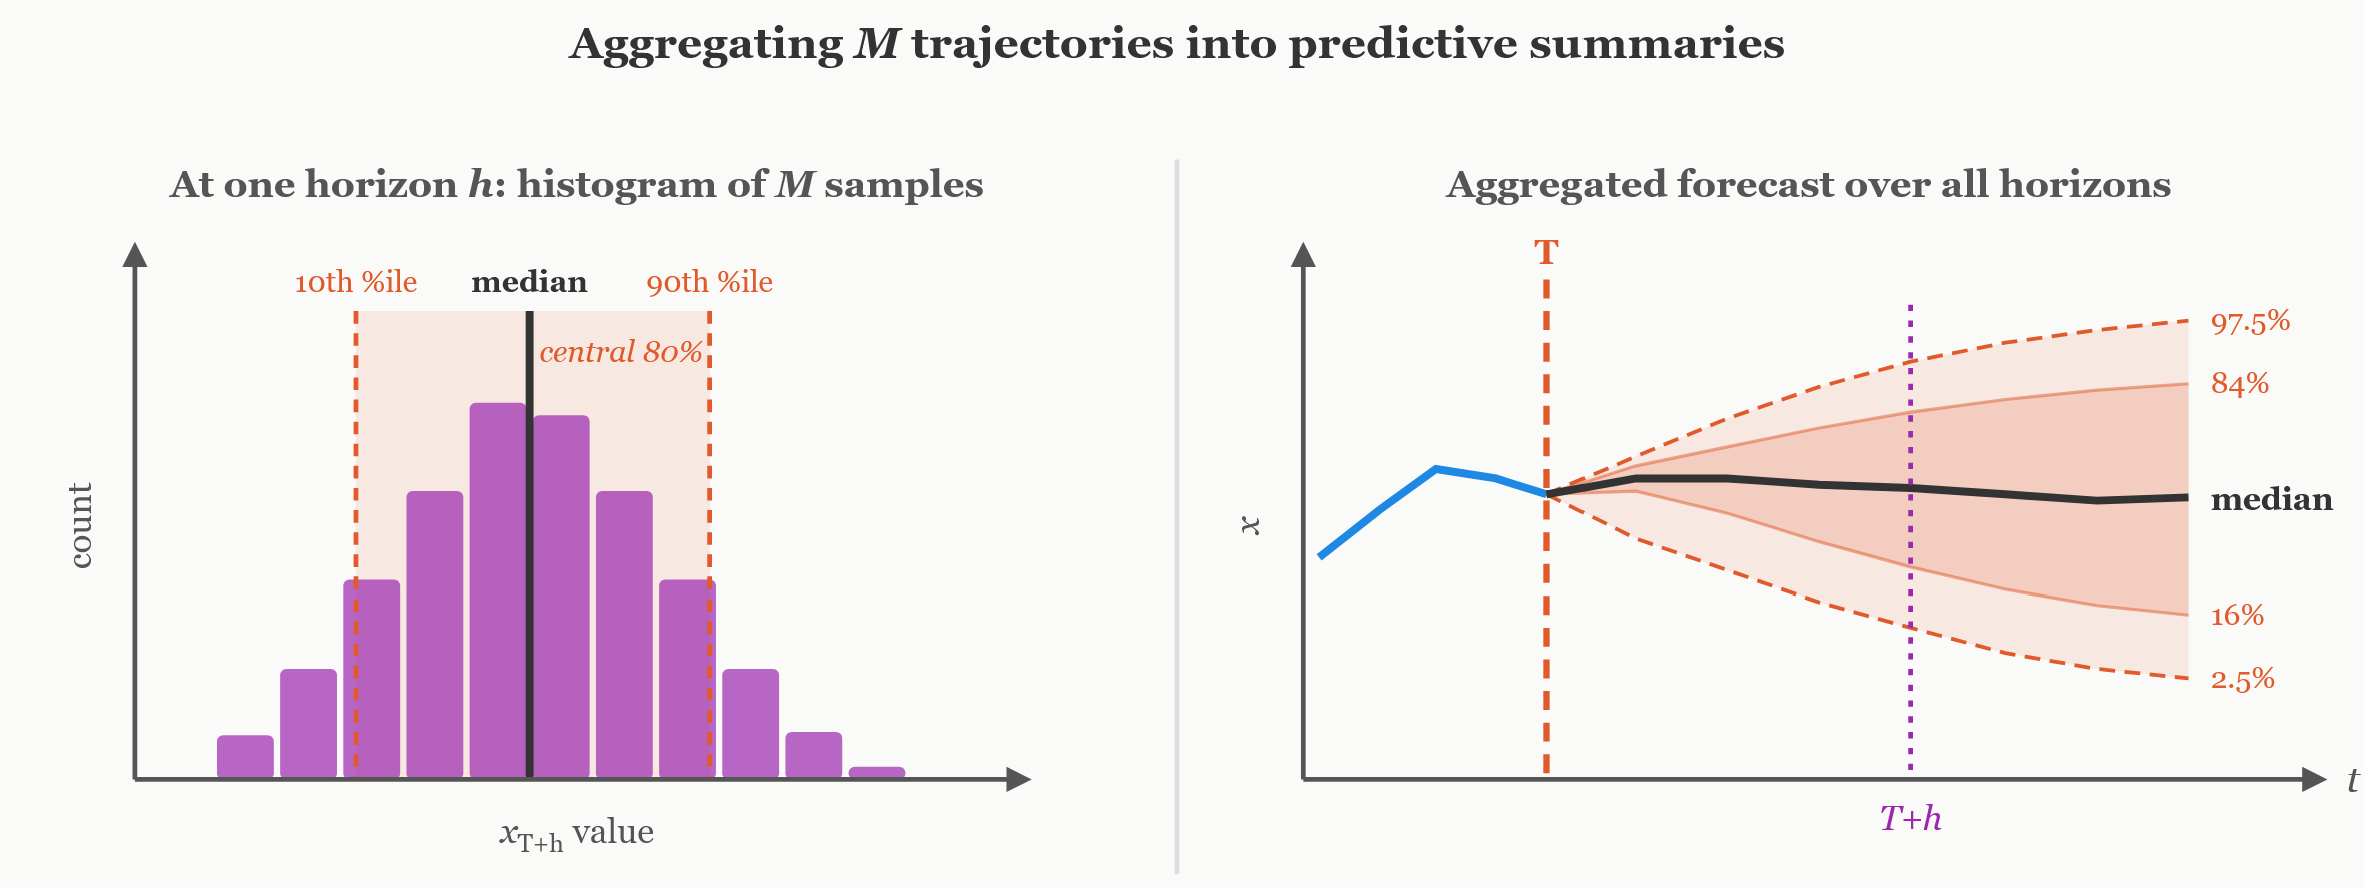
Exceedance probabilities. Remember the alarm threshold from Part I? With trajectories, estimating the probability of crossing it is trivial: count how many cross it, divide by . If 35 out of 500 cross at some point during the horizon, your estimated exceedance probability is 7%. No closed-form integral needed.
The key property of all these summaries: at early horizon steps, the trajectories cluster tightly, so bands are narrow. At late horizon steps, the trajectories have fanned out, so bands are wide. The widening happened naturally from the compounding randomness, you didn’t tune anything, you just sampled honestly.
···
QA the forecast I: the coverage-horizon plot
One example is anecdotal. The real test: run both rollout strategies from many starting points in the test set, and check whether the 90% band actually contains the true value about 90% of the time, at every horizon step.
For each test window with true future , compute the band from each strategy and check:
Average over all test windows:
For a calibrated forecast, at every horizon .
Now plot as a function of coverage on the -axis, horizon on the -axis. This single plot tells you almost everything:
-
Flat line near 90%: the rollout is well calibrated. The bands are honest at every horizon. This is what you want.
-
Line that drops as grows: the bands are too narrow at long horizons. The model is overconfident about the distant future. This is the classic signature of deterministic rollout, it misses the propagated uncertainty, so even by step 50 the band is far too tight.
-
Line that rises as grows: the bands are too wide. The model is overly cautious.
In the companion notebook, the contrast is stark. The deterministic rollout’s coverage crashes below 50% within a few steps and keeps falling, by step 50, it’s barely above chance. The stochastic rollout holds roughly stable across the full horizon. Same model, same context, same trained weights, one line of code changed. That one line, replacing mu with sample in the context append is the difference between a forecast you can trust and one that’s silently lying about its confidence.
QA the forecast II: the PIT histogram
The coverage plot tells you “are the bands the right width?” The Probability Integral Transform (PIT) tells you something richer: is the entire predicted distribution correct, not just the width?
For each test window and horizon step , compute the fraction of trajectories that fell below the true value:
This is the empirical quantile of the truth within the ensemble. If the truth landed right in the middle, . If almost all trajectories were below the truth, .
Key property: if the ensemble is perfectly calibrated, should be uniformly distributed on . The truth should land in the bottom 10% of trajectories about 10% of the time, in the middle 10% about 10% of the time, in the top 10% about 10% of the time. Collect values across all test windows and all horizons, and plot a histogram. The shape is the diagnosis:
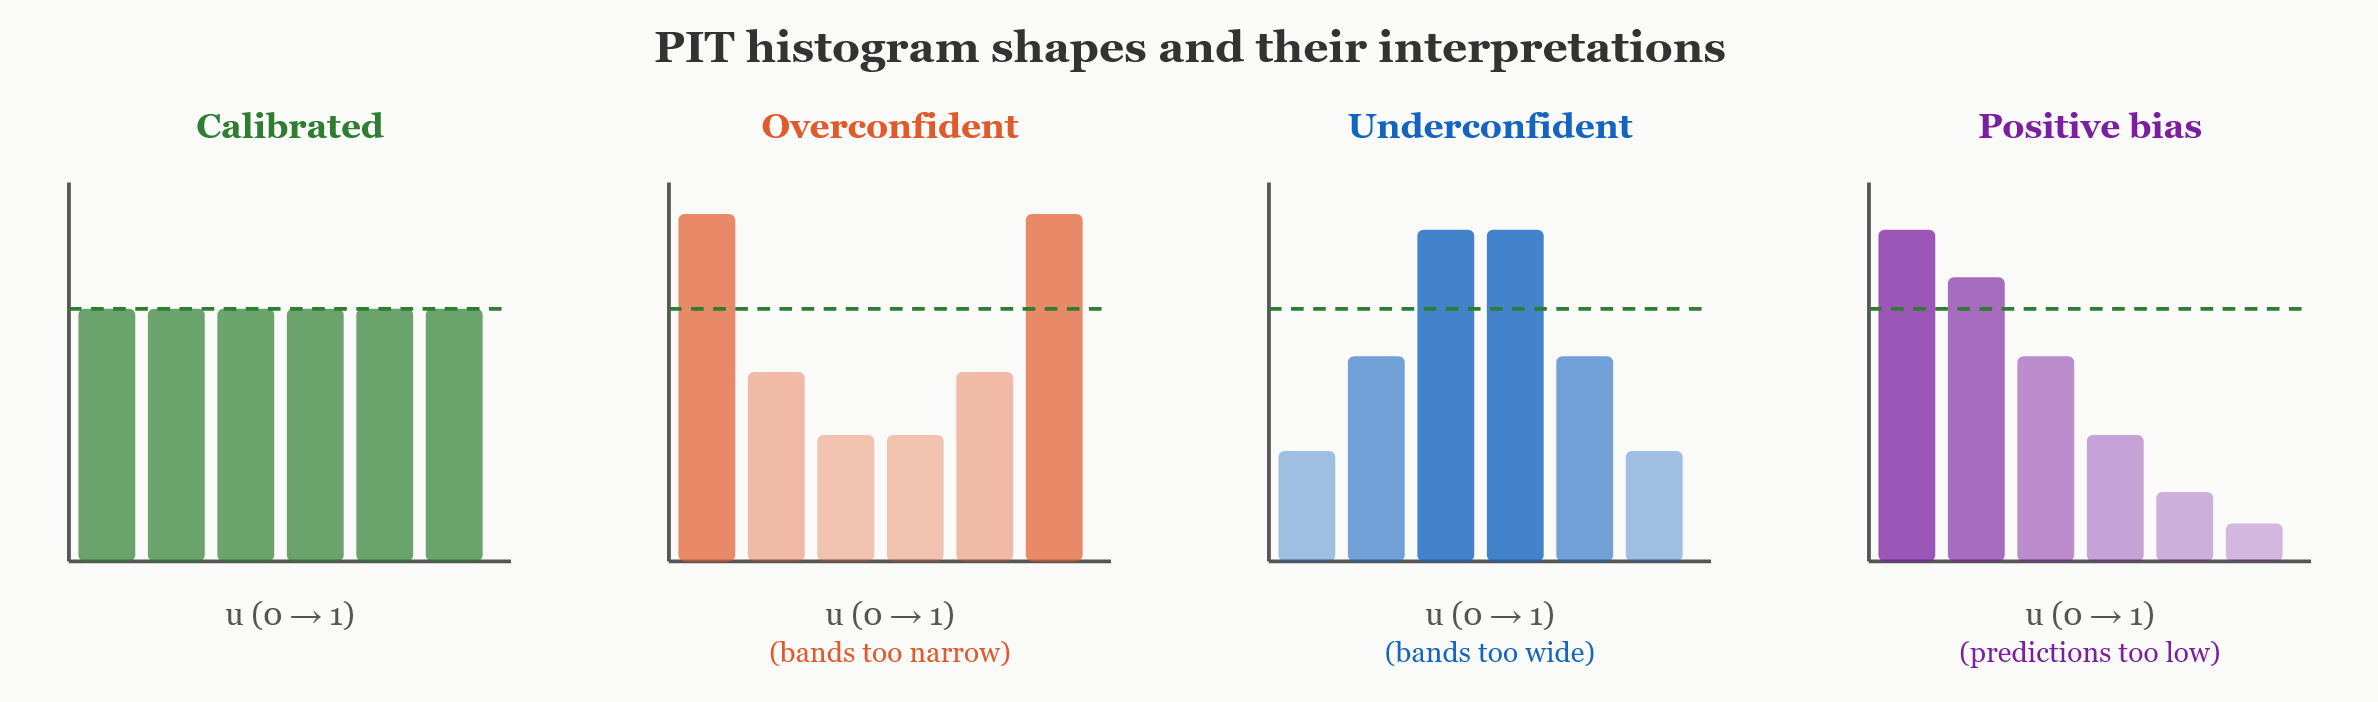
PIT histogram shapes
One histogram, four possible diagnoses. In the accompanying notebook, the deterministic rollout produces a dramatic U-shape, the truth is in the extreme tails far more often than it should be, because the bands are too narrow. The stochastic rollout is much flatter.
···
Practical Considerations
Keep the clamp during rollout
During rollout, the model feeds on its own outputs, data it never saw during training. This is distribution shift: the inputs look different from training data because they’re the model’s own predictions, not real observations.
In this unfamiliar setting, can drift to extreme values. Without the same clamp used during training, a single unlucky trajectory might produce a wild sample that drives to zero (infinite confidence, gradient explosion) or infinity (total ignorance) at the next step. That corrupts the trajectory, and if it happens early, every subsequent step is garbage. The fix is actually trivial, just apply the same clamp you used during training:
If this clamp is already in your model’s forward() method (as it should be from Part I), you don’t need to change anything. Just don’t remove it for inference.
Single-step head vs multi-step heads
Some architectures include multi-step prediction heads (such as DeepSeek or SeismoGPT), auxiliary outputs that directly predict the distribution at horizons 2, 3, …, from the current context, without rolling out. These are useful during training as regularisers and give fast marginal distributions at each horizon. But marginal is the key word. A marginal distribution at step tells you the spread of by itself. It does not tell you how relates to , or how they move together. There’s no joint distribution, no coherent trajectories.
Only the autoregressive stochastic rollout produces a joint distribution, actual sequences where each step depends on the previous one. That’s what you need for:
-
Coherent trajectory sampling (a single plausible future)
-
Exceedance probabilities over windows of time (“will the threshold be crossed sometime in the next hour?”)
-
Correct quantile bands that account for compounding uncertainty
The right approach: use the single-step head plus Monte Carlo rollout for inference. Treat multi-step heads as training auxiliaries, not inference tools.
Batching is key for speed
The stochastic rollout processes all trajectories as a single batch of shape one forward pass per horizon step. This is important. separate forward passes of shape would give the same result but be dramatically slower, especially on a GPU where the kernel launch overhead dominates for small models.
On the synthetic signal from Part I (transformer with 32-dimensional embeddings, 2 layers, 4 heads), 500 trajectories over 50 steps runs in about 2 seconds on a CPU. Scaling to real models and longer horizons, the batched approach stays efficient.
···
What this does not guarantee
The stochastic rollout propagates uncertainty correctly, but only the uncertainty the model has learned to express. If the one-step model is miscalibrated (its is systematically too small or too large), the rollout faithfully propagates that miscalibration. Garbage in, garbage out.
This is why the diagnostics from Part I still matter. The one-step model must be well calibrated first, honest at every individual step, before rolling it forward. The coverage-horizon plot and PIT histogram then tell you whether the rollout introduced additional problems on top of that.
There’s also the question of distribution shift during rollout: the model was trained on windows of real data, but during multi-step inference it’s feeding on its own predictions. If the model’s predictions drift for example, if the mean trajectory slowly diverges from the true signal dynamics, the later context windows look increasingly unlike anything the model saw during training. The model might still output reasonable-looking , but the quality degrades. This is a real problem, especially at very long horizons, and it’s why multi-step training losses (training the model on its own rollout outputs, not just on real data) can help.
There’s also a deeper assumption we haven’t questioned: the predictive distribution at each step is Gaussian. The rollout propagates whatever the one-step model outputs, but if the true noise is skewed, heavy-tailed, or multimodal, even a perfectly calibrated Gaussian is fitting the closest bell curve to a non-bell-curve reality. The mean and variance might be right, but the shape is wrong and shape matters for tail probabilities and threshold crossings.
We’ll revisit these concerns in future articles.
···
Conclusion
One-step prediction gives you a distribution over one value. Multi-step prediction needs a distribution over entire sequences. The chain rule says you can build it one step at a time, but only if you propagate uncertainty correctly through the chain.
Deterministic rollout (feed back) treats each intermediate prediction as certain. This captures only the local noise at each step and ignores the inherited uncertainty from all previous steps. The law of total variance guarantees that this underestimates the true forecast variance, and the underestimation compounds at every step. Coverage degrades with horizon.
Stochastic rollout (sample and feed back, times) lets uncertainty compound naturally through the autoregressive loop. Different trajectories diverge because of the randomness at each step, and the spread of the ensemble at any horizon step reflects both the local noise and all the accumulated propagation. Coverage stays honest.
The difference in code is one line. The difference in forecast quality is fundamental.
The coverage-horizon plot and the PIT histogram are the tools that tell you whether your multi-step forecast is calibrated. They apply regardless of the model architecture, the distribution family, or the signal domain. If you’re producing probabilistic forecasts at any horizon longer than one step, you need both.
And there’s a deeper point here. We started this series asking “should I worry about this prediction?” Part I gave the model a voice, a way to express uncertainty at a single step, through . Part II gave that voice a memory, a way to carry uncertainty forward over an extended future, through stochastic sampling. But listen to what that voice is actually saying. At every step it says: “I think the next value is drawn from a bell curve with this center and this width.” A bell curve. Symmetric, unimodal, light-tailed.
Some signals don’t fit that shape. For instance, a seismic signal can have sudden regime changes that create multimodal futures. For all of these, a single Gaussian per step is too rigid, no matter how well you propagate it. That’s where richer predictive distributions, quantized tokens, mixture models, flow matching become essential. The rollout machinery stays exactly the same (sample and feed back, times), but the one-step distribution becomes expressive enough to capture the full complexity of what might happen next. That’s where the next part of this series begins.
···
References
[1] M. Seitzer, A. Tesch, N. Rasiwasia and G. Martius, On the Pitfalls of Heteroscedastic Uncertainty Estimation with Probabilistic Neural Networks (2022), ICLR 2022
[2] W. Esmail, S. Russell, J. Klinge, A. Kappes and C. Thomas, Data-Driven Forecasting of three-Component Seismograms Using Transformer Architectures (2026), arXiv:2606.02912