

In 2022, a small team of researchers ran an experiment that should have been unremarkable. They trained a tiny neural network, far smaller than anything that gets called “AI” today, on one of the simplest tasks imaginable: modular addition, basically clock math. What is 8 plus 7 if the clock only goes up to 12? The answer is 3.
The network learned this almost immediately. Within a thousand training steps it was answering every practice question correctly.
Then the researchers tested it on questions it had never seen before. It did barely better than guessing.
That part isn’t surprising. It’s a familiar failure in machine learning: the model had memorized the answer key instead of learning the rule behind it. Normally, that’s where the story ends. Except the researchers kept training the model well past the point most people would call it finished. Thousands more steps. Then tens of thousands.
At some point, with no new data and nothing visibly different about the setup, the model’s performance on the unseen questions jumped from barely better than random to nearly perfect. At 1,000 steps it scored perfectly on training data but only about 10 percent on new problems. By 20,000 steps, it scored close to 100 percent on both, with no change to how it was being trained in between [1].
It had been sitting there, looking finished by every normal measure, quietly turning into a completely different kind of model. The researchers named this grokking.
Cramming versus actually understanding
An analogy that captures it well: picture a student who crams the night before a test. They can answer yesterday’s practice questions perfectly. Give them a new question that tests the same idea in a slightly different form, and they freeze, because they memorized answers rather than the concept underneath them.
Now imagine that student keeps studying anyway, not new material, just the same material again and again. Weeks later, something clicks. They stop recalling flashcards and start actually understanding the topic well enough to solve problems they’ve never seen.
That’s roughly what grokking looks like from the outside. The strange part is the timing. The click happens long after the student appears finished. Stop watching them right when their quiz scores plateau, and you’d conclude they’re a memorizer and move on, with no way of knowing that real understanding was still forming underneath.
What was actually happening during that quiet stretch
This is the part that turns grokking from a curiosity into something worth paying attention to, because researchers didn’t just observe the effect. They opened the network up and reverse engineered what it was doing at each stage, similar to taking apart a watch to look at the gears.
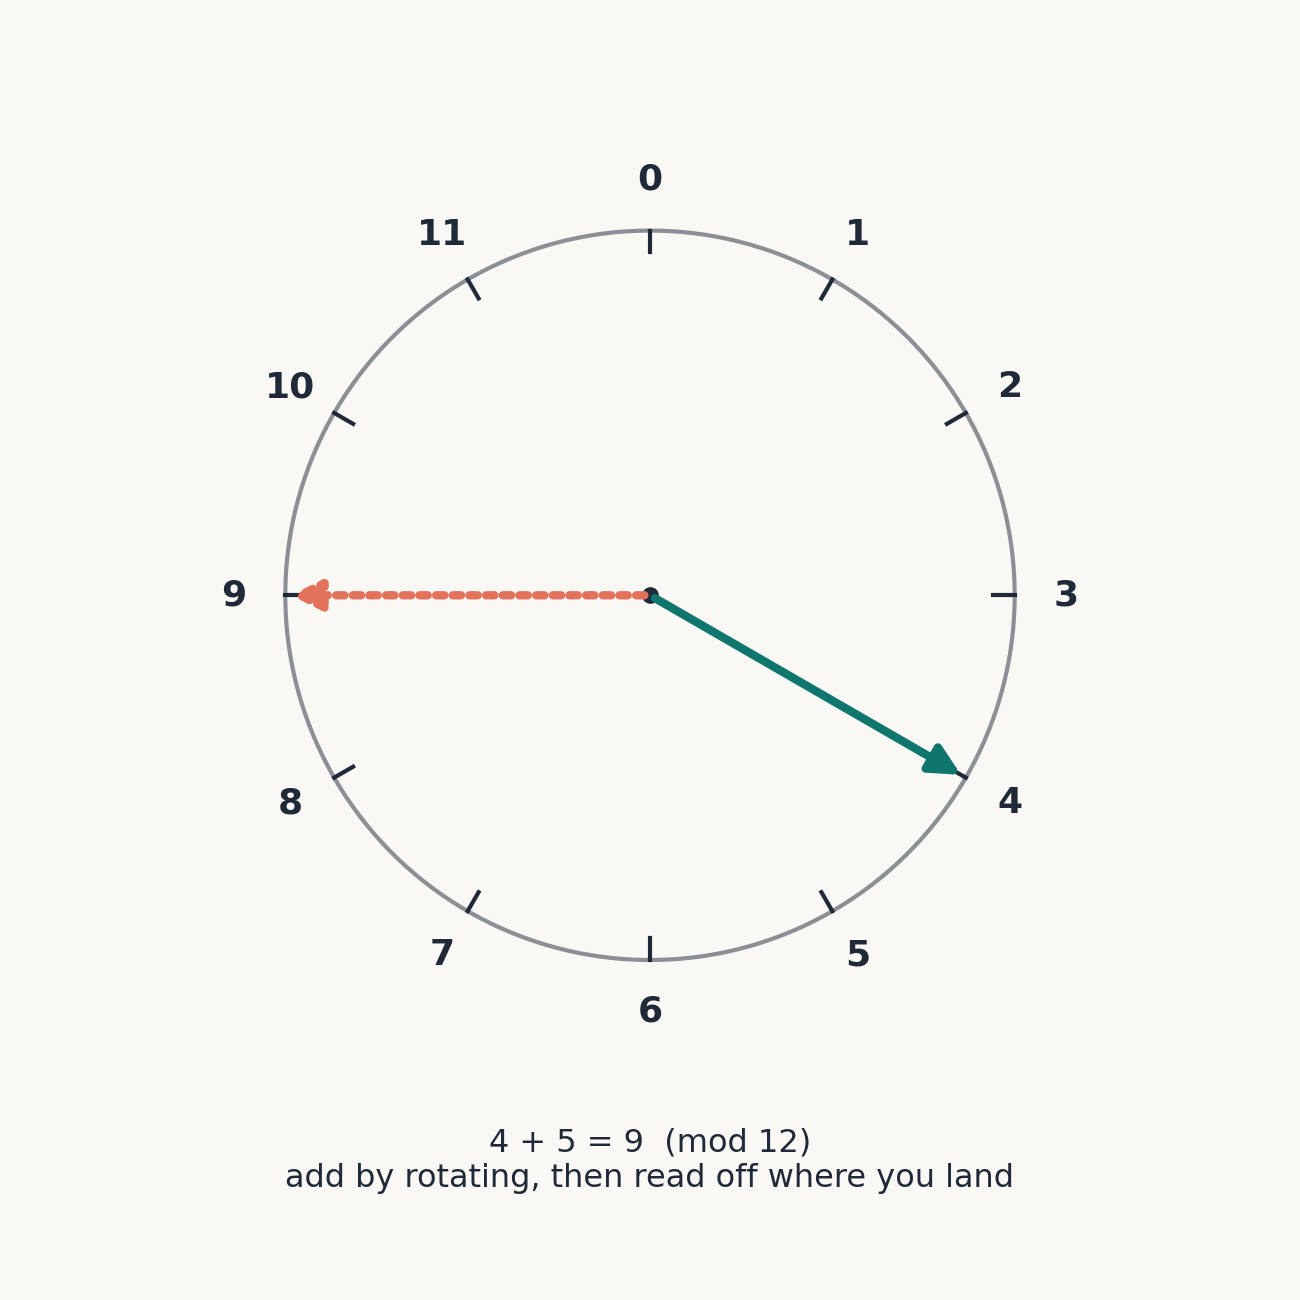
A follow-up study in 2023 found something unexpectedly elegant. The network had taught itself to represent numbers as positions around a circle, then combined those positions using the mathematics of rotation, essentially rediscovering trigonometry to solve clock math without anyone showing it what trigonometry was [2].
Picture an actual clock face. The network learned to place each number at a point around the circle. Adding two numbers became a matter of rotating to one position, rotating again by the second amount, and reading off wherever the hand landed. It’s a clean, genuinely generalizable method, the kind a mathematician might design on purpose. Nobody built it in. Gradient descent found it on its own.
Building that circular structure took time. For a long stretch, two solutions existed side by side inside the same network: a memorized shortcut that worked on familiar questions but nowhere else, and a real, general method still being assembled piece by piece underneath it. The general method only took over once it was complete enough to outcompete the memorized one. From outside the network, that construction phase looked like nothing happening at all. From inside, it was the entire story.
Why a flat line doesn’t mean nothing is happening
This detail is worth sitting with. If you only watch the scoreboard, accuracy on training data and accuracy on new data, grokking looks like a long flat stretch followed by a sudden cliff. Anyone judging progress from the outside would give up right before the interesting part begins. That’s close to what would have happened here under a standard early stopping rule, the kind built into most training setups specifically to save time by cutting off models that appear to have stopped improving.
That raises a question worth taking seriously well beyond toy math problems. How many times has something like this happened quietly in larger, more important models, and simply been switched off before anyone noticed the click coming?
Nobody has a full answer yet. Grokking has since been documented in a handful of other narrow, rule-based tasks, but whether anything similar happens invisibly inside today’s much larger models is still an open question. It’s one of the stranger implications of the whole phenomenon: memorization and real understanding can look identical from the outside, right up until the moment they stop looking identical.
Where the name comes from
Grokking is borrowed from Robert Heinlein’s novel Stranger in a Strange Land, where it describes understanding something so completely that you absorb it intuitively rather than simply knowing it. It’s an odd word to attach to a math experiment, but it fits. The model didn’t get gradually better at faking the right answer. At some specific, hidden point, it stopped faking and started knowing.
The lesson here isn’t really about transformers or modular arithmetic. It’s that understanding doesn’t always look like understanding while it’s still forming. Sometimes it looks like nothing at all, right up until it doesn’t.
···
[1] A. Power, Y. Burda, H. Edwards, I. Babuschkin and V. Misra, Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets (2022), arXiv:2201.02177
[2] N. Nanda, L. Chan, T. Lieberum, J. Smith and J. Steinhardt, Progress Measures for Grokking via Mechanistic Interpretability (2023), ICLR 2023